Promptify: Pydantic schemas over a LiteLLM backend, with litellm pinned to a ceiling
Prompt Engineering | Prompt Versioning | Use GPT or other prompt based models to get structured output. Join our discord for Prompt-Engineering, LLMs and other latest research
At a glance
- What is it?
- Promptify presents itself as a task-based NLP engine, scikit-learn for LLM powered NLP, where the unit of work is a Pydantic model rather than a prompt string. Twelve built-in tasks return typed results, any provider is reached by changing the model string, and the one dependency decision worth reading is `litellm>=1.50.0,<=1.82.6`, a range with a hard ceiling.
- Who is it for?
- Adopt Promptify if you want typed extraction and classification results from an LLM without hand-rolling a JSON schema, a prompt and a parser, and if you are willing to let a library own that layer. Do not adopt it if you need the newest LiteLLM release, since the dependency carries an upper bound, or if you want model confidence treated as a measurement, since the schemas carry whatever the model returned.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
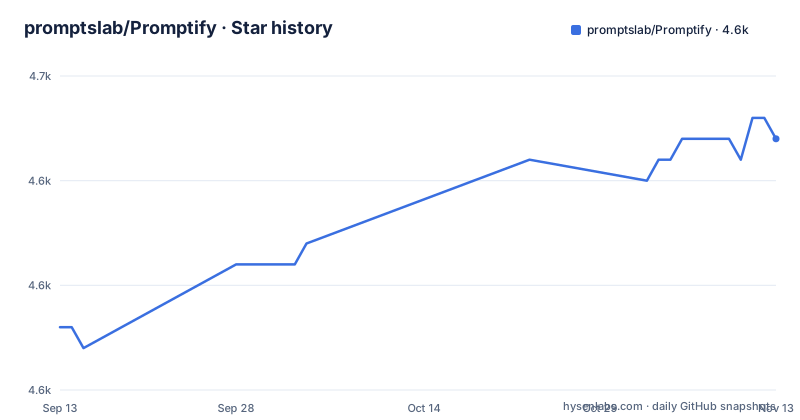
Star history
- promptslab/Promptify4,647 ★ · +9
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| promptslab/Promptify | 4.6k | 4.6k |
9 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A Pydantic model is the whole interface
The custom task example is the clearest statement of the design. You define a schema and hand it to `Task`:
from promptify import Task
from pydantic import BaseModel

class MovieReview(BaseModel):
    sentiment: str
    rating: float
    key_themes: list[str]

task = Task(model="gpt-4o", output_schema=MovieReview, instruction="Analyze this movie review.")
review = task("Nolan's best work. Stunning visuals but the plot drags.")
# MovieReview(sentiment="mostly positive", rating=7.5, key_themes=["visuals", "pacing"])
The return value is a `MovieReview` instance, not a string you have to parse. That is the feature list's phrase type-safe results, not raw strings, and it is the reason the library compares itself to scikit-learn: the schema plays the role an estimator class plays, so validation happens at the boundary instead of in your downstream code.
Switching provider means editing one string
The provider abstraction is LiteLLM, and it is entirely visible in the constructor:
ner_openai = NER(model="gpt-4o-mini")
ner_claude = NER(model="claude-sonnet-4-20250514")
ner_local  = NER(model="ollama/llama3")
The same task class runs against a hosted model, a different vendor's model, and a local Ollama model, with no code change. The feature list names OpenAI, Anthropic, Google, Ollama, Azure and 100 or more, which is LiteLLM's reach rather than Promptify's own integration work. The cost is in the dependency range: `litellm>=1.50.0,<=1.82.6`. A ceiling that tight means a new LiteLLM release cannot be picked up until Promptify widens it, which is a deliberate trade of currency for stability and the one to check before you upgrade.
Eleven built-in tasks and one escape hatch
The task table is the feature list in compact form:
| Task | Class | Output Schema | |------|-------|---------------| | Named Entity Recognition | `NER` | `NERResult` (list of `Entity`) | | Binary Classification | `Classify` | `Classification` | | Multiclass Classification | `Classify` | `Classification` | | Multilabel Classification | `Classify(multi_label=True)` | `MultiLabelResult` | | Question Answering | `QA` | `Answer` | | Summarization | `Summarize` | `Summary` | | Relation Extraction | `ExtractRelations` | `ExtractionResult` | | Tabular Extraction | `ExtractTable` | `ExtractionResult` | | Question Generation | `GenerateQuestions` | list of `GeneratedQuestion` | | SQL Generation | `GenerateSQL` | `SQLQuery` | | Text Normalization | `NormalizeText` | normalized text | | Topic Modelling | `ExtractTopics` | list of topics | | Custom Task | `Task` | any Pydantic `BaseModel` |
Two rows are worth pausing on. Multilabel classification is the same `Classify` class with `multi_label=True` and a different result type, so labels are a constructor argument rather than a subclass. And the last row is the important one: when the built-ins run out, `Task` takes any schema you write, which is what keeps the library from being a fixed set of wrappers.
Accuracy levers are the domain argument and few-shot examples
The examples show what the output objects carry. Named entity recognition returns `Entity` records with a text and a label, and passing `domain="medical"` changes the prompt context; the sample text yields labels such as `AGE`, `CONDITION` and `SYMPTOM`. Classification returns `Classification(label="positive", confidence=0.95)`, and question answering returns `Answer(answer="Ulm", evidence="Einstein was born in Ulm", confidence=0.98)`, so an answer carries the sentence it came from. The feature list names the two documented ways to improve accuracy: few-shot examples you can add, and the domain argument for context aware prompts. Everything else about quality is up to the model, since no training data is required and none is used.
Batch and async are the same object
Concurrency is not a separate API. Batch processing is one call with a concurrency limit:
results = ner.batch(["text1", "text2", "text3"], max_concurrent=10)and the feature list is explicit that the async concurrency happens under the hood, so you are not writing a gather over per-item coroutines yourself. Single-item async is the `acall` method:
result = await ner.acall("Patient has diabetes")which is native await support. Cost tracking rides along with the same object through `get_cost_summary()`, which reports token usage and cost, so a batch job can be checked after the fact rather than estimated in advance. The remaining feature is the safe parser: for providers without native structured outputs, it falls back to a JSON completion and does not use `eval()`, which is the specific implementation choice worth knowing about.
Evaluation is an extra with rouge-score and nltk behind it
The evaluation framework lives in a separate import and a separate extra. Installation is:
pip install promptify[eval]and the manifest puts `rouge-score>=0.1` and `nltk>=3.8` in that group, which is why the base install stays small. Calling it:
from promptify.eval import evaluate

scores = evaluate(task=ner, dataset=labeled_data, metrics=["precision", "recall", "f1"])
# {"precision": 0.92, "recall": 0.88, "f1": 0.90}
The metric list is longer than the example: precision, recall, F1, accuracy, exact match and ROUGE. A dataset of labelled examples is required, so evaluation is the part of this library that asks you to do the labelling work.
A version file, strict typing and an async test mode
The project metadata is ordinary and readable. The build uses hatchling, the version is dynamic and read from `promptify/_version.py`, the licence is Apache-2.0, and the classifiers cover Python 3.9 through 3.13 with a Beta development status. The runtime dependencies are four: LiteLLM, Jinja2, Pydantic 2 and Tenacity for retries. Development adds pytest, pytest-asyncio, ruff and mypy, and the configuration is strict in two places: mypy runs with `warn_return_any`, `warn_unused_configs` and `disallow_untyped_defs`, and ruff is set to py39 with a line length of 100 and the E, F, I, W rule sets. Pytest runs with `asyncio_mode = "auto"` and `testpaths = ["tests"]`. The tree also holds `benchmarks/`, `notebooks/`, `docs/`, `assets/`, an `examples/` directory with a `medical_ner.py` script, and, at the root, a committed `.DS_Store` that has no business being in version control. There are no GitHub releases, so the version you get is whatever the wheel says, and the last recorded push is dated 2026-03-27. The README also carries a BibTeX citation block crediting Promptify to Ankit Pal in 2022, which dates the project's origin before most of the models it now calls.
Editorial conclusion
Adopt Promptify if you want typed extraction and classification results from an LLM without hand-rolling a JSON schema, a prompt and a parser, and if you are willing to let a library own that layer. Do not adopt it if you need the newest LiteLLM release, since the dependency carries an upper bound, or if you want model confidence treated as a measurement, since the schemas carry whatever the model returned. Verify first your Python version against the 3.9 floor, and install `promptify[eval]` up front if you intend to score results rather than eyeball them.
Frequently asked questions
Is Promptify suitable for beginners?
The library's own claim is two or three lines of code for any NLP task with no training data required, and it ships built-in tasks for named entity recognition, binary, multiclass and multilabel classification, question answering, summarization, relation extraction and SQL generation. Anything beyond those uses your own Pydantic schema.
How do I install and use Promptify?
Install with pip install promptify on Python 3.9 or newer, or from source with pip install git+https://github.com/promptslab/Promptify.git. Add pip install promptify[eval] for the evaluation metrics, then import a task class such as NER, Classify or QA and pass it a model string like gpt-4o-mini.
What is Promptify?
A task-based NLP engine with Pydantic structured outputs, built-in evaluation and LiteLLM as the universal LLM backend, which the README compares to scikit-learn for LLM powered NLP. Results come back as typed Pydantic objects rather than raw strings.
Which LLM providers does Promptify support?
Any provider LiteLLM reaches, including OpenAI, Anthropic, Google, Ollama, Azure and 100 or more. You switch by changing the model string, for example claude-sonnet-4-20250514 for Anthropic or ollama/llama3 for a local model.
Does Promptify include evaluation metrics?
Yes, an evaluation framework covering precision, recall, F1, accuracy, exact match and ROUGE. It ships as an extra, installed with pip install promptify[eval], which pulls in rouge-score and nltk, and it needs a dataset of labelled examples.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/promptslab-promptify)Star history chart for your README
[](https://hysenlabs.com/projects/promptslab-promptify)Was this useful?