go-stress-testing: a goroutine-per-user load generator for Go services
A load-testing tool implemented in Go, with an introduction to ab, Locust and JMeter - includes a practical case study stress-testing 1 million connections on a single machine.
At a glance
- What is it?
- A single-binary HTTP and gRPC load generator that spends one goroutine per simulated user and prints qps and latency every second. Useful for capacity maths against servers you own, blunt as a general scripting platform.
- Who is it for?
- Adopt go-stress-testing if you own the target server and want a single binary, no scripting language and no web interface between you and a throughput number for a uniform HTTP or gRPC endpoint. Skip it if the workload needs sequenced requests, authentication steps or a load curve that changes mid run, because all three of those need the scripting model Locust and JMeter provide.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 55 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
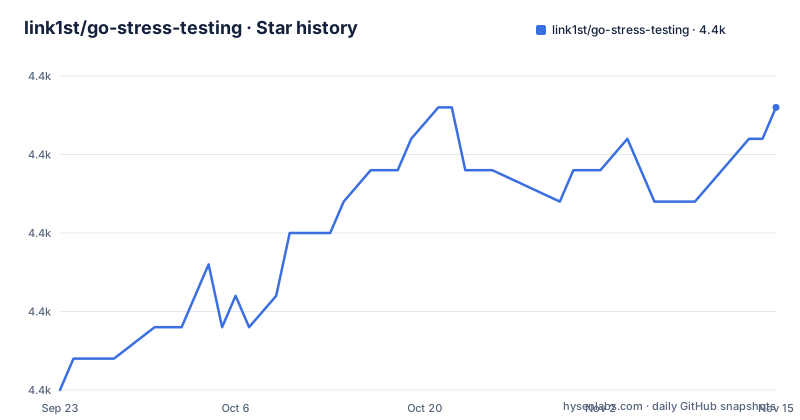
Star history
- link1st/go-stress-testing4,409 ★ · +9
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| link1st/go-stress-testing | 4.4k | 4.4k |
9 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One goroutine per simulated user is the whole design
The tool models load as concurrency rather than as a request rate. Every simulated user gets its own goroutine, and each goroutine loops issuing requests until its share of the work is done. That choice is what makes a single machine able to hold a large number of open connections, and it is also what makes the numbers hard to interpret, because goroutines are cheap and the network is not.
The measured output is a table printed once per second. Each row carries elapsed time, concurrency, success count, failure count, qps, longest latency, shortest latency and average latency, plus a column that accumulates response codes and how often each one came back. Nothing in that table is a percentile. Longest and shortest are running extremes over the entire run, so one slow DNS lookup at the start will sit in the maximum column for every subsequent second and quietly distort your reading of the run.
For engineers working out how many machines a service needs, the unit that matters is qps, and the tool reports it directly each second. The README pairs that with a sizing formula: take daily page views, multiply by 0.8, divide by 86400 seconds times 0.2, and you have the peak second request count. Its worked example gives roughly 1389 qps, and dividing that by a measured 69 qps per machine yields about 20 machines. The arithmetic is the tool's real contribution; the generator is how you get the 69.
-c, -n and the multiplication that decides your run length
Three flags carry the basic run shown in the README. -c sets concurrency, which is also the number of goroutines started. -n sets how many requests each concurrent goroutine issues, so the total request count is concurrency multiplied by per-goroutine count, exactly as the parameter notes state. -u is the address under test.
The consequence is that, with these three flags, run time is not set directly. A run ends when the last goroutine finishes its count, which means a miscalculated -c and -n pair can keep a load running against a service far longer than you intended. If you want ten seconds of traffic, you have to pick numbers whose expected latency divides your request budget correctly, and the tool will not tell you when you got it wrong until it stops printing.
Connection handling is the other half. The README describes support for both HTTP 1.1 and HTTP 2.0 persistent connections, and notes that a simple extension can add support for a private protocol. That extension path is worth weighing before you adopt: the goroutine loop is the reusable piece, but each transport still needs its own request construction.
Reading the per-second table without fooling yourself
The result block is the tool's primary output and it rewards careful reading. Success and failure counts are cumulative across the row sequence, not per-second deltas, so a run that reports 46 successes at six seconds has issued 46 requests in six seconds, not 46 in the last second. The qps column is the per-second rate, which is why it hovers near 8 while the success column climbs by roughly eight each row.
The error code column packs status code and count together, as in the 200:8 and 200:15 entries shown in the sample output. During a sustained run that column grows into a small set of entries, and it is the fastest way to see whether failures are concentrated in one status or spread across several. A run against a service that sheds load under pressure tends to show the error entries clustering while the qps column stops climbing, which is more informative than any latency figure in the table.
What the table cannot do is attribute a latency distribution, isolate client-side timeouts from server timeouts, or exclude connection setup from the measurement for short-lived runs. There is no histogram and no percentile field.
Two installation routes, and what each one costs
The README gives two routes and the choice is about build environment rather than convenience. With a Go toolchain present, installation is a single go install of the module path, and the binary lands in the directory reported by the Go bin environment variable. The binary name differs from the module path, so once installed the command is shorter than what you installed.
go install github.com/link1st/go-stress-testing@latestWith no Go environment, the project publishes prebuilt binaries per platform through its download page, and the macOS build carries a platform suffix in its filename. That difference matters for scripts: the go-installed binary and the downloaded one are not invoked with the same command string.
./go-stress-testing-mac -c 1 -n 100 -u https://www.baidu.com/That run asks for one concurrent goroutine issuing 100 requests against the given URL. Each second the terminal prints one table row, and after the last request the tool prints the accumulated result. Replace the address with a host you own. The README lists gRPC load testing among its features, and the repository has top-level curl, helper, model, proto, server, tests and tools directories.
go.mod requires Go 1.25 while the Dockerfile builds on 1.17
Here is the contradiction worth catching before you build your own image. The module file declares go 1.25.0, while the container build starts from golang:1.17, disables cgo and cross-compiles a linux amd64 binary. A toolchain older than the version the module declares will refuse the build or demand a download, so the checked-in Dockerfile is behind the module requirement and will need its base image bumped before it produces a working binary.
The rest of the Dockerfile is a container that does not run the tool. It copies the compiled binary into an ubuntu layer, sets the entrypoint to sleep for ten hours, and leaves it there. That shape suits a load generator, since a container whose main process is the load would exit the moment the run ends.
Dependencies are light and tell you what the tool actually touches: a shell-word parser, the extended net stack for HTTP 2, gRPC and protobuf for the gRPC target, and a radius library, which is the one dependency with no obvious counterpart in the HTTP path. The last tagged release was v1.0.18 on 2026-01-07, and the last push to the repository was on 2026-09-21.
Against ab and Locust, the difference is where the logic lives
ApacheBench ships with the Apache server and is a fixed command line with no scripting, which makes it a reasonable sanity check for a plain HTTP endpoint. go-stress-testing sits closer to ab in spirit: it is a binary you point at one URL with three flags, and it will not model a user journey.
Locust differs structurally. It is a Python tool where the workload is a Python class you write, so request sequence, think time and per-user behaviour live in code rather than in a flag, and the fleet is coordinated by a web interface with workers. go-stress-testing inverts that: the workload is fixed by arithmetic in -c and -n, there is no scripting layer and no web interface, and the entire run is one process on one machine. If your load needs to log in, hold a token and then hit an authenticated endpoint in order, the scripting model is what you are buying, and this tool does not sell it.
Both approaches also differ in how much machinery sits between you and the traffic. A single-process generator is easier to point at a box you own and easier to reason about for raw throughput, and harder to use when you need several machines to generate the traffic shape.
Nothing in the tool stops you from aiming it at someone else's host
Read the feature list plainly. There is no target allowlist, no rate ceiling, no consent check and no domain restriction. Give it -u with someone else's address and it will send the traffic. The README frames the 1-million-connection exercise as a system tuning exercise with kernel tuning, client configuration and measurement, and the surrounding chapters are a primer on capacity planning for services you deploy, but the binary enforces none of that framing.
That absence is normal for a load generator and it is your responsibility, not a defect to report. It does mean the adoption decision includes the operational question of who is allowed to run it and against what addresses. The README's own kernel tuning and client configuration steps change host limits, which affects everything else on the machine, so an accidental target is not the only risk in a misconfigured run.
A second limit is narrower and easier to hit. With only -c, -n and -u, a workload is uniform: same method, same path, same headers, repeated. Any service that is cheap under one uniform endpoint and expensive under a realistic mixed path will look far healthier here than it is. The HTML test report and its scoring section is the reporting answer to that problem, not the workload problem.
Editorial conclusion
Adopt go-stress-testing if you own the target server and want a single binary, no scripting language and no web interface between you and a throughput number for a uniform HTTP or gRPC endpoint. Skip it if the workload needs sequenced requests, authentication steps or a load curve that changes mid run, because all three of those need the scripting model Locust and JMeter provide. Before the first run, do the request count arithmetic yourself: -c multiplied by -n is the total request count. Confirm also that the server under test is one you are permitted to load, since the binary applies no restriction to the -u address.
Frequently asked questions
How do I install go-stress-testing without a Go toolchain?
The project publishes prebuilt binaries for macOS, Linux and Windows through its GitHub releases page, and the macOS build is invoked with a platform suffix such as ./go-stress-testing-mac. With a Go toolchain present, the documented route is go install github.com/link1st/go-stress-testing@latest, which places the binary in the directory reported by the Go bin environment variable.
What do the -c and -n flags mean in go-stress-testing?
-c sets the concurrency, which is also the number of goroutines started. -n sets how many requests each concurrent goroutine issues, and the total request count for the run is concurrency multiplied by per-goroutine count. -u supplies the address under test.
Does go-stress-testing report latency percentiles?
The once-per-second table does not: it reports longest latency, shortest latency and average latency only, with no percentile or histogram field. The longest and shortest values are running extremes across the run, so a single slow request stays in the maximum column.
Can go-stress-testing load test a gRPC service?
Yes. The README lists gRPC load testing and has a gRPC section, the repository has a proto directory, and go.mod requires google.golang.org/grpc and protobuf.
Does go-stress-testing support scripted user journeys or changing load?
Not with the -c, -n and -u parameters shown in the README's quick start. The workload is fixed by the -c and -n arithmetic against a single -u address, and the README notes that supporting a private protocol requires extending the tool. Locust and JMeter place the workload in a script instead, which is the difference that matters if requests need to be sequenced or authenticated.
How do I calculate how many machines a service needs from a load test?
The README gives the sizing method: multiply daily page views by 0.8, divide by 86400 seconds times 0.2, giving peak-second qps, then divide that by the qps a single machine sustains. Its worked example produces about 1389 qps, and dividing by 69 qps per machine gives roughly 20 machines.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/link1st-go-stress-testing)Star history chart for your README
[](https://hysenlabs.com/projects/link1st-go-stress-testing)Was this useful?