ControlNet: Adding Conditional Control to Stable Diffusion Without Destroying the Base Model
Let us control diffusion models!
At a glance
- What is it?
- ControlNet is a neural network structure that lets you steer Stable Diffusion with edges, poses, scribbles, or segmentation maps. It works by locking the original model weights and training a parallel copy, which keeps the base model intact.
- Who is it for?
- Adopt ControlNet if you need to add a specific condition (edges, pose, depth, segmentation) to a Stable Diffusion 1.5 workflow without retraining the base model, and you have a GPU (the README points 8GB GPUs to its low VRAM mode). Do not adopt it if you need a production-ready, maintained codebase, since the README says ControlNet 1.1 is released as a separate nightly repository and has not yet been merged here.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 33 months ago, on February 25, 2024.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 19, 2026, and from our analysis. They are not legal advice.
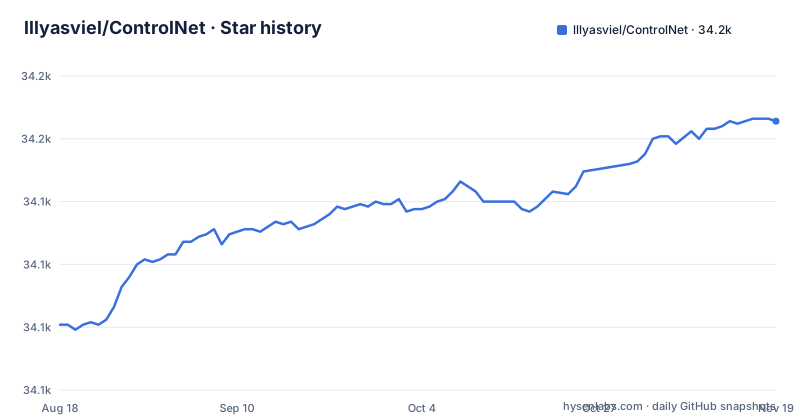
Star history
- lllyasviel/ControlNet34,157 ★ · +81
| Repository | 2026-08-18 | 2026-11-19 |
|---|---|---|
| lllyasviel/ControlNet | 34.1k | 34.2k |
81 Stars in the last 93 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What ControlNet Solves and Who It Is For
Text-to-image diffusion models like Stable Diffusion are hard to steer. A prompt can suggest a subject, but it cannot pin down the exact composition, the pose of a figure, or the precise edges of a building. ControlNet addresses this by adding extra conditions to the diffusion process. The target user is a researcher or an engineer who wants to generate images that respect a spatial constraint, such as a Canny edge map, a human pose skeleton, or a semantic segmentation mask. It is also aimed at people who want to fine-tune a diffusion model on a small dataset of image pairs without wrecking the pretrained model. The README is explicit about this: training with a small dataset will not destroy the production-ready diffusion models. That is the core promise, and it is a specific one.
The Locked and Trainable Copy Mechanism
The architecture is simple on paper. ControlNet copies the weights of neural network blocks into two copies: a locked copy and a trainable copy. The locked copy preserves the original model, and the trainable copy learns the condition. The two are connected by zero convolutions, which are 1x1 convolutions with both weight and bias initialized to zero. Before training, these zero convolutions output zeros, so ControlNet causes no distortion to the original model. No layer is trained from scratch; it is still fine-tuning. The README claims this is friendly to merging, replacement, and offsetting of models, weights, blocks, and layers. The mechanism also has a computational benefit: the original SD encoder does not need to store gradients, so the required GPU memory is not much larger than the original Stable Diffusion, even though many layers are added. That is a concrete design choice, and it is the reason training on personal devices becomes feasible.
Running the Provided Gradio Apps
Getting ControlNet running starts with creating a conda environment. The README gives two commands: conda env create -f environment.yaml and conda activate control. After that, you need to download all models and detectors from the Hugging Face page. The SD models go into ControlNet/models, and detectors go into ControlNet/annotator/ckpts. The repository provides nine Gradio apps, each tied to a specific condition type. For example, python gradio_canny2image.py runs the Canny edge control, python gradio_pose2image.py runs human pose control, and python gradio_seg2image.py runs semantic segmentation control. Each app is a standalone script, so you run them one at a time. The README notes that the Gradio UI is difficult to customize, and for the scribble app you need to draw scribbles outside the UI and import them as images. There is also an interactive scribble interface, but the README admits it was buggy and the drawing area was small, though it says that is now fixed.
The Zero Convolution Question
A natural objection to zero-initialized convolutions is that a zero weight produces a zero gradient, so the network should learn nothing. The README addresses this in the FAQ and points to docs/faq.md for an explanation. The README answers that this is not true and links to docs/faq.md for the explanation. The design is unusual, and it is worth understanding before you rely on it. If you are training your own condition, you should read that FAQ first.
Limitations and Failure Modes
The repository is not a finished product. The README announces a nightly version of ControlNet 1.1, and says those new models will be merged to this repo after everything is good. That means the current repo is version 1.0, and the maintenance status is uncertain. The README also complains about Gradio being buggy and difficult to customize, which affects the usability of the interactive interfaces. The pose and segmentation apps require you to input an image, and the detector extracts the condition automatically, so you cannot directly manipulate the skeleton or segmentation map. That is a real limitation if you want fine-grained control. The scribble app requires external drawing software, which is a workflow friction. Finally, the README mentions a low VRAM mode for 8GB GPUs, but it is not the default, and you need to read docs/low_vram.md to use it.
Alternatives and the Difference in Approach
The obvious alternative is to fine-tune Stable Diffusion directly on your condition data. That approach trains all layers or a large subset, which requires a large dataset and a lot of compute, and it risks catastrophic forgetting of the original model's capabilities. ControlNet avoids that by locking the base weights and training only a parallel trainable copy. ControlNet's approach is to inject the condition through the encoder path, reusing the SD encoder as a backbone. The README cites evidence that the SD encoder is an excellent backbone, and it connects layers in a computationally efficient way. The difference is that ControlNet is not a new model; it is a structure that wraps an existing model.
Maintenance and License Considerations
The repository is licensed under Apache-2.0, which is permissive for commercial use. The pretrained models are downloaded from a Hugging Face page, so check the model licences there. The maintenance status is a concern: the repository publishes no releases and the last push was 2024-02-25. The README's news section is from 2023, and the project appears to be in a transitional state, with version 1.1 living in a separate nightly repository. That means you are adopting a project that may not receive updates in this repo. The upgrade path is unclear: if you want the newer models, you have to switch to the nightly repo. The README points to docs/faq.md for the zero convolution explanation and docs/low_vram.md for low VRAM mode. This is a research codebase, not a polished library.
Editorial conclusion
Adopt ControlNet if you need to add a specific condition (edges, pose, depth, segmentation) to a Stable Diffusion 1.5 workflow without retraining the base model, and you have a GPU (the README points 8GB GPUs to its low VRAM mode). Do not adopt it if you need a production-ready, maintained codebase, since the README says ControlNet 1.1 is released as a separate nightly repository and has not yet been merged here. Before using it, verify that you can download all required pretrained weights and detector models from the Hugging Face page, and test the low VRAM mode if your GPU is 8GB. The core idea is solid, but the tooling around it is still rough.
Frequently asked questions
How do I use ControlNet?
Create the conda environment with `conda env create -f environment.yaml` and `conda activate control`, then download the base model into ControlNet/models and the detectors into ControlNet/annotator/ckpts from the project's Hugging Face page. Nine Gradio apps are provided, each launched as its own script, such as `python gradio_canny2image.py` for Canny edges and `python gradio_pose2image.py` for human pose.
How do I install ControlNet?
There is no package to install. The setup is a conda environment created from environment.yaml, followed by manually placing the Stable Diffusion models in ControlNet/models and the detector models, including HED, Midas and Openpose, in ControlNet/annotator/ckpts.
How do I use ControlNet with human pose?
Run `python gradio_pose2image.py`, which uses the Openpose detector on an image you supply rather than letting you manipulate a skeleton directly in the interface. The README notes that this model deserves a better interface and that Gradio is hard to customize, so the pose is detected for you.
How do I use ControlNet with Stable Diffusion?
The structure is repeated fourteen times on top of the Stable Diffusion encoder, which is reused as the backbone for learning controls while the original encoder blocks keep their locked copies and store no gradients. The result adds many layers without needing much more GPU memory than the original model.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/lllyasviel-controlnet)Star history chart for your README
[](https://hysenlabs.com/projects/lllyasviel-controlnet)Was this useful?