bitnet.cpp: Running 1.58-bit LLMs on CPUs
GitHub describes it as Official inference framework for 1-bit LLMs. The repository metadata lists C++ as its primary language. The metadata lists the MIT license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- Microsoft's official inference framework for ternary LLMs trades precision for speed and energy savings on commodity CPUs. The trade-off is real, but so is the constraint: you must use models trained for 1-bit weights.
- Who is it for?
- Adopt bitnet.cpp if you need to serve a 1.58-bit model on CPU-bound hardware, especially for edge or local deployments where memory and power are tight. Do not adopt it if you expect to run arbitrary full-precision LLMs; the framework only supports models trained or converted to 1.58-bit weights, and the quality of a 2B ternary model will not match a 7B FP16 one.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 111 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
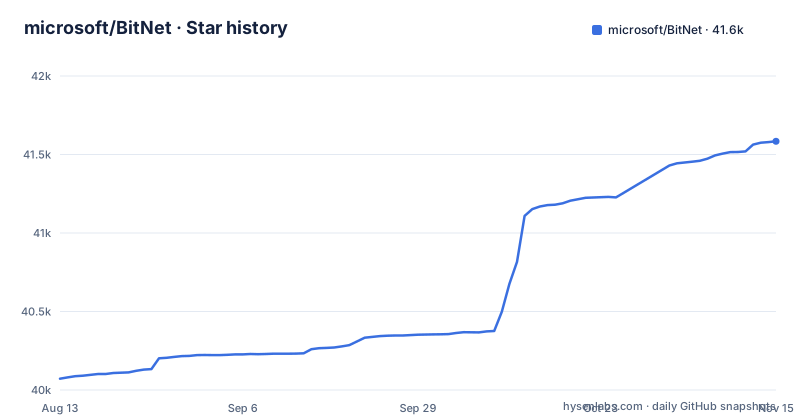
- microsoft/BitNet41,584 ★ · +1,512
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| microsoft/BitNet | 40.1k | 41.6k |
1,512 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: full-precision LLMs do not fit on edge CPUs
Running a large language model on a CPU is usually an exercise in patience. A 7B model in FP16 needs about 14 GB of memory and delivers a few tokens per second on a server chip. On a laptop or a Raspberry Pi, it is often unusable. bitnet.cpp attacks this from the weight side. Instead of storing weights in 16 or 8 bits, it stores them in 1.58 bits: each weight is ternary, either -1, 0, or +1. That reduces memory and compute dramatically. The README claims a 100B BitNet b1.58 model can run on a single CPU at 5-7 tokens per second, which is human reading speed. That claim is extraordinary, but the project's own technical reports and benchmarks back the general direction. The target user is not a datacenter operator with GPUs to spare. It is someone building local, private, or edge deployments where power and memory are the binding constraints.
The mechanism: ternary weights and lossless kernels
The core idea comes from the BitNet b1.58 paper: constrain every weight to three values. Multiplication with activations becomes addition and subtraction, which is far cheaper than floating-point multiply-accumulate. bitnet.cpp implements this with a suite of optimized kernels for CPU and GPU. The README distinguishes between the original implementation and later optimizations: a January 2026 release added parallel kernel implementations with configurable tiling and embedding quantization support, claiming an additional 1.15x to 2.1x speedup. The framework also supports I2_S conversion, a quantization format that uses 2 bits per weight and is the basis for the embedding models. The key word in the README is 'lossless'. The project claims that inference is lossless relative to the quantized model, meaning the kernels do not introduce extra error beyond the quantization itself. That is a strong statement, and it hinges on the kernels being bit-exact, which is plausible given the deterministic nature of integer arithmetic.
Getting it running: build from source and model conversion
The README points to two build paths: CPU and GPU. For CPU, you clone the repository and follow the build-from-source instructions in the main README. The GPU path has its own README under gpu/README.md, which you should read before attempting a GPU build because the kernels and dependencies differ. The repository has no GitHub releases, so you build from source. The documentation also references a detailed guide for converting and running BitNet embedding models with I2_S kernels: docs/bitnet-embeddings-i2s-guide.md. That guide covers the I2_S conversion process, which is necessary if you want to run the embedding models. The top level holds setup_env.py, run_inference.py and run_inference_server.py. The online demo at the Azure URL gives you a way to try the 2B model without building anything.
The performance claims: speedups and energy savings
The README is full of numbers. On x86 CPUs, speedups range from 2.37x to 6.17x compared to full-precision models, with energy reductions between 71.9% and 82.2%. On ARM CPUs, speedups are 1.37x to 5.07x, with energy savings of 55.4% to 70.0%. The 2B model specifically achieves up to 6.17x on x86 and 5.07x on ARM. The embedding models show prefill speedups of 1.42x to 2.28x for the 0.6B model and 1.32x to 1.74x for the 270M model, measured with 8 threads on x86. These numbers are impressive, but they come from the project's own benchmarks. Treat them as upper bounds. The energy figures are even harder to verify without a controlled setup. Still, the direction is clear: ternary weights reduce memory traffic, and memory traffic is often the bottleneck on CPUs.
A real limitation: model availability and quality
The biggest limitation is not the kernel speed; it is the model zoo. bitnet.cpp only runs 1-bit LLMs. The README's model-release section lists BitNet-b1.58-2B-4T (a 2.4B parameter ternary model) and two embedding models (0.6B and 270M). The 2B model is trained on 4 trillion tokens, which is a lot, but a 2B ternary model will not match a 7B FP16 model on complex reasoning tasks. The README says it delivers 'competitive performance with full-precision models of similar size', not larger ones. If your application needs high-quality generation, you will need to verify that the 2B model's outputs are good enough. The README also describes I2_S conversion for the embedding models.
The alternative: llama.cpp with quantized full-precision models
The obvious alternative is llama.cpp, which runs GGUF-quantized models on CPUs. llama.cpp supports 2-bit, 3-bit, 4-bit, and 5-bit quantization of models that were trained in higher precision. The difference in approach is fundamental: llama.cpp quantizes existing weights, while bitnet.cpp runs models that were designed with ternary weights from the start. BitNet b1.58 models are trained to work with ternary weights, so the quality loss from quantization is smaller than what you would get from rounding a dense model to 2 bits. However, llama.cpp has a much larger ecosystem of models. You can run Llama 3, Mistral, or any GGUF file. bitnet.cpp is limited to 1-bit models. If you need a specific model that has no BitNet variant, llama.cpp is the safer choice. If you want maximum efficiency on a CPU and are willing to accept the model constraint, bitnet.cpp is the more specialized tool.
Maintenance and license: MIT but a moving target
The project is licensed under MIT, which is permissive. You can use it commercially, modify it, and embed it in your own products without licensing fees. That is a strong point for adoption. The maintenance picture is mixed. The README shows a steady stream of releases from October 2023 through July 2026, including new models, GPU kernels, and optimization guides. The project is not archived, and the news section shows recent activity. However, the repository has no GitHub releases, which suggests that the project may be developed in a rolling fashion rather than with tagged releases. That means you will likely be building from the main branch, which can change under you. The GPU kernel and the CPU kernel have separate READMEs, suggesting a split codebase. Upgrading from one version to another may require re-reading the guides. The cost of maintenance is moderate: you need to track the repository for changes, rebuild when you update, and test your specific hardware, especially for ARM and GPU paths.
Editorial conclusion
Adopt bitnet.cpp if you need to serve a 1.58-bit model on CPU-bound hardware, especially for edge or local deployments where memory and power are tight. Do not adopt it if you expect to run arbitrary full-precision LLMs; the framework only supports models trained or converted to 1.58-bit weights, and the quality of a 2B ternary model will not match a 7B FP16 one. Before committing, verify that your target model has an official BitNet variant or that you can convert it with the provided I2_S tools, and check the GPU kernel's README for hardware-specific requirements, since CPU and GPU paths differ significantly.
Frequently asked questions
What is BITNET used for?
bitnet.cpp is the official inference framework for 1-bit LLMs such as BitNet b1.58. It offers a suite of optimized kernels for fast and lossless inference of 1.58-bit models on CPU and GPU, with NPU support described as coming next. The README's model-release section lists one 2.4B language model and two embedding models.
What is BITNET b1 58?
It is the ternary, 1.58-bit, model line introduced by the paper The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits. The official model here is BitNet-b1.58-2B-4T, with 2.4B parameters trained on 4 trillion tokens, and it is quoted at up to 6.17x speedup on x86 CPUs against full-precision models.
how to install bitnet cpp
It offers an online demo to try immediately, or building and running it yourself, with a build-from-source anchor in the file and a separate GPU README. The top level holds setup_env.py, run_inference.py and run_inference_server.py, and requirements.txt resolves entirely into a 3rdparty llama.cpp submodule.
how to use bitnet cpp
You build it and run one of the top-level Python scripts, run_inference.py for inference or run_inference_server.py for the server, after setup_env.py. The CPU kernels are described in src/README.md, including parallel implementations with configurable tiling and embedding quantization support, and the GPU kernels have their own guide at gpu/README.md.
what is bitnet model
The README's model-release section lists three: BitNet-b1.58-2B-4T, a 2.4B-parameter ternary language model trained on 4 trillion tokens that supports conversational mode, plus BitNet-embedding-0.6B and BitNet-embedding-270M, embedding models quoted at 1.42x to 2.28x and 1.32x to 1.74x over F16 on prefill with 8 threads on x86.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-bitnet)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-bitnet)Was this useful?