LLMForEverybody: a Chinese chapter tree for LLM interview prep, fronted by a LearnLLM.AI storefront
LLM knowledge shared in a way everyone can understand; a must-read before spring/autumn recruitment LLM interviews so you can talk confidently with interviewers.
At a glance
- What is it?
- luhengshiwo/LLMForEverybody organizes large language model knowledge into thirteen numbered Chinese chapters aimed at job seekers preparing for recruitment-season interviews. The repository is free under Apache-2.0, but its README now steers readers toward paid courses and walkthroughs hosted on learnllm.ai.
- Who is it for?
- LLMForEverybody suits Chinese-reading engineers preparing for LLM interviews who want a free, chapter-by-chapter reading path from pretraining through quantization, agents, evaluation and math. Readers who need English or Russian chapter content, versioned snapshots, or self-contained paper walkthroughs on GitHub should look elsewhere or accept that much of the guided material sits on learnllm.ai.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 78 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
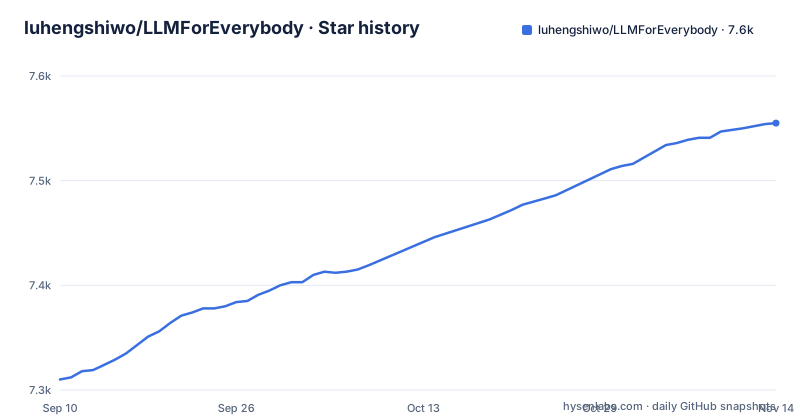
- luhengshiwo/LLMForEverybody7,555 ★ · +245
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| luhengshiwo/LLMForEverybody | 7.3k | 7.6k |
245 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Thirteen numbered chapters, from the road to AGI to personal reflections
The repository is laid out as a book. Each top-level folder is a numbered chapter with a Chinese title, and the numbers give a reading order. 00-序-AGI之路 is the preface on the road to AGI. 01-第一章-预训练 covers pretraining, 02-第二章-部署与推理 covers deployment and inference, 03-第三章-微调 covers fine-tuning, and 04-第四章-量化 covers quantization. 05-第五章-显卡与并行 deals with GPUs and parallelism, 06-第六章-Prompt Engineering with prompting, and 07-第七章-Agent with agents. The later chapters move away from model internals: 08-第八章-大模型企业落地 is about putting large models into production at companies, 09-第九章-评估指标 is about evaluation metrics, 10-第十章-热点 tracks hot topics, 11-第十一章-数学 gathers the math, and 12-第十二章-企业与个人思考 closes with thoughts on companies and individuals.
That ordering matters for an interview candidate. The sequence runs from how a model is trained, to how it is served, to how it is adapted and compressed, to the hardware underneath, and only then to prompting and agents. Someone who only wants agent questions can jump straight to chapter 07, but the numbering signals that the author expects the earlier chapters to be read first. Alongside the chapters sit docs/, draft/ and pic/ folders, plus the LICENSE and three README files.
The README front page is now a storefront for LearnLLM.AI
Opening the repository on GitHub, the first substantial block is not a table of contents for the chapters. It is a pitch for LearnLLM.AI, the project homepage at https://www.learnllm.ai. The pitch lists three offerings: a curated bank of LLM interview questions ranging from fundamentals to frontier topics, a systematic paper-reading track that starts from the 2017 Transformer paper, and a set of Chinese practical courses on AI Agent, RAG knowledge bases, fine-tuning and LLM application development. The courses name LangChain, LlamaIndex, Dify and MCP as the toolchains they cover, and they come with project code and instructor Q&A.
The courses are sold. The README offers GitHub users a discount code, GITHUB50, described as limited-time, and links to https://learnllm.ai/courses?ref=github for the full catalogue. Every outbound link carries a ref=github parameter. For a reader this means the README has two jobs at once: it is the entry point to a free, Apache-2.0 repository, and it is a sales page for a separate paid product. Treat the course descriptions as marketing copy from the same team, not as an independent review of what the courses contain.
The paper table walks from Transformer in 2017 to Gemma 2
Below the promotion is a table titled LLM 精选论文, a selection of milestone papers. Each row has five columns: date, paper link, a one-line Chinese summary, a bilibili video, and a Start learning link. The visible rows start with Transformer (2017-06-12, self-attention and the Transformer architecture), then GPT-1 (2018-06-11, generative pretraining plus fine-tuning), BERT (2018-10-11, bidirectional encoder with MLM and NSP), GPT-2 (2019-02-14), T5 (2019-10-23, a unified text-to-text framework) and GPT-3 (2020-05-28, scale and few-shot learning).
The list is not limited to text models. It includes ViT, ViLT, CLIP, DALL·E 1, Stable Diffusion, DALL·E 2 and Whisper on the vision, image generation and speech side, Codex and AlphaCode for code generation, and InstructGPT for alignment through human feedback. From 2023 onward it shifts to open models: LLaMA-1, LLaVA, LLaMA-2, Qwen-VL, Qwen 1, Mistral 7B, LVM, Mixtral 8x7B, Gemma 1, DeepSeek-V2, ChatGLM, Llama 3 and Gemma 2. Some dates are given to the day and some only to the month, such as 2020-10 for ViT and 2024-02 for Mixtral 8x7B. For interview preparation the table works as a chronology to talk through: what each paper introduced, in one sentence, in order.
Every Start learning link leaves GitHub for learnllm.ai
The paper table looks like a study plan, but the study itself does not happen in the repository. Each Start learning cell points to a URL of the form https://www.learnllm.ai/learning?milestone=transformer&ref=github, with the milestone value changed per paper (gpt1, bert, llama2, deepseek-v2 and so on). Each video cell points to bilibili. The paper column links to arXiv or OpenAI PDFs.
The consequence is that a reader who clones the repository to study offline does not get the guided paper walkthroughs that the table advertises. Those live on an external site run by the same team, and whatever access rules, account requirements or pricing that site applies are outside the repository and outside its Apache-2.0 license. If learnllm.ai changes its URL scheme or retires a milestone page, the table's links break with no copy kept on GitHub. Anyone building a study plan around the table should check that the milestone pages they need are reachable, and keep the arXiv links as the fallback source of truth.
Reading the repository and pinning a revision
LLMForEverybody is reading material, not software. There is no package to install and no command to run; you browse the chapter folders on GitHub or clone the repository with git. GitHub reports Jupyter Notebook as the primary language, so some chapters ship notebooks rather than plain Markdown, and opening those needs a Jupyter environment or GitHub's notebook viewer.
The retrieved repository metadata lists no GitHub releases. Releases and Git tags are separate concepts, so check tags independently; a commit hash provides a precise revision to cite or compare. The draft/ folder sits beside the chapter folders, and its name alone does not establish which drafts are current. If you are preparing for a specific interview date, note the commit you studied from so you can find it again.
Chinese folder names are the real interface, and they bite in a shell
The README exists in three languages: README.md in Chinese, README.en.md in English and README.ru.md in Russian. The chapter tree does not follow suit. Every chapter folder name is Chinese, and the top-level listing shows a single chapter tree, not parallel English or Russian copies. The project description itself frames the audience as candidates heading into China's spring and autumn recruitment seasons. A reader who cannot read Chinese can follow the English README to understand the project but will be navigating the chapters by number rather than by title.
The folder names also carry practical friction. Names such as 06-第六章-Prompt Engineering contain a space, and all of them mix ASCII and CJK characters. In a terminal, those paths must be quoted, and scripts that walk the tree need to handle UTF-8 file names correctly. If you plan to convert the chapters into another format, test the path handling on one folder before running anything across all thirteen.
Videos and community channels sit on other platforms
The README points to companion video tutorials, marked as still being updated, on two platforms: a bilibili list at https://space.bilibili.com/37863979/lists?sid=7144646 and a YouTube channel at https://www.youtube.com/@learnllm-ai. The header also links the author's accounts on WeChat (an official account article), Zhihu, CSDN and Juejin.
This spread is useful if you already live on those platforms, and awkward if you do not. Discussion of a chapter can happen on Zhihu, a video comment thread, or GitHub, with no single place that collects corrections. The repository's own Apache-2.0 license covers the files in the repository. It does not tell you the terms for the videos, the posts on CSDN or Juejin, or the courses on learnllm.ai, so check each platform separately before reusing anything from them in your own notes or teaching material.
Editorial conclusion
LLMForEverybody suits Chinese-reading engineers preparing for LLM interviews who want a free, chapter-by-chapter reading path from pretraining through quantization, agents, evaluation and math. Readers who need English or Russian chapter content, versioned snapshots, or self-contained paper walkthroughs on GitHub should look elsewhere or accept that much of the guided material sits on learnllm.ai. Before relying on it, open the specific chapter folder you care about, check the last push date (2026-08-28 at the time of writing), and read learnllm.ai's own terms before buying a course with the GITHUB50 code.
Frequently asked questions
Is LLMForEverybody free to use?
The repository is released under the Apache-2.0 license. The README also promotes paid courses on learnllm.ai, with a limited-time discount code GITHUB50 for GitHub users; those courses are a separate product.
Does LLMForEverybody have an English version?
There is an English README (README.en.md) and a Russian one (README.ru.md). The thirteen chapter folders all have Chinese names, and the top-level listing shows only one chapter tree.
What topics does LLMForEverybody cover?
Its chapters cover pretraining, deployment and inference, fine-tuning, quantization, GPUs and parallelism, prompt engineering, agents, enterprise adoption, evaluation metrics, hot topics, math, and closing reflections. The README adds a paper timeline from the 2017 Transformer paper onward.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/luhengshiwo-llmforeverybody)Star history chart for your README
[](https://hysenlabs.com/projects/luhengshiwo-llmforeverybody)Was this useful?