microsoft/call-center-ai: an API that places phone calls and fills a claim schema
Send a phone call from AI agent, in an API call. Or, directly call the bot from the configured phone number!
At a glance
- What is it?
- This is an Azure-hosted Python service that turns an HTTP POST into an outbound AI phone call and returns a structured record of what was said. It is aimed at teams already inside Azure who need low to medium complexity calls handled, not at anyone wanting a self-contained voice stack.
- Who is it for?
- Treat it as the proof of concept the README says it is, not intended for production, and adopt it only if you are already on Azure, your calls are scripted around a claim schema, and you accept that the bot is bound to Azure Communication Services, Cognitive Services and OpenAI resources. Do not adopt it if you need a carrier-neutral or self-hosted voice stack, or if your calls are open-ended rather than form-filling.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- No. The owners have archived the repository on GitHub, so it is read-only and no longer receives changes.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
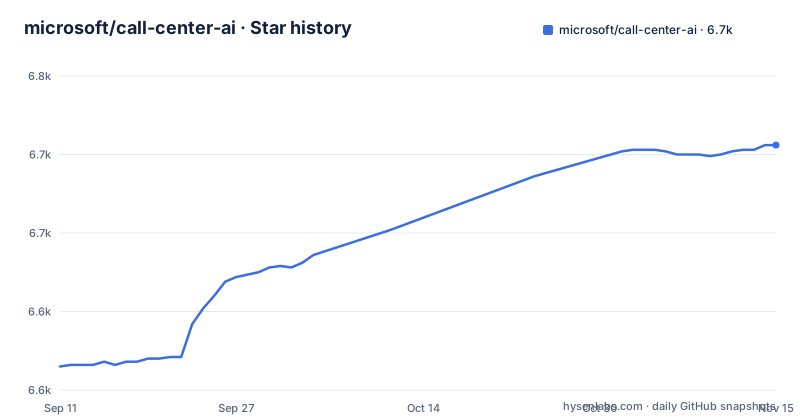
Star history
- microsoft/call-center-ai6,706 ★ · +141
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| microsoft/call-center-ai | 6.6k | 6.7k |
141 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: turning a phone call into a filled-in form
Most voice bot projects stop at conversation. This one starts from the record it wants to produce. The README frames the use case as insurance, IT support and customer service, and the request body makes the intent explicit: you send a claim array where each entry has a name and a type, and the agent's job during the call is to gather those fields. In the worked example the fields are hardware_info, first_seen and building_location. The demo output shows the same idea with an insurance claim: incident_description, incident_location, involved_parties and policy_number, all populated from a French-language call. The audience is therefore narrow and specific. It is for a team that already receives calls or wants to place them, has a defined set of questions, and wants the answers in a database row rather than a transcript someone has to read. If your calls are exploratory, or your output is a decision rather than a set of fields, the claim schema is working against you rather than for you.
What the POST /call request actually carries
The README gives one curl example and it is the clearest statement of the interface. You POST JSON to a /call endpoint with bot_company, bot_name, phone_number, task and agent_phone_number, plus the claim array. bot_company and bot_name set the persona; in the example the assistant is Amélie working for Contoso. task is free text describing the objective, and the README's own wording is instructing: the assistant works for the IT support department, helps with the issue, and gathers information in the claim. agent_phone_number is a separate number, which suggests a human fallback path, consistent with the feature list mentioning human agent fallback. Check the repository for authentication on that endpoint, rate limits, and what the response body contains rather than guessing. The endpoint is the whole product surface: everything else in the repository exists to make that one request produce a phone call and a stored record.
The data flow: telephony in, structured JSON out
The pipeline visible in the README runs through Azure. Azure Communication Services carries the call, Cognitive Services handles speech, and OpenAI resources supply the model. The README states that conversations are streamed in real time to avoid delays, can be resumed after disconnections, and are stored for future reference. Streaming matters here because a turn-based pipeline that waits for a full recording before transcribing would add seconds to every reply. Resumption matters because phone calls drop. The demo extract shows a claim object and messages with created_at, action, content, persona, style and tool_calls, and the demo stores conversation, claim and todo list in the database. Redis is named for caching, and Application Insights for monitoring and tracing. The README also mentions retrieval-augmented generation over internal documents and fine-tuning on historical conversations.
Deployment is Azure-shaped, and that is the main constraint
The README describes a containerized, serverless architecture on Azure, with provisioning of LLM resources called out as a way to reduce latency. There is a GitHub Codespaces badge pointing at a quickstart, so the fastest path to a running instance is a Codespace rather than a local install. If you are evaluating this for adoption, the first thing to check in the repository is how the infrastructure is declared and which resource types it creates. The provider lock-in is not incidental. Swapping Azure Communication Services for another telephony provider would mean replacing the call handling layer, and the model choice is expressed in OpenAI resource terms. The README's own note that gpt-4.1 and gpt-4.1-nano are known for a 10 to 15x cost premium is a useful signal: model selection is a cost lever you will be adjusting.
Where the design strains: latency, cost and the schema itself
Three limitations follow. First, latency. Streaming reduces delay but does not remove it, and the README explicitly suggests provisioning LLM resources to cut it, which means the default deployment is not the fastest configuration. Second, cost. A live phone call holds a model in a loop for its full duration, and the README itself flags the premium tier. Call length is the cost driver, and a bot that handles long, meandering calls will cost more than one that closes them. Third, the schema. A fixed claim array is a good fit for insurance intake and a poor fit for anything where the important information is not known in advance.
The honest alternative: a speech pipeline you assemble yourself
The obvious comparison is a general voice agent framework built on a real-time speech API, where you write the turn loop and choose the telephony provider separately. The difference is where the structure lives. Here, the claim schema and the reminders are part of the product, and the model is prompted to fill them. In a hand-assembled pipeline you would build each of those as your own tool call or post-processing step, which gives you control over the prompt, the model and the carrier, at the cost of writing and maintaining the orchestration. If your calls genuinely fit the claim pattern and you are on Azure, the assembled version is duplicated work. If your calls do not fit the pattern, you are fighting the abstraction. There is no middle ground: the interface is a task string plus a field list.
Licence and the cost of keeping up
The repository is Apache-2.0, which permits commercial use and modification and includes an explicit patent grant. It does not cover the Azure services the code calls, and it does not cover the model weights or the OpenAI API terms, which are separate agreements you accept when you deploy. The release cadence is rapid: v17.4.0, v17.4.1 and v17.4.2 all landed within four days in May 2025, and the last push to the default branch is dated 2026-07-01. A patch-level burst like that usually means fixes shipping quickly, which is good for users and also means you should pin a version rather than track main. Upgrading carries two kinds of cost: the code itself, and the prompts and model versions bundled with it, since a change in how the claim is extracted can alter your stored data shape. Budget for reading the diff on every minor bump, not just the major ones.
Editorial conclusion
Treat it as the proof of concept the README says it is, not intended for production, and adopt it only if you are already on Azure, your calls are scripted around a claim schema, and you accept that the bot is bound to Azure Communication Services, Cognitive Services and OpenAI resources. Do not adopt it if you need a carrier-neutral or self-hosted voice stack, or if your calls are open-ended rather than form-filling. Before committing, verify the Bicep deployment in the repository, the current gpt-4.1 pricing against your call volume, and whether the call recording and Application Insights telemetry you enable match your own data-retention rules.
Frequently asked questions
What does Call Center AI do with a single API call?
It places an outbound phone call from the AI agent: the payload carries bot_company, bot_name, phone_number, agent_phone_number, a free-text task and a claim array that declares which fields to collect and whether each is text or datetime. A person can also call the bot from the configured phone number instead.
What does the Call Center AI report page show?
It shows the conversation history, the claim data and the reminders, and it is reached at https://[your_domain]/report/[phone_number], with the local example http://localhost:8080/report/%2B133658471534. The phone number is the key, with the plus sign percent-encoded.
Which Azure services does Call Center AI need?
The component diagram names Communication Services for calls and SMS, Cosmos DB for conversations and claims, Event Grid as the broker, Azure Storage queues, Redis as the cache, AI Search for RAG, an ADA embedding, Azure Storage for sounds, Cognitive Services for speech to text, and gpt-4.1 with gpt-4.1-nano as the LLM.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-call-center-ai)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-call-center-ai)Was this useful?