GraphRAG: A Research-Grade Graph Pipeline for LLM Question Answering, Now in Maintenance Mode
A modular graph-based Retrieval-Augmented Generation (RAG) system
At a glance
- What is it?
- Microsoft's GraphRAG offers a modular pipeline for extracting knowledge graphs from unstructured text to ground LLM answers. It is a capable but expensive research tool, explicitly in maintenance mode, so adopters must weigh its unique graph-based approach against the cost and lack of new features.
- Who is it for?
- Adopt GraphRAG if you need to answer questions over large, narrative-heavy private corpora and you have the compute budget for LLM-driven indexing. Do not adopt it if you need active feature development, or if your data is small enough for simpler RAG.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
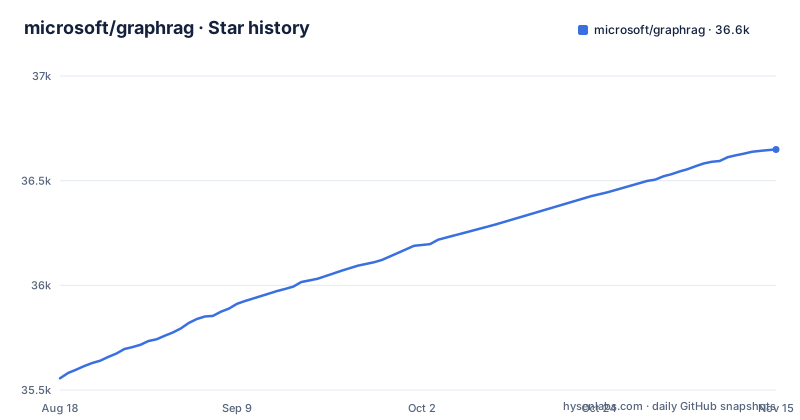
Star history
- microsoft/graphrag36,649 ★ · +1,093
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| microsoft/graphrag | 35.6k | 36.6k |
1,093 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What GraphRAG Actually Solves
GraphRAG addresses a specific failure of standard RAG: when your private data is a collection of narratives, like email threads, reports, or historical documents, a simple vector search often retrieves fragments that miss the global context. The README describes the project as 'a data pipeline and transformation suite that is designed to extract meaningful, structured data from unstructured text using the power of LLMs.' That extraction produces a knowledge graph, and that graph becomes the memory structure for question answering. The intended user is a developer or researcher who has a corpus of text where relationships between entities matter, not just keyword matches. Microsoft's research blog positions it as a way to unlock LLM discovery on narrative private data. If your data is a set of independent facts, a conventional RAG pipeline may serve you better, but if the answers depend on how entities connect across documents, GraphRAG is the specific tool.
The Mechanism: From Text to Graph to Context
The core idea is to use an LLM to read every document and extract entities and relationships, then store them as a graph. The documentation describes this as a 'methodology for using knowledge graph memory structures to enhance LLM outputs.' The pipeline is modular, meaning you can swap components, but the README itself only says the project explores the functional use of graphs to form a targeted context for question answering. The README warns that indexing can be an expensive operation.
Getting It Running: Commands and Configuration
The quickstart is command-line driven. You start with `graphrag init --root [path]`, which creates a configuration file and a prompts folder. The README explicitly says to run `graphrag init --root [path] --force` between minor version bumps to get the latest config format. After initialization, you run the indexing pipeline, which processes your input documents and builds the graph. The exact indexing command is not in the README, but the documentation at microsoft.github.io/graphrag/get_started/ provides it. The configuration file controls LLM endpoints, API keys, and pipeline parameters. Prompt tuning is strongly recommended: the README says 'Using GraphRAG with your data out of the box may not yield the best possible results.' That means you should follow the Prompt Tuning Guide to fine-tune your prompts for your data. The whole process is not a single command; it is a multi-step workflow that requires you to understand the config format and the prompts. The README also warns you to back up your configuration and prompts before running `--force`, because it overwrites them.
The Elephant in the Room: Maintenance Mode and Cost
The README contains a prominent warning: 'This project is largely in maintenance mode, and won't be accepting new PRs or implementing new features.' That is a hard constraint for any adopter. You will get bug fixes and dependency updates, particularly for CVEs, but no new functionality. The second warning is about cost: 'GraphRAG indexing can be an expensive operation.' The README advises you to read all of the documentation to understand the process and costs involved, and to 'start small'. The maintenance mode compounds the cost issue because you cannot rely on future optimizations to reduce the bill. If you adopt GraphRAG, you are committing to the current cost profile, which may or may not be acceptable depending on your data size and LLM pricing.
Versioning and Upgrade Path
The project has a clear versioning policy, documented in the breaking-changes.md file. Between minor version bumps, you must re-run `graphrag init --root [path] --force` to update your config format. Between major version bumps, you can run a migration notebook to avoid re-indexing prior datasets, but that notebook is not in the README; it is referenced as something you must run. The important caveat is that `--force` overwrites your configuration and prompts, so you must back them up. This means every minor upgrade is a potential breaking change to your setup. The recent releases are v3.3.0 on 2026-10-08, v3.2.0 on 2026-09-24 and v3.1.2 on 2026-08-21. That suggests active maintenance, but the maintenance mode warning says feature work has stopped. The upgrade process is manageable, but it is not automatic. You need to read the breaking-changes document and plan for config migrations. The license is MIT, which is permissive, but the README notes that the code is a demonstration and not an officially supported Microsoft offering, so you cannot expect support from Microsoft.
Alternatives and the Difference in Approach
The most direct alternative is a standard RAG pipeline, where you chunk your documents, embed them, and retrieve by vector similarity. That approach is simpler and cheaper, but it lacks the global reasoning that GraphRAG provides. A vector index treats each chunk independently, so it cannot answer a question that requires synthesizing information from ten different documents unless the retrieval happens to surface the right chunks. GraphRAG's graph structure explicitly encodes relationships, so the context is built by traversing those relationships. Another alternative is a graph database like Neo4j combined with an LLM, but that requires you to manually define the schema and write the extraction logic yourself. GraphRAG automates the extraction, which is its main advantage. The trade-off is that GraphRAG is a research project with its own pipeline, while a custom graph database gives you full control. If you need to answer questions that span documents, GraphRAG is the ready-made option; if you need to control the extraction quality or the graph schema, you will have to build your own.
Limitations and Failure Modes
The most obvious limitation is the cost, which the README warns about. A second limitation is the quality of the extracted graph, which depends entirely on the LLM you use and the prompts you provide. The README says out-of-the-box results may be poor, and prompt tuning is strongly recommended. That means you cannot just point GraphRAG at your data and expect good answers; you must invest time in tuning. A third limitation is the maintenance mode: you cannot request features, and you cannot contribute PRs. If you find a bug that is not a CVE, you may be stuck. The project is also a demonstration, not a supported product, so you are on your own if something breaks. The failure mode is that you spend significant money and time on indexing, only to find that the graph quality is insufficient for your questions. The README's advice to start small and tune your prompts is the main mitigation; it also links RAI_TRANSPARENCY.md for how GraphRAG was evaluated and which metrics were used.
Editorial conclusion
Adopt GraphRAG if you need to answer questions over large, narrative-heavy private corpora and you have the compute budget for LLM-driven indexing. Do not adopt it if you need active feature development, or if your data is small enough for simpler RAG. Before committing, verify the current indexing cost on a small sample, run prompt tuning as the README insists, and check the breaking-changes document for your target version. The project is in maintenance mode, so plan for a frozen feature set and rely on bug fixes only. If you need a maintained graph-based RAG, look elsewhere, but as a research-grade reference implementation from Microsoft Research, GraphRAG is still worth studying.
Frequently asked questions
what is graphrag
GraphRAG is a modular graph-based retrieval-augmented generation system, described as a data pipeline and transformation suite that extracts meaningful, structured data from unstructured text using LLMs. It presents a methodology for using knowledge graph memory structures to enhance LLM outputs.
Is GraphRAG open source?
The repository carries an MIT LICENSE and the package is published on PyPI as graphrag. The code is described as a demonstration and not an officially supported Microsoft offering, and the project is largely in maintenance mode, with no new pull requests and no new features.
Why is GraphRAG better than RAG?
The repository does not make a head-to-head comparison. It frames GraphRAG as forming a targeted context for question answering using graphs, and it points to RAI_TRANSPARENCY.md for how GraphRAG was evaluated and which metrics were used, which is the place to look before accepting any superiority claim.
how to install graphrag
The quickstart recommendation is the command line quickstart in the documentation at microsoft.github.io/graphrag/get_started/, and the package is on PyPI as graphrag. The repository's own metadata requires Python 3.11 up to but not including 3.14, and the one command in the README is graphrag init --root [path] --force, which is for refreshing config between minor version bumps.
what is graphrag good for
The project positions it as forming a targeted context for question answering over private data, and RAI_TRANSPARENCY.md covers its intended uses. The repository also warns that indexing can be an expensive operation and tells you to start small.
Can GraphRAG be used with Postgres?
The repository does not name a database backend. It describes itself as a data pipeline and transformation suite for extracting structured data from unstructured text, and the architecture and configuration details are in the documentation rather than in this repository.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Does Graph RAG Actually Help? I Measured It on Postgres and TypeScriptdev.to · Nov 5, 2026 · 2 points · 4 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-graphrag)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-graphrag)Was this useful?