TimeCraft: Microsoft's Diffusion Framework for Cross-Domain Time Series Generation
Official code for TimeCraft: A Time Series Generation Framework for Real-World Applications
At a glance
- What is it?
- TimeCraft is a Python diffusion framework for generating synthetic time series across domains, with text-based control and task-aware adaptation. It is research code aimed at teams that need controllable synthetic temporal data, not a drop-in library.
- Who is it for?
- TimeCraft is for research and applied ML teams that need synthetic time series with domain control, text conditioning, or downstream-task targeting, and that can read a paper alongside the code. It is not for teams wanting a pip-installable data augmentation library, and it is not a substitute for collecting real data where collection is feasible.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 18 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
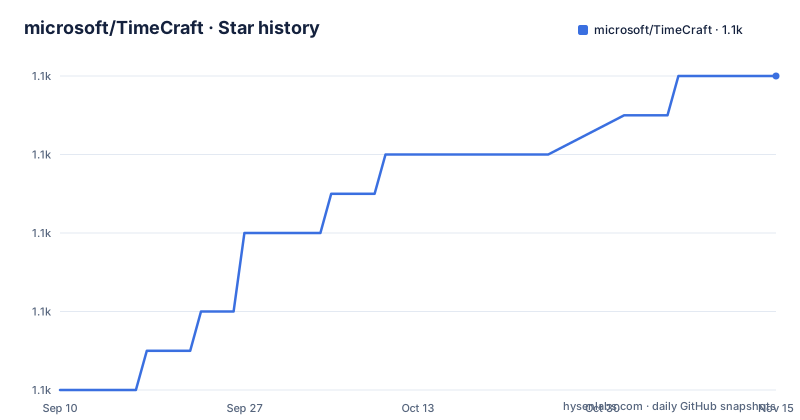
Star history
- microsoft/TimeCraft1,098 ★ · +8
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| microsoft/TimeCraft | 1.1k | 1.1k |
8 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem TimeCraft targets: single-domain generators and unconditional sampling
Most time series generators are trained on one dataset and reproduce that dataset's distribution. The TimeCraft README states this directly: existing methods are "limited to single-domain generation" and "lack controllability." The second complaint matters more than the first for practitioners. A generator that produces plausible ECG windows is useful only if you are working on ECG. A generator that produces plausible ECG windows when you ask for them, and stock ticks when you ask for those, is a different kind of asset. TimeCraft is built for the second case. The intended users are teams in healthcare, finance, energy, and transportation that face data scarcity, privacy constraints on sharing real records, or a need to simulate scenarios that cannot be collected. The README also names a third failure it wants to fix: models that "focus solely on replicating the training data distribution" without asking whether the synthetic data helps the downstream model. That is the target-aware claim, and it is the most ambitious part of the framework.
Semantic prototypes and the Prototype Assignment Module
The cross-domain mechanism rests on a shared latent space. TimeCraft learns what the README calls "semantic prototypes," described as a dictionary of temporal patterns that encode domain-invariant features such as trends and seasonality. A prototype is not a template you pick by hand. It is a learned latent component, and the claim is that the same components reappear across domains. Adaptation to a new domain happens through the Prototype Assignment Module (PAM), which computes domain-specific weights over the prototypes from few-shot examples. The result is a domain prompt, a latent representation of the target domain built without labels and without retraining the base model. The design has a clear appeal: you pay for the base model once and pay a small few-shot cost per new domain. It also has a clear dependency. The quality of the prompt is bounded by the few-shot examples you supply. The README does not specify how many examples count as few-shot, how sensitive the prompt is to their selection, or what happens when the target domain shares no prototypes with the training mixture. Those are the questions to answer before trusting cross-domain output.
Text conditioning and the multi-agent description pipeline
The second branch is text control. TimeCraft uses a multi-agent text generation system to produce textual descriptions of time series patterns, and those descriptions become paired time series and text data for training. At generation time the framework combines semantic prototypes with free-form textual prompts, which the README calls hybrid conditioning. The practical value is interpretability: a prompt can name a trend, a seasonality pattern, or a domain characteristic, and the prototype side keeps the output grounded in patterns the model has actually seen. The risk is inherited from the text pipeline. If the multi-agent system writes descriptions that do not match the underlying series, the model learns a mismatched pairing, and no amount of conditioning at inference fixes that. The README does not describe a validation step for the generated descriptions, so anyone using this branch should inspect the paired data before training on it. Treat the text branch as a data-construction pipeline you have to audit, not a black box.
Influence-guided diffusion for downstream tasks
The third branch changes the objective. Instead of matching the training distribution, TimeCraft generates samples intended to improve a downstream model, using an influence-guided diffusion mechanism that estimates the expected reduction in task-specific loss through influence functions. The README lists forecasting, classification, and anomaly detection as the target tasks. This is the part of the framework with the least detail in the README. Influence functions are expensive to compute, and the README does not say how the estimate is approximated, how often it is recomputed during sampling, or what the cost is relative to unconditional generation. It also does not say what happens when the downstream model is later retrained on a different architecture, since the generated samples were optimized against one specific model and loss. If you adopt TimeCraft for this feature alone, plan to verify the influence computation yourself in the code before committing to it.
Getting it running: what the README actually gives you
The current README provides a Quick Start and the root includes `environment.yml` and `train_inference.py`. Create the documented Conda environment from the repository root:
conda env create -f environment.ymlThe dataset preparation example runs `python TimeDP/utils/prepare_datasets.py`; it downloads and transforms public data and writes training and validation windows. Review the script, storage requirements and dataset terms before running it. The README also describes optional text-controlled and target-aware preparation. Some target-aware datasets require prior approval and credentialing.
The repository contains separate research directories including CaTSG, OATS and Diff-MN. Follow the current README and the relevant subproject instructions for configuration and training; validate the result on the target domain rather than assuming the examples transfer unchanged.
Where TimeCraft is the wrong tool
The most obvious limitation is that this is research code. The repository has no published GitHub releases. If your team needs synthetic time series next week and has no capacity to read a paper and adapt training scripts, TimeCraft will cost more than it returns. A second limitation is the few-shot requirement in the PAM path: cross-domain generation assumes you can supply representative examples of the target domain. If you have none, the prototype assignment has nothing to weight against, and you are back to the base model's training mixture. A third is the evaluation gap. The supplied examples and evaluations must still be checked against your own task, baselines and data before relying on the generated samples. Finally, the target-aware branch optimizes against a specific downstream model and loss. If your production model changes architecture or objective, the samples generated for the old one may no longer be the right samples.
Alternatives and the difference in approach
The README itself names TimeDP, a Microsoft Research project described as creating cross-domain synthetic time-series data, and links a research blog about it. The distinction is scope. TimeDP is presented as a cross-domain generator; TimeCraft adds text-based control and influence-guided, target-aware generation on top of the cross-domain foundation, and the 2026 updates extend it further into causal control (CaTSG), online augmentation for time series foundation models (OATS), and continuous generation from irregular observations (Diff-MN). If your need is cross-domain generation alone, TimeDP is the narrower and presumably simpler target. If you need to steer generation with text or to optimize synthetic data for a downstream task, TimeCraft is the only one of the two that claims those capabilities in the README. Outside Microsoft's own line, the general alternative is classical augmentation (jittering, scaling, window warping) applied to your existing series. That approach needs no training and no few-shot examples, but it cannot invent a domain you have no data for, which is precisely the case TimeCraft is built around.
Licence, maintenance, and what to verify first
TimeCraft is MIT licensed, which permits commercial use and modification with the usual attribution requirement. The CaTSG, OATS and Diff-MN subdirectories are separate research contributions with their own papers, so check each subdirectory for its own licence file before shipping anything derived from them. On maintenance: the repository is not archived, the last push is 2026-08-07, and there are no releases. There is no version pin to hold, so an upgrade means pulling main and re-reading the code. For a research framework with three active subprojects, that is a real ongoing cost. The current repository includes `train_inference.py` and a documented Quick Start; verify that their environment and data preparation work in your setting. The second is whether the few-shot path works for your domain. The third is whether the influence-guided branch has a usable implementation, since it is the feature with the least documentation and the highest computational cost.
Editorial conclusion
TimeCraft is for research and applied ML teams that need synthetic time series with domain control, text conditioning, or downstream-task targeting, and that can read a paper alongside the code. It is not for teams wanting a pip-installable data augmentation library, and it is not a substitute for collecting real data where collection is feasible. The repository now documents a Conda environment, dataset preparation and training workflows. Before adopting it, check the dependencies and configuration for the specific subproject, whether representative few-shot examples are available for your domain, and whether you can reproduce the relevant evaluation on your own data.
Frequently asked questions
What is microsoft/TimeCraft?
TimeCraft is a diffusion model based time series generation framework from Microsoft Research, built on three claims: cross-domain generalization through a universal latent space of semantic prototypes, text-based control through a multi-agent text generation system, and target-aware adaptation guided by influence functions. The repository is MIT licensed, written in Python, and has no GitHub releases.
What does the Prototype Assignment Module do in TimeCraft?
It is a lightweight module that computes domain-specific weights for the shared semantic prototypes using few-shot examples, producing a domain prompt that captures the target domain's characteristics without explicit labels or retraining. The prototypes themselves encode domain-invariant features such as trends and seasonality.
Which subprojects ship alongside TimeCraft?
Three are announced in the 2026 news section, each with a paper and a code directory: CaTSG for causal control through diffusion constraints, OATS for online data augmentation of Time Series Foundation Models, and Diff-MN for continuous generation from sparse irregular observations. The file tree also holds BRIDGE, DiGA, TarDiff and TimeDP directories.
How do I install microsoft/TimeCraft?
The current Quick Start instructs users to clone the repository and run `conda env create -f environment.yml`. It also documents data preparation and optional text-controlled and target-aware workflows; consult the relevant subproject instructions and dataset terms.
Does TimeCraft aim to match the training data distribution?
No, and that is the stated criticism it answers: many approaches focus only on replicating the training distribution without considering whether the generated data helps downstream tasks. TimeCraft's target-aware branch generates samples with the goal of improving downstream model performance, using an influence-guided diffusion mechanism that quantifies expected reduction in task-specific loss.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-timecraft)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-timecraft)Was this useful?