Graphify: A Local AST-Based Knowledge Graph for AI Coding Assistants
Turn any codebase, with its docs, SQL schemas, configs, and PDFs, into a queryable knowledge graph. A /graphify skill for Claude Code, Cursor, Codex, and Gemini CLI: local deterministic AST parsing, every edge explained, no vector store.
At a glance
- What is it?
- Graphify maps a codebase into a queryable knowledge graph using deterministic tree-sitter parsing, with no vector store. It targets developers using Claude Code, Cursor, Codex, and Gemini CLI who want to query code structure instead of grepping.
- Who is it for?
- Adopt Graphify if you work in a multi-file codebase inside an AI coding assistant and need deterministic, local answers about structure, imports, and calls without sending code to a model. Do not adopt it if you need semantic understanding of prose-heavy documentation or if your team cannot tolerate the overhead of a separate graph.json that must be regenerated on code changes.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
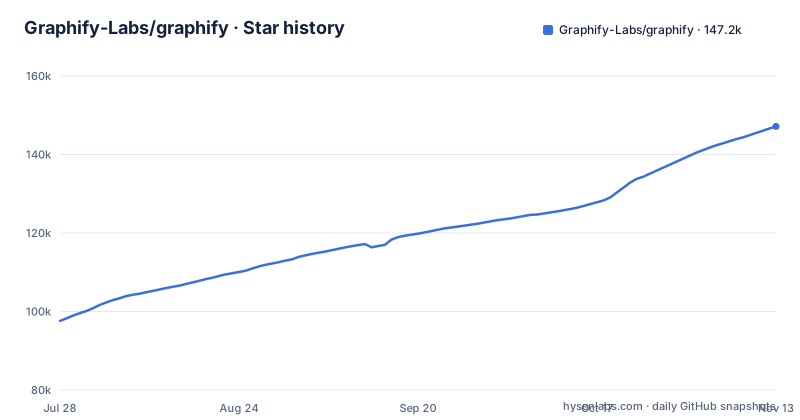
- Graphify-Labs/graphify147,160 ★ · +49,548
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| Graphify-Labs/graphify | 97.6k | 147.2k |
49,548 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Graphify Solves and Who It Is For
Graphify addresses the problem of navigating a large codebase where grep and file-by-file reading are slow and lose the connections between symbols. It builds a knowledge graph from your code, docs, SQL schemas, configs, and PDFs, and lets you query it with plain-language questions or path queries. The target user is a developer working inside an AI coding assistant like Claude Code, Cursor, Codex, or Gemini CLI, who wants to ask 'what does this function depend on?' or 'how do these two modules connect?' without manually tracing references. The README positions it as an alternative to 'grepping through files', and the examples show commands like `graphify explain "APIRouter"` returning node details and connections. This is for teams that value deterministic, local analysis over embedding-based retrieval, and who are comfortable with a CLI-driven workflow rather than a background service.
The Mechanism: Tree-Sitter AST, Not Embeddings
The core mechanism is deterministic parsing with tree-sitter AST. The README states that code is parsed locally, with no LLM involved and nothing leaving your machine. This is a fundamental difference from vector-based tools: there are no embeddings and no vector store. Instead, the graph is built from explicit syntactic relationships: calls, imports, inherits, and mixes_in, resolved across approximately 40 languages. Each edge in the graph carries a confidence tag: EXTRACTED means the relationship is explicit in the source, while INFERRED means it was derived through graphify's resolution logic. This distinction is important because it tells you whether a connection was directly read from code or guessed by the tool. The graph is stored in graph.json, which you can query without re-reading your files. This design means the graph is reproducible and auditable, but it also means that semantic understanding of prose, like the intent behind a comment or the meaning of a PDF, is out of scope unless you configure a separate semantic pass that calls a model.
Getting Started: Install, Register, and Query
The README gives a 30-second setup. You install the CLI with `uv tool install graphifyy` or `pipx install graphifyy`. Then you run `graphify install` to register the skill with your AI assistant. After that, in the assistant you type `/graphify .` to map the current directory. The output is three files in a `graphify-out/` directory: `graph.html` for interactive browsing, `GRAPH_REPORT.md` which summarizes key concepts, surprising connections, and suggested questions, and `graph.json` which holds the full graph. You can then run commands like `graphify explain "APIRouter"` to see a node's source location, community, degree, and its connections with edge tags. There is also `graphify path "FastAPI" "ModelField"` which returns the shortest path between two nodes, and `graphify query "<question>"` which returns a scoped subgraph. The CLI is the primary interface, and the skill registration is what ties it into your assistant. The commands are concrete and the output format is plain text, which fits a terminal workflow.
Edge Confidence and the Limits of Inference
The edge confidence tags are a genuine strength but also a limitation. EXTRACTED edges are reliable because they come directly from the source code, such as an import statement or a method call that is syntactically present. INFERRED edges are derived by graphify's resolution, which means they can be wrong or miss context that a human would catch. The README describes INFERRED edges as 'resolved by graphify'. This is a potential failure mode: if you rely on an INFERRED edge to understand a dependency, you might be misled. The example output shows `--> RequestValidationError [uses] [INFERRED]`, which suggests that the tool can detect usage even when it is not a direct call, but the confidence tag is your only clue. For a codebase with heavy metaprogramming, dynamic dispatch, or reflection, the AST-based approach will miss relationships that only exist at runtime. You should treat INFERRED edges as hypotheses to verify, not facts.
Beyond Code: Docs, PDFs, and the Semantic Pass
Graphify is not limited to code. The README states that docs, PDFs, images, and video can map into the same graph, but with a key caveat: these require a semantic pass that uses your assistant's model or a configured API key. This means the local-first guarantee only applies to code parsing. If you include PDFs or images, data leaves your machine and you incur API costs. This split is a trade-off: you get a unified graph, but the trust model changes depending on the file type. For a code-only project, nothing leaves your machine. For a project with documentation, you must decide whether the benefit of having PDFs in the graph is worth sending them to an external model.
Performance Claims and What They Don't Tell You
The repository has a BENCHMARKS.md at its top level. Any figures the project publishes there are self-reported and should be checked against your own task, which for most readers is navigating code rather than retrieving long-term memory.
Alternatives and the Vector Store Divide
The main alternative to Graphify is a vector-based retrieval tool. The difference in approach is fundamental: vector stores embed chunks of text into high-dimensional vectors and retrieve by similarity, which is good for fuzzy semantic search but bad for exact structural queries like 'what imports this module?'. Graphify builds an explicit graph with typed edges, which is better for tracing dependencies and understanding architecture. Another alternative is a traditional code search tool like ripgrep or ctags, which are faster and simpler but provide no graph structure. Graphify's value proposition is that it gives you the graph without a vector store. If your primary need is semantic search over docs, a vector store is the right tool. If your primary need is structural understanding of code, Graphify is a fit.
Maintenance, Licensing, and Upgrade Considerations
Graphify is released under the Apache-2.0 license (the repository also ships LICENSE-MIT and NOTICE files), which permits use, modification, and distribution, including in commercial products. The project is actively developed, with the last push on 2026-11-02 and releases v0.9.101, v0.9.100, and v0.9.99 within days of each other. This high release cadence suggests fast iteration, but it also means you should expect frequent changes and potential breaking changes between versions. The default branch is named 'v8'. The installation method via `uv tool install graphifyy` suggests the package is published on PyPI under the name 'graphifyy' (note the double 'y'), which is different from the repository name. This could be a source of confusion when searching for the package. Check the CHANGELOG.md or release notes before upgrading. Budget time for testing new versions before adopting them in a production workflow.
Editorial conclusion
Adopt Graphify if you work in a multi-file codebase inside an AI coding assistant and need deterministic, local answers about structure, imports, and calls without sending code to a model. Do not adopt it if you need semantic understanding of prose-heavy documentation or if your team cannot tolerate the overhead of a separate graph.json that must be regenerated on code changes. Before committing, verify that your primary languages are covered by the ~40 tree-sitter grammars, test the quality of INFERRED edges on your own code, and confirm that the CLI's output formats (graph.html, GRAPH_REPORT.md, graph.json) integrate with your existing review workflow. The project is under active development with frequent releases, so check the changelog between versions for breaking changes.
Frequently asked questions
What is Graphify used for?
It turns a folder of code, docs, papers, images, or videos into a knowledge graph you can query instead of grepping. You type /graphify in your assistant and get three files: graph.html, GRAPH_REPORT.md, and graph.json.
Is Graphify safe to use?
Code is parsed locally with tree-sitter, deterministically and with no LLM, so nothing leaves your machine for source files. Docs, PDFs, images, and video go through a semantic pass that uses your assistant's model or a configured API key, and the container image serves the MCP server on 0.0.0.0 port 8080.
Is Graphify open source?
The project is Apache-2.0 and the package graphifyy is published on PyPI, with the repository shipping LICENSE, LICENSE-MIT, and NOTICE. The Dockerfile builds the MCP server from source so the image includes the Streamable HTTP transport even before it lands on PyPI.
how to use graphify with claude code
Install the CLI with `uv tool install graphifyy` or pipx, run `graphify install` to register the skill with your assistant, then type `/graphify .` in Claude Code. The result lands in graphify-out/ as graph.html, GRAPH_REPORT.md, and graph.json, and you query it with graphify query, graphify path, and graphify explain.
how to use graphify with cursor
The same two steps apply, since the skill works in Claude Code, Cursor, Codex, Gemini CLI, GitHub Copilot, and 20+ more. The package description names Claude Code, CodeBuddy, Codex, OpenCode, Kilo Code, Cursor, Gemini CLI, Aider, OpenClaw, Factory Droid, Trae, Hermes, Kiro, Pi, Devin CLI, and Google Antigravity.
What are the key differences between Obsidian and Graphify?
Graphify is described as parsing code with tree-sitter into a graph whose edges are tagged EXTRACTED or INFERRED, with no embeddings and no vector store, with Leiden communities and labels that need no LLM, queried through graphify query, graphify path, and graphify explain.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- 2 Agent Skills Every Frontend Developer Should Trydev.to · Oct 20, 2026 · 21 points · 3 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/graphify-labs-graphify)
[](https://hysenlabs.com/projects/graphify-labs-graphify)Star history chart for your README
[](https://hysenlabs.com/projects/graphify-labs-graphify)Was this useful?