vAttention: KV-Cache Memory Management That Keeps Attention Kernels Unmodified
Dynamic Memory Management for Serving LLMs without PagedAttention
At a glance
- What is it?
- Microsoft's vAttention uses CUDA virtual memory APIs to allocate KV-cache physical memory on demand while keeping virtual addresses contiguous, so FlashAttention and FlashInfer kernels can run without paged rewrites. It is a research artifact tied to specific CUDA, PyTorch and GPU versions, and it ships a patched NVIDIA UVM driver for sub-2MB pages.
- Who is it for?
- Adopt vAttention only if you are running Linux with an A100, CUDA 12.1 or later, PyTorch 2.3.0 and Python 3.10, and you are willing to build libtorch, Sarathi-Serve and the allocator from source. Skip it if you need a supported production serving stack, if you depend on non-NVIDIA accelerators, or if you cannot replace the CUDA UVM driver and still want 64KB, 128KB or 256KB pages.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 83 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
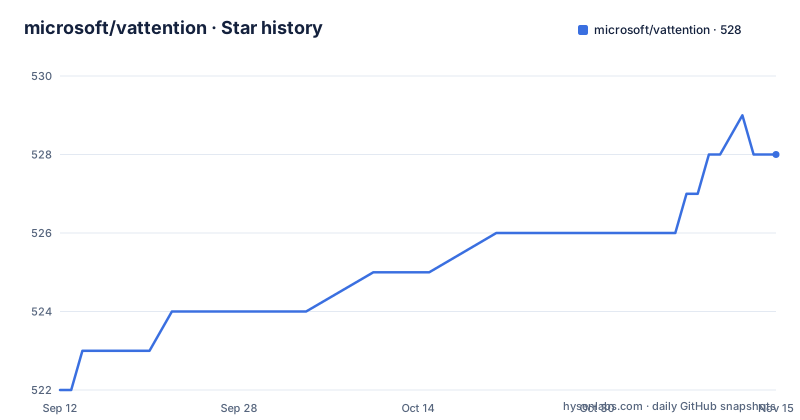
- microsoft/vattention528 ★ · +6
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| microsoft/vattention | 522 | 528 |
6 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem vAttention targets: KV-cache fragmentation without kernel rewrites
Serving an LLM means holding a KV cache whose size depends on how many tokens each request has generated so far. PagedAttention, the approach popularized by vLLM, solves the resulting memory fragmentation by implementing demand paging in user space. The cost is that attention kernels must be rewritten to gather non-contiguous blocks, and the README states plainly that PagedAttention "requires rewriting custom kernels to support dynamic memory allocation." vAttention takes the opposite route. It decouples virtual memory allocation from physical memory allocation using the CUDA virtual memory APIs, allocating physical memory on demand while retaining contiguity in virtual memory. The target reader is an engineer who wants dynamic KV-cache growth but does not want to maintain a fork of FlashAttention or FlashInfer. The README also claims performance improvements over PagedAttention "especially for prefill-bound workloads," and points to the arXiv paper for the numbers. That claim is not substantiated in the repository text itself, so treat it as a pointer to the paper rather than a measured result you can verify from the code alone.
How the allocator splits virtual and physical memory
The mechanism rests on the CUDA driver's virtual memory management API. Instead of asking the driver for a contiguous physical block sized to the maximum sequence length, vAttention reserves a contiguous virtual address range and maps physical pages into it as requests grow. Because the virtual range stays contiguous, the attention kernel sees what looks like an ordinary dense KV cache. No block table, no gather indices, no kernel modification. The repository layout reflects this split: the vattention directory holds the allocator itself, written in C, and it must be linked against libtorch, which is why the install instructions download a libtorch build before building anything. The allocator is not a standalone server. It is consumed by sarathi-lean, a modified Sarathi-Serve that supports both PagedAttention and vAttention style memory management, so the same serving loop can be run against either allocator for comparison. The README notes one optimization worth knowing about: memory allocation can be overlapped with compute, and the _sync suffix on a backend knob disables that overlap, which "may be useful for benchmarking." In other words, the default asynchronous path is the intended production behavior, and _sync exists to make measurements easier to reason about.
Installation: libtorch, Sarathi-Serve, then the allocator
The README specifies PyTorch 2.3.0 and CUDA 12.1 or later, with the caveat that other CUDA versions "may or may not work." Testing was done on Linux with A100 GPUs and Python 3.10. The sequence is: create a conda environment with python=3.10, download libtorch 2.3.0+cu121 and unzip it, build sarathi-lean with pip install -e . plus the FlashInfer extra index URL, then build the allocator with LIBTORCH_PATH=<path to libtorch dir> python setup.py install. The libtorch version must match the torch version, and the README says only v2.3.0 has been tested. That is a narrow window. If your cluster is on a newer PyTorch, you are outside the documented configuration. Attention backends are selected by editing an attention_backends list in the benchmark scripts. Supported names are fa_paged_[block_size], fi_paged_[block_size], fa_vattn_[page_size], fi_vattn_[page_size], and the _sync variants, where fa is FlashAttention (tested at v2.5.9) and fi is FlashInfer (tested at v0.0.6). Page sizes for vAttention are 64KB, 128KB, 256KB and 2MB, written for example as fa_vattn_256kb or fi_vattn_2mb_sync. The README recommends block size 256 for FlashAttention and 16 for FlashInfer, based on the authors' observation that those perform best.
The custom UVM driver is the sharpest constraint
NVIDIA CUDA drivers allocate memory only at the granularity of large pages, 2MB or above. If you want 64KB, 128KB or 256KB pages, the README directs you to replace the default CUDA UVM driver with the modified one in nvidia-vattn-uvm-driver, following that directory's README. Replacing a kernel-mode driver is not a routine dependency install. It affects every CUDA workload on the machine, not just vAttention, and it is the kind of change that belongs on a dedicated node rather than a shared one. The README does note that driver replacement is not required if you use only 2MB pages, which gives you a way to evaluate the allocator without touching the driver stack. That is the sensible first experiment. The second constraint is hardware: testing was on A100 GPUs, and no other accelerator is mentioned. The third is the missing release history. The repository has no published GitHub releases, so there is no tagged version to pin, no changelog to read, and no upgrade path other than tracking the main branch. For a component that sits underneath your serving loop, that matters more than it would for a CLI tool.
When vAttention is the wrong tool
If your serving stack is already built around PagedAttention and its block managers, vAttention does not slot in as a drop-in replacement. It is integrated with Sarathi-Serve in this repository, and the README describes sarathi-lean as a modified version of that system. You are adopting a serving system, not a library you can call from your own scheduler. If you need a supported, versioned artifact with a release cadence, this repository does not provide one. If you run on non-A100 hardware, or on a PyTorch version other than 2.3.0, you are outside the tested configuration and the README says so explicitly. And if your workload is decode-heavy rather than prefill-bound, the README's performance argument is aimed at prefill, so the motivation is weaker. The repository also carries an experimental backend, vattention_flashinfer_wrapper.py, which the README describes as demonstrating portability by mixing FlashInfer prefill with FlashAttention decode. Experimental is the README's own word. Treat that path as a demonstration, not a default.
How it differs from PagedAttention in practice
The comparison is not about which one allocates memory more cleverly. It is about where the complexity lands. PagedAttention pushes the problem into the kernels: you get demand paging, and in exchange every attention kernel must understand blocks and gather from them. vAttention pushes the problem into the driver and the allocator: you get demand paging, and in exchange you depend on CUDA virtual memory APIs and, for small pages, a patched UVM driver. Both approaches appear in this repository side by side, since sarathi-lean supports PagedAttention and vAttention memory management, and the benchmark knobs let you select fa_paged_256 against fa_vattn_256kb in the same harness. That is the useful part of the repository for an evaluator: you can compare the two allocators on your own trace without rewriting anything. The trade is asymmetric in one respect. PagedAttention's kernel work is a one-time cost paid by kernel authors and then reused broadly across hardware. vAttention's driver dependency is paid by every operator who wants small pages, on every machine, and it is tied to a specific GPU generation in the documentation.
Benchmarks, the OpenAI-compatible endpoint, and what to check first
Two benchmark scripts are provided. benchmark_e2e_dynamic_trace.py runs 256 requests from the arxive dataset at qps 0.4, 0.8, 1, 2, 4 and 6 with Poisson arrivals. benchmark_e2e_static_trace.py runs 50 requests at context lengths 32k, 64k and 128k with prefill-to-decode ratios of 500, 100 and 50, and is described as reproducing the paper's makespan results. Both accept a --test flag for a setup check before a full run, and results land in experiments/e2e_static_eval or experiments/e2e_dynamic_eval, parsed by process_e2e_static.py or process_e2e_dynamic.py. Configuration knobs are documented in sarathi-lean/sarathi/benchmark/config/default.yml. Model configurations live in scripts/utils.py, and the README says all Yi and Llama family models are expected to work. There is also an OpenAI-compatible API started with python -m sara from inside sarathi-lean, intended for use with benchmarking tools such as metron. Running --test first is the cheapest way to confirm that libtorch, the allocator and the backend knobs line up before you spend GPU hours on a 128k-context static trace. The repository is MIT licensed, which is permissive, but note that it builds against and redistributes nothing from NVIDIA; the UVM driver directory contains a modified driver, and the terms governing NVIDIA driver modification and redistribution are a separate question from the MIT licence on this code.
Editorial conclusion
Adopt vAttention only if you are running Linux with an A100, CUDA 12.1 or later, PyTorch 2.3.0 and Python 3.10, and you are willing to build libtorch, Sarathi-Serve and the allocator from source. Skip it if you need a supported production serving stack, if you depend on non-NVIDIA accelerators, or if you cannot replace the CUDA UVM driver and still want 64KB, 128KB or 256KB pages. Before committing, verify that your driver installation path matches nvidia-vattn-uvm-driver/README.md, that your attention backend name resolves to a supported knob such as fa_vattn_256kb, and that your target model appears in scripts/utils.py.
Frequently asked questions
How does vAttention differ from PagedAttention?
vAttention decouples virtual and physical memory using the CUDA virtual memory APIs, so physical pages are allocated on demand while the KV cache stays contiguous in virtual space. PagedAttention does demand paging in user space, which requires rewriting attention kernels to handle non-contiguous memory.
What are the version requirements for building vAttention?
PyTorch 2.3.0 and CUDA 12.1, with later CUDA versions possibly working. The libtorch download must match the PyTorch version, and testing was done on the Linux kernel with A100 GPUs and Python 3.10.
Why does the repository include a modified Sarathi-Serve?
The modified serving system supports both PagedAttention and vAttention style memory management, so the same stack can run either approach with everything else held constant. Sarathi-Serve itself was published at OSDI 2024 as a separate project.
What do the two benchmark trace scripts measure?
The dynamic script runs 256 requests from the arXiv dataset at query rates from 0.4 to 6 with Poisson arrivals, which is a load test. The static script runs 50 requests at context lengths of 32k, 64k and 128k with prefill-to-decode ratios of 500, 100 and 50, and reproduces the paper's makespan results.
What does the _sync suffix in a vAttention backend name do?
It disables the optimisation that overlaps memory allocation with computation. The documentation recommends asynchronous allocation, so leave the suffix off unless you are specifically benchmarking without the overlap.
Why do I need the custom NVIDIA UVM driver?
Only for page sizes below 2MB. CUDA drivers allocate memory only at the granularity of large pages, so 64KB, 128KB and 256KB pages require replacing the default driver. It is not needed if you use 2MB pages only.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-vattention)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-vattention)Was this useful?