PDF.js: The Browser PDF Engine That Renders Without a Server
GitHub describes it as PDF Reader in JavaScript. The repository metadata lists JavaScript as its primary language. The metadata lists the Apache-2.0 license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- Mozilla's PDF.js parses and draws PDFs entirely in JavaScript, making it the default choice for in-browser viewing. This review covers its architecture, build process, testing tools, and the trade-offs you accept when you adopt it.
- Who is it for?
- Adopt PDF.js if you need to display PDFs in a web page without a server-side renderer, and you can rely on modern browsers. Skip it if your users are on legacy browsers that lack native JavaScript features, or if you need to extract structured data beyond what the viewer exposes.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
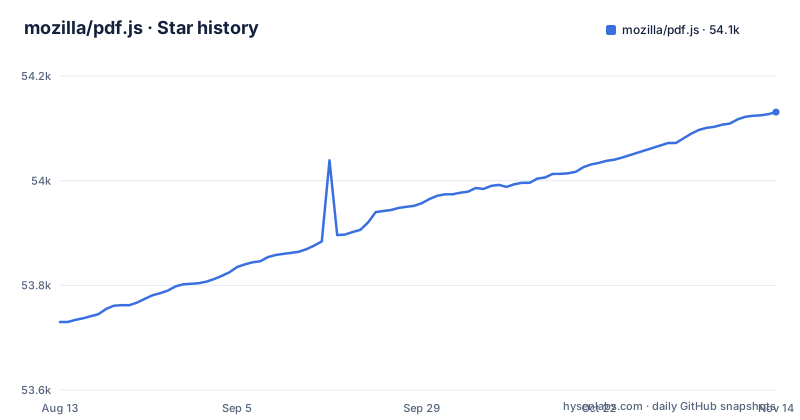
Star history
- mozilla/pdf.js54,131 ★ · +401
| Repository | 2026-08-13 | 2026-11-14 |
|---|---|---|
| mozilla/pdf.js | 53.7k | 54.1k |
401 Stars in the last 93 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What PDF.js Actually Does
PDF.js is a PDF viewer written in JavaScript and HTML5. It solves the problem of displaying PDFs in a browser without a native plugin or a server-side conversion step. The library parses the PDF file structure, interprets the page content streams, and renders the result to a canvas. For engineers, the value is that the entire pipeline, from file fetch to pixels, happens client-side. That removes a class of server dependencies and lets you host static files that still render as documents. The intended audience is anyone building a web application that must show PDFs: document management systems, e-commerce invoice viewers, or internal dashboards. It is also the engine inside Firefox itself, which means it gets constant real-world exercise. The project is community-driven and supported by Mozilla, and the repository is active, with releases tagged monthly, such as v6.5.438 in November 2026. The core mechanism is a JavaScript parser and renderer, not a wrapper around a native binary.
How the Rendering Pipeline Is Structured
The repository is split into source files under `src/` that get bundled into two production scripts: `pdf.js` and `pdf.worker.js`. The README is explicit that both are needed, but only `pdf.js` must be included in your page, because `pdf.worker.js` is loaded automatically by `pdf.js`. The debugger at `internal-viewer/web/debugger.html` lets you inspect the internal document structure, which is useful for understanding how the parser sees your files.
Getting It Running: Build Commands and the Local Server
To get a local copy, clone the repository and run `npm install`. The README warns that you must start a local web server because some browsers block `file://` URLs for PDFs. The command is `npx gulp server`, which serves the viewer at `http://localhost:8888/web/viewer.html`. That gives you a development viewer with all test PDFs listed on the right side at `http://localhost:8888/test/pdfs/?frame`. For production, you run `npx gulp generic` to bundle the source into `build/generic/build/`. If you need to support older browsers, you run `npx gulp generic-legacy` instead, which generates a legacy build in `build/generic-legacy/build/`. The README notes that the generated files are large and should be minified for production. The build is driven by gulp tasks. The `generic` target produces the two scripts, and you include only `pdf.js` in your HTML. The `legacy` variant exists because the modern build assumes native support for the latest JavaScript features, which older browsers lack. That is a concrete constraint: you must pick the right build for your audience.
The Testing and Coverage Toolchain Is a Hidden Strength
The README spends a significant amount of space on code coverage, which is unusual and worth noting. The project uses `babel-plugin-istanbul` to instrument the bundled code, and it supports multiple test types: browser unit tests, Node unit tests, Puppeteer integration tests, and reference tests. You can run any of them with a `--coverage` flag, for example `npx gulp unittest --coverage` or `npx gulp integrationtest --coverage`. The output defaults to an LCOV file in `build/coverage`, but you can switch to HTML with `--coverage-formats html` or combine formats like `info,html`. There is also a `coverage_search` task that maps a specific source line or function to the reference tests that exercise it. For instance, `npx gulp coverage_search --code="canvas.js::205"` tells you which ref tests touch that line. This is a practical tool for debugging a rendering issue: you can find the exact test that covers a code path and run only that test with `npx gulp browsertest --code="canvas.js::205"`. The per-test index is published to a separate repository and downloaded on demand, so you do not need to build coverage locally to search. This tooling is a genuine advantage for maintainers, but it also signals that the project is large and complex enough to need such precise test targeting.
Where It Falls Short: Browser Dependency and PDF Complexity
The most obvious limitation is that the README presents PDF.js as a viewer built with HTML5, so it is aimed at in-browser display; the repository also contains an examples/node directory, so check it before ruling out server-side use. The second limitation is browser support. The modern build assumes native support for the latest JavaScript features, and the README points to a wiki FAQ for the exact support matrix. If your user base includes older browsers, you must use the `generic-legacy` build, but that build still has limits. The third limitation is rendering fidelity. PDF is a complex format with many features, and the project's own test suite includes reference tests that compare rendered output to expected images. That implies that some PDFs may not render perfectly, and you should test your specific files. The README also notes that you cannot open PDFs via `file://` in some browsers, which is a practical deployment constraint for offline or local-file use cases. These are not fatal flaws, but they are real boundaries you must verify before adopting the library.
The Alternative: A Native Viewer or a Server-Side Renderer
The main alternative to PDF.js is using the browser's built-in PDF viewer, which in Firefox is actually PDF.js itself. In Chrome and Edge, the native viewer is a separate implementation, and it is not scriptable in the same way. If you need to embed a PDF in a custom interface with your own controls, PDF.js gives you a JavaScript API that the native viewer does not. Another alternative is a server-side renderer like Ghostscript or Poppler, which converts PDFs to images or text on the server and sends the results to the browser. That approach differs fundamentally: the heavy lifting moves off the client, which can reduce client-side CPU usage but adds server load and latency. PDF.js keeps everything on the client, which is better for static hosting and privacy because the PDF never leaves the user's device. The trade-off is that the client must be capable of running the JavaScript, which is the browser support constraint mentioned above. If your users are on modern browsers, PDF.js is often the right call. If they are not, a server-side renderer might be more reliable, at the cost of infrastructure.
Maintenance and License: What You Inherit
PDF.js is licensed under Apache-2.0, which is permissive for commercial use, but you should read the full license text for your own legal review. The project is actively maintained, with a release cadence of roughly one minor version per month, as seen in v6.3.289 in August, v6.4.299 in October, and v6.5.438 in November 2026. That means you will need to track updates to get bug fixes and new features, but it also means the library is not abandoned. The maintenance cost for your team includes keeping up with those releases, because PDF rendering bugs are often fixed in new versions. The build system is gulp, which is not the default in new JavaScript projects, so your team may need to learn it if they are not familiar. The project also has a large test suite and a CI pipeline, which is a sign of engineering rigor, but it also means the codebase is large and not something you would fork lightly. The README mentions that the files are large and should be minified, so you must have a build step in your own deployment. Overall, the maintenance burden is moderate: you are adopting a mature, active library, but you must budget time for version upgrades and for testing your own PDFs against each new release.
Editorial conclusion
Adopt PDF.js if you need to display PDFs in a web page without a server-side renderer, and you can rely on modern browsers. Skip it if your users are on legacy browsers that lack native JavaScript features, or if you need to extract structured data beyond what the viewer exposes. Before committing, verify that your target browser supports the required JavaScript features, and check the wiki's FAQ for the exact support matrix. Then test your specific PDF corpus against the latest release, because rendering fidelity varies by file and version.
Frequently asked questions
What is PDF JS used for?
PDF.js is a Portable Document Format viewer built with HTML5, and the stated goal is a general-purpose, web standards-based platform for parsing and rendering PDFs. It is community-driven and supported by Mozilla.
Is PDF JS free?
The repository is licensed under Apache-2.0, so it is free to use, modify, and redistribute under those terms. The project is community-driven and looks for more contributors.
Where can I download the PDF.js file?
For the library itself, the documented route is to clone https://github.com/mozilla/pdf.js.git, run npm install, and build with npx gulp generic, which produces pdf.js and pdf.worker.js. An online demo is available at https://mozilla.github.io/pdf.js/web/viewer.html, but that is the viewer, not a library archive.
how to use pdf.js in html
Include pdf.js in the page and let it load the worker itself. Both files are needed, but only pdf.js needs to be included, since pdf.worker.js is loaded by pdf.js. Some browsers do not allow opening PDF files over a file:// URL, so serve the page over a local server.
what is pdf js viewer
The generic viewer is what npx gulp generic builds alongside the two production scripts. Two demos exist online: a modern browsers version at https://mozilla.github.io/pdf.js/web/viewer.html and an older browsers version at https://mozilla.github.io/pdf.js/legacy/web/viewer.html, since the modern build assumes native support for the latest JavaScript features.
how to install pdf js
The documented setup is a local copy from git, Node.js installed, then npm install for all dependencies, then npx gulp server to start a local web server. The viewer is then reached at http://localhost:8888/web/viewer.html. The instructions assume the latest version of Mozilla Firefox.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- PDF Reader in JavaScriptHacker News · Oct 30, 2026 · 2 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mozilla-pdf-js)Star history chart for your README
[](https://hysenlabs.com/projects/mozilla-pdf-js)Was this useful?