shuorenhua: A Chinese-First Rewrite Skill That Protects Facts While Cutting AI Tone
AI skill Chinese-first rewrite skill for Codex / Claude Code / Cursor / ChatGPT, removes AI tone, preserves facts.
At a glance
- What is it?
- shuorenhua is a Chinese-first rewrite skill for Codex, Claude Code, Cursor, and ChatGPT. It strips AI-flavored phrasing without touching numbers, versions, commands, or factual relations, backed by a 111-case benchmark and a four-tier release gate.
- Who is it for?
- Adopt shuorenhua if you write Chinese-facing text with AI tools and need tone cleanup without fact drift, especially for READMEs, release notes, issue replies, or API references. Skip it if you write primarily in English or need aggressive rewriting of long-form prose; the bounded scope default is conservative.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
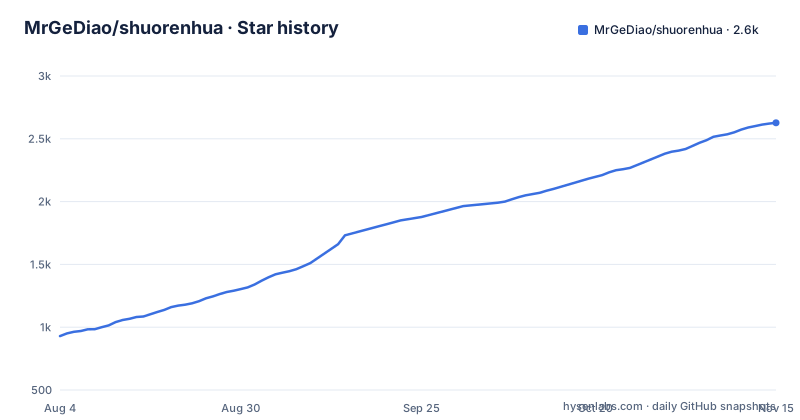
- MrGeDiao/shuorenhua2,627 ★ · +1,698
| Repository | 2026-08-04 | 2026-11-15 |
|---|---|---|
| MrGeDiao/shuorenhua | 929 | 2.6k |
1,698 Stars in the last 103 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: AI Tone in Chinese Text, and the Fact-Drift Trap
Chinese text generated by AI tools carries a recognizable flavor: template openers, performative politeness, engineer posturing, translationese, and unsourced authority. shuorenhua targets that tone. The README's own example shows the risk: a sentence about p95 latency dropping from 480ms to 160ms can be 'cleaned' into 'the optimization significantly reduced latency,' losing the numbers and the evidence. The project's core claim is that tone removal must not change facts. It is built for developers, maintainers, and writers who draft Chinese with AI and need output that sounds human without becoming inaccurate. The repository is a skill, not a standalone tool: it is a set of instructions and rules that an AI agent follows, not a Python script you run directly.
How It Works: Scenario Detection, Protected Spans, and Tiered Rewriting
The rewrite process is not a word-replacement table. The README describes a fixed order: determine the main scenario (chat, status, docs, public-writing), mark protected spans (numbers, versions, commands, citations, responsibility subjects, factual relations), judge hit strength (Tier 1/2/3) and rewrite intensity, handle sentence and paragraph patterns first, use the phrase list only as a fallback, then do a fidelity read-back. The 'fidelity contract' is explicit: numbers and their objects stay together, relations are not rewritten (potential is not implementation), and scope, condition, negation, modality, completion, direction, and intensity are treated as facts. Abstract information is not made concrete; missing information is flagged, not invented. A bidirectional check verifies that facts from the input can be found in the output and that new relations in the output trace back to input evidence. This mechanism is more disciplined than a simple style guide, but it depends on the agent following it correctly.
Getting It Running: Commands for Claude Code, Codex, and Others
Installation varies by agent. For Claude Code, the README gives two commands: /plugin marketplace add MrGeDiao/shuorenhua and /plugin install shuorenhua@shuorenhua. For Codex, you clone the repo and run a single command: codex exec -C . "读取 ./SKILL.md,按其中规则改写以下文本:……". Other agents that support the skills command can use npx skills add MrGeDiao/shuorenhua. There are three distribution tiers: mini (dist/shuorenhua-mini.md, under 1,500 characters, self-contained), lite (SKILL.md), and full (SKILL.md plus references/). The mini tier is for single sessions or tight context windows; full is for long-term projects and public text. The README also suggests adding a trigger rule to AGENTS.md to apply the skill automatically for '去 AI 味' or '说人话' tasks, while excluding code, logs, config, and command output.
The Fidelity Contract: What It Protects and What It Refuses to Do
The fidelity contract is the project's backbone. It lists five rules: numbers and their modifiers stay together, relations are not upgraded (potential stays potential), scope and modality are facts, abstract claims are not made concrete, and missing information is flagged rather than filled in. The README gives a concrete failure mode: '展示了云原生架构的潜力' must not become '采用了云原生架构'. This is a real constraint, not a slogan. The contract also defines two read-back directions: input facts must be recoverable in the output, and every new output relation must trace back to an input basis. This is a strong guard against the common rewrite failure where a sentence becomes fluent but the meaning shifts. However, the contract only works if the agent actually performs the read-back. The project provides a zero-dependency script, python3 automation/eval/hard_metrics.py, to check word retention, dash density, and protected spans, but that is for evaluation, not for every rewrite.
Scene Packs and Scope: Context-Specific Rules and Conservative Long-Form Editing
Different text types get different treatment. Scene Packs cover README, release note, forum post, issue reply, API reference, and FAQ. Each pack has a focus: release notes list changes and limitations without a release manifesto; issue replies state reproducibility first; API references protect endpoints, methods, fields, status codes, and recovery actions. For long-form text, three scopes define how much can be cut: structural allows deleting and rearranging whole sentences, bounded (the default for long public-writing) moves empty sentences to a 'suggested deletion (pending confirmation)' list, and in-place only lowers tone within sentences without removing any. This is a thoughtful answer to the problem of over-aggressive rewriting. The bounded default is conservative, which means it may not satisfy users who want a heavily condensed rewrite, but it reduces the risk of destroying rhythm and meaning.
Evaluation Rigor: A 111-Case Benchmark and a Four-Tier Release Gate
The project takes evaluation seriously. The benchmark has 111 cases: 61 SF (should fix) and 50 SNF (should not fix), plus 20 scene samples that are evaluated separately. There are also 8 HUMAN long-form residual comparisons, but they are only for observing false positives, not for setting a 'human' threshold. The release gate from v2.1.0 has four tiers: L1 hard constraints (fabrication, protected-span drift, attribution change, scope violation) must have zero failures; SNF mis-kill rate must stay below 10%; L2 style goals are reported per model; L3 style observations are recorded but do not block. Models are tested on a blind, shuffled benchmark without expected answers. The v2.3.1 release notes claim Opus passed with zero L1 failures and 57/61 SF, but DeepSeek V4 Pro was dropped due to a real L1 issue and run-to-run variance. This is an honest limitation: results are model-dependent, and you cannot assume the same quality on your own setup.
Limitations and the Wrong Tool Cases
shuorenhua is not a universal style fixer. It is Chinese-first; the README's English section is a brief summary, and the rules are built for Chinese text. If your output is primarily English, this skill is likely the wrong tool. The bounded scope default also means it will not aggressively shorten long text; if you need a heavy rewrite, you must explicitly request structural scope. Another limitation is model variance: the release notes document that DeepSeek V4 Pro failed a real L1 constraint and showed run-to-run variance, so the skill's reliability depends on the underlying model. The HUMAN corpus is missing docs and status samples, which the check_repo flags as a known gap. Finally, the corpus text and adaptations follow their own licenses, not the repo's MIT, so if you reuse that material, you must check those licenses separately.
Alternatives: Generic Style Prompts vs. Structured Skills
The obvious alternative is a custom prompt like 'rewrite this to sound more natural' or a style guide in your AGENTS.md. That approach has no protected-span mechanism, no scene packs, and no benchmark. It relies entirely on the model's interpretation, which is exactly where fact drift happens. Another alternative is a deterministic text-processing tool that strips specific phrases, but the README explicitly argues against a pure word-replacement table, because it cannot handle context or preserve relations. shuorenhua's difference is the combination of structured rules, a fidelity contract, and an evaluation suite. That is a real contrast: a prompt is a one-shot instruction; this skill is a multi-layer rule system with a verification step. For teams that value reproducibility, the benchmark and release gate provide a level of confidence that a plain prompt cannot.
Maintenance and Upgrade Cost, and License Notes
The project is actively maintained, with releases in August 2026 and a clear versioning scheme. Upgrading means pulling new releases, which can change behavior: v2.3.1 introduced a mini distribution, expanded Scene Packs, and changed the fidelity read-back to a clause-level ledger. That means your installed skill may behave differently after an update, so you should re-test on your own text. The Claude Code plugin is the easiest way to follow updates, but manual installation requires copying files or using symlinks. The license is MIT, which permits commercial use and modification, but the README notes that the HUMAN evaluation corpus does not fall under the repo's MIT license. That is a practical detail if you plan to reuse that corpus. The maintenance cost is low for a skill: it is mostly text files and a small Python script for evaluation. The real cost is verifying that each new version still meets your quality bar on your own models.
Editorial conclusion
Adopt shuorenhua if you write Chinese-facing text with AI tools and need tone cleanup without fact drift, especially for READMEs, release notes, issue replies, or API references. Skip it if you write primarily in English or need aggressive rewriting of long-form prose; the bounded scope default is conservative. Before adopting, verify the v2.3.1 benchmark results against your own model, since DeepSeek V4 Pro was dropped due to run-to-run variance, and check the missing docs and status HUMAN samples in the eval corpus. Confirm the MIT license fits your use, and note that the HUMAN corpus is not under MIT.
Frequently asked questions
Does shuorenhua detect whether text was written by AI?
No. The project states that it does not judge whether an article is AI-written and gives no guarantee about AI content levels or about avoiding detection. It is an editing skill for boilerplate, repeated setup and stiff phrasing.
How much change does shuorenhua make to normal Chinese text?
The evaluation set has 58 normal texts, and Claude Opus 5 produced 0 false edits on them across 136 targeted acceptance runs. Grok 4.6 covered only 11 of those 58, found no false edits, and that partial figure is not a full rate.
What happens to a claim like research shows when it has no source?
By default the attribution and the claim are both kept, with the missing source flagged outside the body when needed. It is only removed if you explicitly ask for unsourced claims to go, or name the rewrite-safe mode, so that deleting research shows alone cannot turn a claim into a verified fact.
Why does shuorenhua change long articles so little?
It is a known gap tracked in issue 16. Widening cleanup changed the strength of the author's judgement and the author's own terminology, which did not reach the release standard. Version 2.4.x cleans more but may change the meaning, so edits there need checking by hand.
Which files does a full shuorenhua install copy?
The three listed in runtime-files.json: SKILL.md, references/editing-guide.md and references/examples.md, with their relative paths kept. Repository development files do not update an installed copy, and the evaluation folder should not sit in the scanned skill directory.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mrgediao-shuorenhua)Star history chart for your README
[](https://hysenlabs.com/projects/mrgediao-shuorenhua)Was this useful?