Docling: A Document Parser That Treats PDFs as More Than Text
Get your documents ready for gen AI. Convert a document (CLI) This generates a .md file in the current directory containing structured document content.
At a glance
- What is it?
- Docling converts PDFs, Office files, emails, and even video into a unified structured document model. Its real value is the advanced PDF layout analysis and the breadth of export formats, but the model download and pipeline complexity are worth checking before you adopt it.
- Who is it for?
- Adopt Docling if you need to extract structure from heterogeneous document types, especially PDFs with complex layouts, tables, formulas, or scanned pages, and you want a single Python API or CLI that feeds directly into LangChain, LlamaIndex, or a local agent. Skip it if your pipeline only needs plain text extraction from simple PDFs, where a lighter tool avoids the model download and pipeline overhead.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
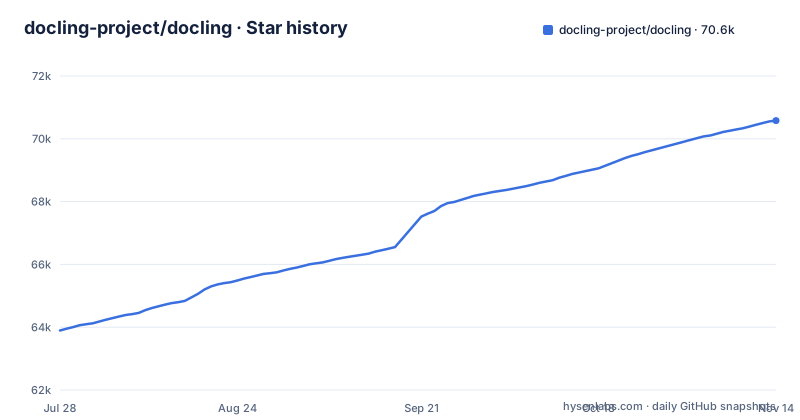
- docling-project/docling70,555 ★ · +6,660
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| docling-project/docling | 63.9k | 70.6k |
6,660 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A Parser, Not Just an Extractor
Docling solves a specific problem: turning messy, format-diverse documents into a clean, structured representation that generative AI systems can consume. It is not a text scraper. The README emphasizes advanced PDF understanding, including page layout, reading order, table structure, code, formulas, and image classification. That is a different league from a tool that just pulls raw text. The target user is an engineer building a retrieval pipeline, an agentic AI system, or a data preparation workflow that needs faithful document structure, not just characters. The unified DoclingDocument format is the core output, and from there you can export to Markdown, HTML, WebVTT, DocLang, DocTags or lossless JSON, and the README also lists support for application-specific XML schemas such as DocLang, USPTO patents, JATS articles and XBRL reports. That breadth is the main selling point.
The Pipeline: From File to Structured Document
The mechanism is a conversion pipeline. You feed a source, either a local path or a URL, into a DocumentConverter. The converter produces a DoclingDocument object, and the README lists layout analysis, table structure, OCR and vision language model support among its capabilities. The README shows a three-line Python example: create a converter, call convert, then export to markdown. The CLI wraps the same pipeline. The architecture is modular enough that you can swap in different pipelines, such as a vision language model (VLM) pipeline with GraniteDocling. The README points to the Docling Technical Report for details on Docling's inner workings.
Getting Started: CLI and Python in Two Commands
The quickstart is genuinely quick. Install with pip install docling. Then run docling https://arxiv.org/pdf/2206.01062. That command generates a .md file in the current directory. For a VLM-based pipeline, you add flags: docling --pipeline vlm --vlm-model granite_docling <url>. The Python API is equally direct: from docling.document_converter import DocumentConverter, create a converter, call convert, and export. The README notes that Python 3.9 support was dropped in version 2.70.0, so you need Python 3.10 or higher. It works on macOS, Linux, and Windows, on both x86_64 and arm64. The installation is simple, but the runtime behavior depends on which models the pipeline downloads on first use. The README does not list the exact model sizes, so budget for that.
Format Coverage: From PDF to Video, with Caveats
The feature list is impressive: PDF, DOCX, PPTX, XLSX, HTML, EPUB, Apple Pages, WAV, MP3, WebVTT, Box Notes, email formats (EML, MSG), images, LaTeX, plain text, and even video files (MP4, AVI, MOV, MKV, WebM). Video parsing includes an ASR transcript and representative keyframes. That is a wide net. But breadth does not mean equal depth. The README highlights advanced PDF understanding as a headline feature, and the technical report (arXiv:2408.09869) goes into detail. For video, the description says 'parsing' with transcript and keyframes, which is a different level of fidelity. If your corpus is mostly video, you should test how well the keyframe extraction and ASR handle your specific content. The same caution applies to email parsing and XBRL: the format is supported, but the quality of structure extraction will vary by document complexity.
Local Execution and Air-Gapped Environments
Docling can run locally, which is a major plus for sensitive data. The README explicitly lists 'local execution capabilities for sensitive data and air-gapped environments.' That means you can process documents without sending them to a cloud service. For many enterprise use cases, that is a hard requirement. The trade-off is that local execution implies you must download and manage the models yourself. The README does not specify the exact disk footprint or RAM usage for the default pipeline. If you are in an air-gapped environment, you will need a plan to pre-stage the model weights. The VLM pipeline, such as GraniteDocling, will be even heavier. So the local capability is real, but the operational cost is on you.
Integrations and the MCP Server
Docling does not stop at producing a markdown file. It has native integrations with LangChain, LlamaIndex, Crew AI, and Haystack. That means you can plug the parsed document directly into a retrieval or agent pipeline. There is also an MCP server, which lets any agent connect to Docling over the Model Context Protocol. And docling-serve exposes an API server for running Docling as a service. These integrations are the difference between a library and a platform. If your stack is already built on LangChain or LlamaIndex, Docling slots in without a custom adapter. The README mentions these as 'plug-and-play,' but you should verify the integration versions match your framework version, as these ecosystems move fast.
A Real Limitation: Model Licenses and Pipeline Complexity
The MIT license covers the codebase, but the README is explicit: 'For individual model usage, please refer to the model licenses found in the original packages.' That is a genuine caveat. The models that power the advanced PDF understanding, OCR, or VLM features are separate components with their own licenses. If you are building a commercial product, you cannot assume the whole stack is MIT. You must audit each model. Another limitation is the pipeline's computational weight. Running layout analysis, table recognition, and optional OCR on a large PDF is not free. The README does not provide benchmark numbers, so you will need to profile it on your own documents. For a simple text-only PDF, a lighter tool might be faster and simpler, but you lose the structural richness.
Alternatives: Comparing Approaches
The obvious alternative is a dedicated PDF-to-text tool like pdfplumber or PyMuPDF. Those tools are lightweight, fast, and give you direct access to text and coordinates, but they do not produce a unified document model with reading order, table structure, or formula recognition. They are extractors, not parsers. Another alternative is a commercial service like Azure Document Intelligence or AWS Textract. Those services offer high accuracy for tables and forms, but they are cloud-based, which conflicts with Docling's local execution advantage. The key difference is that Docling gives you a local, open-source pipeline with a consistent output format across many input types, while the alternatives either trade off structural depth (pdfplumber) or require sending data to a third party (Textract). Choose based on whether structure fidelity or data locality matters more.
Maintenance and Upgrade Cost
The project is actively maintained. The last push was November 2, 2026, and the recent releases show a rapid cadence: v2.146.0 on November 3, v2.145.0 on October 29 and v2.144.0 on October 28, 2026. That means the project is not stagnant, but it also means you should expect frequent updates. The README notes that Python 3.9 support was dropped in 2.70.0, which is a breaking change for older environments. Upgrading Docling may introduce new model versions or changed output formats, so you need a regression test suite for your document conversion outputs. The documentation and examples are referenced heavily, which suggests a mature project, but the fast release cycle is a maintenance consideration. Plan to pin versions in your environment and test upgrades carefully.
Editorial conclusion
Adopt Docling if you need to extract structure from heterogeneous document types, especially PDFs with complex layouts, tables, formulas, or scanned pages, and you want a single Python API or CLI that feeds directly into LangChain, LlamaIndex, or a local agent. Skip it if your pipeline only needs plain text extraction from simple PDFs, where a lighter tool avoids the model download and pipeline overhead. Before committing, verify the exact model dependencies for your target format, test the output quality on your own document set, and confirm that the MIT license covers the code while the individual model licenses are acceptable for your use case.
Frequently asked questions
What is docling used for?
Docling parses documents into one unified representation so downstream tools can use them. It handles PDF, DOCX, PPTX, XLSX, HTML, EPUB, Apple Pages, WAV, MP3, WebVTT, email, images, LaTeX and plain text, with advanced PDF work on layout, reading order, table structure, code, formulas and image classification.
Does Docling run locally?
Yes. Local execution for sensitive data and air-gapped environments is a listed feature, and the quickstart install is a single pip command. Python 3.9 support was dropped in version 2.70.0, so you need Python 3.10 or higher.
How do you use docling in Python?
Import DocumentConverter, give it a local path or a URL, and call convert. The result exposes a document object with an export_to_markdown method, and the same object can be exported to HTML, WebVTT, DocLang, DocTags or lossless JSON.
How do you install docling in Docker?
The repository ships a Dockerfile built on python:3.11-slim-bookworm. It installs the package with an extra index URL for the PyTorch CPU wheels, runs docling-tools models download to bake in the weights, and sets OMP_NUM_THREADS to 4. Removing that extra index URL is how you get the GPU requirements.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/docling-project-docling)Star history chart for your README
[](https://hysenlabs.com/projects/docling-project-docling)Community discussions
Was this useful?