graph-based-deep-learning-literature: a conference index you read on GitHub, not install
links to conference publications in graph-based deep learning
At a glance
- What is it?
- This repository is a curated set of links to graph-based deep learning papers, sorted by conference, year and topic, plus workshops, surveys and software lists. The judgement: it is useful for survey work and for tracking where a subfield publishes, but it is a reading list, not a library, and it carries no code you can run.
- Who is it for?
- Adopt it if you need a pre-sorted entry point into graph-based deep learning venues, or if you are building a reading group list and want the conference and year already separated. Do not adopt it if you need runnable code, dataset loaders, or anything that tracks papers outside the listed conferences and years.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 26 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
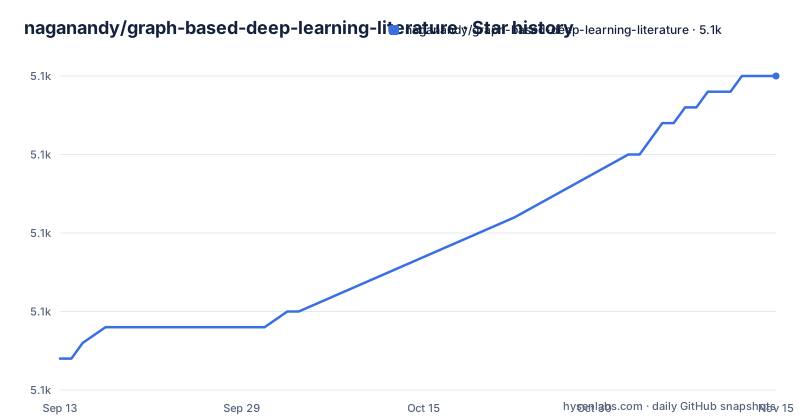
- naganandy/graph-based-deep-learning-literature5,115 ★ · +18
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| naganandy/graph-based-deep-learning-literature | 5.1k | 5.1k |
18 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the repository actually is, and what it is not
The README opens with a plain statement: the repository primarily contains links to conference publications in graph-based deep learning. That is the whole product. There is no package, no importable module, no dataset, and no evaluation harness. The primary language is listed as Jupyter Notebook. Treat the language field as metadata about the file mix, not as a promise of executable content.
The target reader is someone who needs to find papers rather than run them. A PhD student mapping a subfield before writing a related-work section. An engineer asked to evaluate whether graph neural networks apply to a problem, who wants the last three years of NeurIPS and ICLR entries in one place. A reading group picking a paper a week. For those people the value is in the sorting, not the content.
What it is not: a maintained implementation, a benchmark suite, a leaderboard, or a substitute for a literature search engine. If you need to reproduce a result, the link takes you to the paper, and the paper takes you to whatever code its authors released, if any. This repository does not intermediate that step.
How the link collection is organised: conference, year, then topic
The structure is a two-level index. The top level groups venues into categories, starting with Machine Learning Conferences (NeurIPS, ICML, ICLR) and Data Mining Conferences (KDD), and the README also points to Related Workshops, Surveys / Literature Reviews / Books, and Software / Libraries as sibling lists.
Under each venue, the README lists years as separate links. NeurIPS runs from 2026 back to 2015, with 2017 and earlier collapsed into a single 2017_and_Earlier file. ICML runs 2026 back to 2016. ICLR runs from a 2027 submissions page back to 2014. KDD's year list in the README starts at 2026. Each year link resolves to a README inside a folder path of the form conference-publications/folders/years/<year>/publications_<venue><yy>/README.md, so the naming is mechanical and predictable: publications_neurips25, publications_icml26, publications_iclr26, publications_kdd25.
The README states that within each conference and year, publications are organised into topic-specific categories. That is the part that saves time. A flat chronological dump of a conference would force you to scan everything; a topic split lets you read only the categories relevant to your question. The trade-off is that the category scheme is the maintainer's.
Getting to the papers: no install, just paths
There is no dependency file in the repository. Usage is navigation. The README gives the top-level entry point as conference-publications/README.md, which is the file that anchors the conference list.
From there the pattern is consistent enough that you can construct a path by hand. If you want ICLR 2023, the README links to conference-publications/folders/years/2023/publications_iclr23/README.md. For NeurIPS 2024 it is conference-publications/folders/years/2024/publications_neurips24/README.md. The older material is the exception: NeurIPS 2015, 2016 and 2017, ICML 2016 and 2017, and ICLR 2014, 2016 and 2017 all live inside conference-publications/folders/years/2017_and_Earlier/README.MD, addressed by anchor fragments such as #neurips-2017 or #icml-2016. Note the file extension on that one: README.MD in uppercase, unlike the lowercase README.md used elsewhere. If you are scripting against these paths, that inconsistency will break a naive glob.
The practical workflow is to clone the repository and grep it, or to read the per-year README in the browser. Because the content is Markdown links, a local clone plus ripgrep over the conference-publications directory gives you a searchable index of titles and URLs. The repository does not ship that tooling; you would be writing it.
Coverage is bounded by the venue list, and that is the main limitation
The index only contains what the maintainer has chosen to index. The README's conference list starts with NeurIPS, ICML, ICLR and KDD; check the full list before assuming a particular venue or journal is covered.
A second limit is freshness. The README already lists NeurIPS 2026 and an ICLR 2027 submissions page, which means the links appear around the publication cycle. Whether a given year file is complete or partially filled at any moment is not something the README states. The last push timestamp on the repository is 2026-10-20, so the index is being touched.
A third limit is that links rot. This is a link collection with no archived copies and no DOI resolution layer described. When a paper page moves or a proceedings URL changes, the entry becomes a dead link, and the only fix is a pull request. The repository has no published GitHub releases, so there is no versioned snapshot you can pin to and no changelog describing what changed between states.
Where it sits against Papers with Code and Semantic Scholar
The obvious alternatives are automated indexes. Papers with Code associates papers with implementations and links to code repositories directly on the paper page. Semantic Scholar provides citation graphs, author pages, and recommendation feeds. Both are search-first: you type a query and get ranked results.
This repository inverts that. It is browse-first and human-curated, organised by venue and year rather than by relevance score. The difference matters in two concrete ways. First, a curated conference list can surface a paper you did not know to search for, without depending on a search ranking. Second, the venue-and-year axis answers a question automated indexes handle poorly: what did this specific community publish in this specific cycle. If you are preparing a submission and want to know what the field looked like at the last edition of the conference, that axis is the point.
The cost of the curated approach is coverage and latency. An automated index picks up a paper when it appears on arXiv; a curated list picks it up when a human adds it.
Maintenance, contribution and the MIT licence
The repository is licensed MIT and is not archived. MIT is permissive: it allows reuse, modification and redistribution with the licence text retained, and it comes with no warranty. The licence applies to the repository contents, which here are the README files and their organisation. The papers themselves are not covered by this licence, and neither is any code those papers link to. If you plan to copy the category structure or the link lists into your own index, the MIT terms are what govern that reuse. This is a description of the licence text, not legal advice.
Maintenance is the real cost, and it is borne by whoever wants the list to stay current. Adding a paper means editing the correct per-year README under conference-publications/folders/years/<year>/publications_<venue><yy>/, placing the entry in the right topic category, and opening a pull request.
For a consumer, the ongoing cost is re-checking. Because there are no releases, you cannot say "I used the 2026.1 snapshot." You either clone and pin a commit hash yourself, or you accept that the list you read today may differ from the list next month. For a reading list that is usually fine. For anything you intend to cite as a fixed corpus, pin the commit.
Workshops, surveys and software as separate entry points
Three of the sibling lists are worth calling out because they serve different jobs than the conference index. The Related Workshops list is where you look for work that is early or niche enough not to have cleared a main track. The Surveys / Literature Reviews / Books list is the one to check before you start reading primary papers, since a survey can save you the pass entirely. The Software / Libraries list points at implementations, which is the closest this repository comes to being useful for someone who wants to run something, though it is a list of links and not a dependency manifest.
The software list is also the weakest of the three in terms of what the README tells us. The README links to conference-publications/folders/software/README.md but does not describe how libraries are selected, whether they are maintained, or what they cover. If you arrive from a search looking for a graph neural network library, that page is a starting point for further reading, not an evaluation.
The surveys list has the same property: it points, it does not summarise. Neither list carries the kind of metadata (last commit, licence, supported framework) that would let you pick between two libraries without leaving the repository.
Editorial conclusion
Adopt it if you need a pre-sorted entry point into graph-based deep learning venues, or if you are building a reading group list and want the conference and year already separated. Do not adopt it if you need runnable code, dataset loaders, or anything that tracks papers outside the listed conferences and years. Before relying on it, open the README for the specific year folder you care about and check whether the entries you expect are present, since the coverage is per conference and per year rather than comprehensive.
Frequently asked questions
What does the graph-based-deep-learning-literature repository contain?
Links to conference publications in graph-based deep learning, plus separate folders for related workshops, surveys and literature reviews and books, and software libraries. Within each conference and year, the publications are organised into topic-specific categories.
Which conferences does the graph deep learning literature index cover?
The root page splits venues into machine learning conferences and data mining conferences, and the machine learning group covers NeurIPS, ICML, and ICLR with a page per year, while the data mining group starts with KDD. Each venue name links to the conference site and each year links to a file inside the repository.
Do I need to install or run anything to use this literature index?
No. The top level contains only LICENSE.md, README.md, and the conference-publications directory, so the content is Markdown links to per-year files. The repository is MIT licensed and publishes no releases.
Where are the older graph deep learning papers listed?
Years from 2017 and earlier share a single file, reached through section anchors such as #neurips-2015 in the 2017_and_Earlier README, while 2018 entries for ICML and ICLR are addressed as icml-2018-jul and iclr-2018-may inside the 2018 folder.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/naganandy-graph-based-deep-learning-literature)Star history chart for your README
[](https://hysenlabs.com/projects/naganandy-graph-based-deep-learning-literature)Was this useful?