LLM-Beginner: A Six-Task Path from Transformer Mechanics to a Coding Agent
An ebook on LLMs and agents paired with 6 programming assignments: Transformer, mini-GPT, SFT/DPO, RAG, tool calling, and coding agents.
At a glance
- What is it?
- This repository pairs a 17-chapter Chinese ebook on large models and agents with six graded programming tasks, each with a self-check harness. It is a teaching resource, not a framework, and its value depends on your willingness to write code in src/.
- Who is it for?
- Adopt this if you are a learner with Python and deep learning basics who wants to build components by hand rather than only call libraries. Skip it if you need a ready-to-run agent framework or if you prefer English-only material, since the book and task instructions are in Chinese.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 69 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
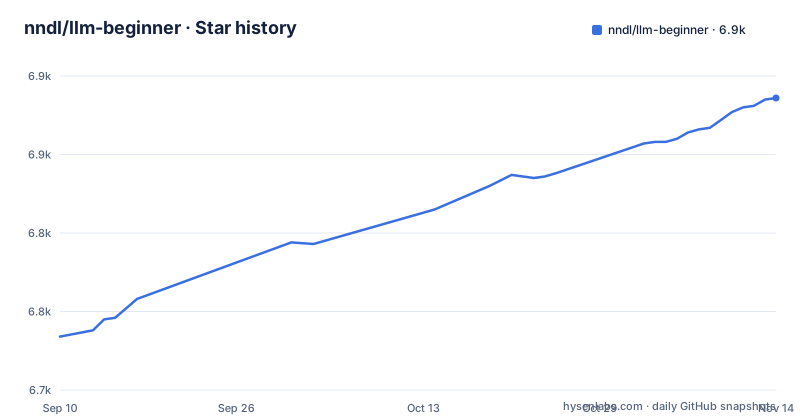
- nndl/llm-beginner6,886 ★ · +152
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| nndl/llm-beginner | 6.7k | 6.9k |
152 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Repository Actually Is
LLM-Beginner is a curriculum, not a software product. It contains a Chinese ebook, 《大模型与智能体》, written by Qiu Xipeng, and six programming tasks that move from a hand-written Transformer to a coding agent that can modify code and run tests. The intended reader is someone with Python and deep learning basics who wants to understand the internals of large language models. The ebook is in publication preparation, and the PDF is available as a release download. The tasks are independent of the book, so you can start with task one without reading the chapters. The repository is a rewrite of an earlier NLP-Beginner project, and it keeps the same step-by-step philosophy.
The Six Tasks and Their Progression
The tasks are ordered to build on each other, but each has its own README and can be done alone. Task one has you write scaled dot-product attention, multi-head attention, and a full encoder block, then run a Chinese sentiment classification task and visualize attention heatmaps. Task two moves to a decoder-only mini-GPT where you implement a simplified BPE tokenizer, rotary position embeddings, KV cache, and sampling strategies. Task three covers LoRA, supervised fine-tuning, and DPO. Task four builds a retrieval, reranking, and generation pipeline for document QA. Task five implements a ReAct loop with tool calling and error recovery. Task six asks you to construct an agent that edits code, runs tests, and iterates. The suggested time ranges from two weeks for task one to five or six weeks for task six, so the later tasks are substantial commitments.
How the Self-Check Mechanism Works
Each task directory follows the same layout: requirements.txt, a data/download.py script, an eval/run.py self-check, and an eval/tutor_prompt.md file. Your implementation goes in src/, and you must export classes and functions with the exact signatures listed in each task's README. The eval script imports your code by those signatures and checks key contracts, such as attention value correctness, recall, or task success rate. The results are written to eval/result.json in UTF-8. Each check item can be marked as passed, skipped, or failed. A skipped item means a prerequisite like a model checkpoint or data file is missing, not that your code is wrong. The README warns that the self-check is a lower-bound test of correctness, not a substitute for the comparison and ablation experiments described in each task.
Getting It Running: Commands and Environment
You need Python 3.10 or newer, with 3.11 or 3.12 recommended. Each task has its own requirements.txt, and you can install them in one shared environment or separate virtual environments. The standard flow, shown for task one, is to change into the task directory, run python data/download.py to fetch data or models, write your implementation in src/, then run python eval/run.py. Some download scripts take arguments: task two accepts --dataset poetry, tinystories, or skypile; task four accepts --skip-models; task six accepts --with-swebench. A critical constraint is that eval/run.py must run from inside the repository, because it depends on a shared _eval_harness.py at the root. Copying a single task directory outside the repo will break the import. For users in China, the README suggests setting HF_ENDPOINT to https://hf-mirror.com before downloading, and mentions that ModelScope is an alternative for many datasets and models.
The Role of Qwen and the Model Ecosystem
The Qwen series from Alibaba runs through the whole curriculum. Task three downloads Qwen2.5-0.5B for fine-tuning, and other tasks reference Qwen models in their data scripts. This choice gives a consistent model family, which makes comparisons across tasks meaningful. The trade-off is that you depend on Hugging Face or ModelScope for model weights, and the download scripts may need network configuration. The README notes that GPU memory requirements vary with model size, precision, sequence length, and batch size, and suggests starting with small configurations to get the pipeline working. For task two, the quick-start dataset is a 49KB Tang poetry file that runs in about five minutes, which is a sensible way to verify your code before moving to larger corpora like TinyStories or SkyPile-150B.
A Real Limitation: It Is a Teaching Tool, Not a Library
If you are looking for a reusable agent framework or a production-grade fine-tuning pipeline, this repository will frustrate you. The implementations are meant to be written by you, not imported. The README is explicit that you complete the code in src/, and the self-check only validates basic contracts. There is no pretrained model checkpoint provided for you to run out of the box; you must train or download what you need. The language is primarily Chinese, with English used only when data is significantly better, such as for some small-model pretraining corpora. That narrows the audience. Also, the book is in a pre-publication draft state, so content may change without notice, and the repository's last push date suggests ongoing updates.
Alternatives and What Makes This Different
The closest alternative is Karpathy's nanoGPT, which task two explicitly references. nanoGPT gives you a complete, working training loop for a GPT model, but it does not walk you through writing each component from scratch. LLM-Beginner instead asks you to implement BPE, RoPE, and KV cache yourself, then compare against the framework. Another alternative is the original NLP-Beginner repository, which this project was refactored from. If you want a hands-on course with graded self-checks and a companion book, this is structured for that. If you want a minimal codebase to hack on quickly, nanoGPT is lighter.
Maintenance, License, and Upgrade Cost
The repository is licensed under MIT, which means you can reuse the repository's code with minimal restrictions. The project is not archived, and the last push was in September 2026, with a book-pdf release on the same date. The README mentions that the book is updated as it is revised, so you should expect occasional changes to task instructions or data scripts. The shared _eval_harness.py is a coupling point: if you upgrade one task, you may need to keep the harness consistent. Pin your dependencies via requirements.txt if you want reproducibility. The tutor_prompt.md files are a low-cost way to get code reviews from external LLMs, which can reduce the burden of debugging alone.
Editorial conclusion
Adopt this if you are a learner with Python and deep learning basics who wants to build components by hand rather than only call libraries. Skip it if you need a ready-to-run agent framework or if you prefer English-only material, since the book and task instructions are in Chinese. Before starting, verify that your GPU memory can handle the models the tasks use, such as Qwen2.5-0.5B in task three, and confirm that you can download data from Hugging Face or set HF_ENDPOINT to a mirror. The self-check scripts only validate key contracts, so plan to run the broader experiments in each task README to actually learn the trade-offs.
Frequently asked questions
What is LLM-Beginner and who is it for?
It is a seventeen chapter Chinese book on large models and agents plus six Python programming tasks, from hand written attention to a coding agent. The book and the exercises can be studied separately, and the exercises expect Python and deep learning background rather than starting from zero.
How long does it take to work through the six LLM-Beginner tasks?
The suggested pace is two weeks for the Transformer task, three for mini-GPT, two to three for instruction tuning and preference alignment, two for retrieval, two for the tool calling agent and five to six for the coding agent, which adds up to about sixteen to eighteen weeks. The project presents those as pacing advice you can adjust to your background and to how large you run the experiments.
Do I need a GPU to start LLM-Beginner?
Not for the first run. The mini-GPT task ships a quick start dataset of about 49KB that gets a pipeline running in five minutes, and a roughly 100MB TinyStories tier that a CPU can train, while the SkyPile tier of 1GB or more wants a GPU. Memory use varies with model, precision, sequence length and batch size, so each task states its own resource needs.
How is LLM-Beginner code checked?
You write code in each task's src/ folder using the class and function names in that task's implementation contract, then run eval/run.py inside the repository, which imports your module by those names and writes results to eval/result.json. Items come back as pass, skip or fail, and a skip means a missing model, checkpoint or dataset rather than an error.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nndl-llm-beginner)Star history chart for your README
[](https://hysenlabs.com/projects/nndl-llm-beginner)Was this useful?