Nuclio: a serverless framework for real-time events and data processing
High-Performance Serverless event and data processing platform
At a glance
- What is it?
- Nuclio runs functions on Docker or Kubernetes and targets data, I/O and compute intensive workloads. It fits event-driven pipelines with Kafka, MQTT or HTTP triggers, and fits poorly if you want a managed cloud function service.
- Who is it for?
- Adopt Nuclio if you run event-driven functions on your own Docker host or Kubernetes cluster and need triggers for Kafka, MQTT, HTTP or timers, with the option of GPU execution. Do not adopt it if you want a fully managed cloud function service with no cluster to operate, or if your team has no container build pipeline and no appetite for maintaining one.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
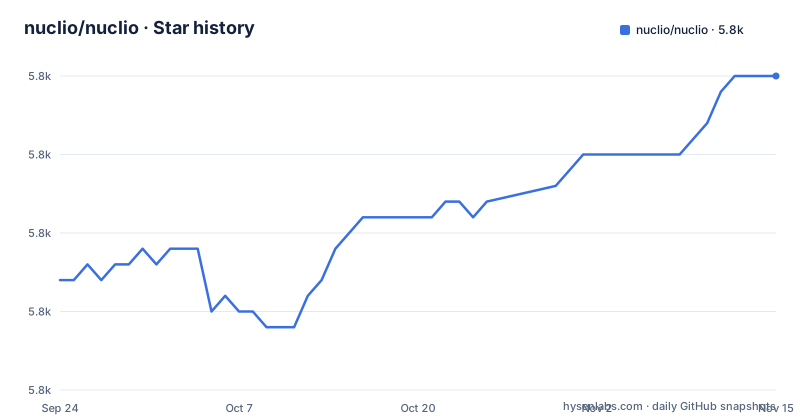
- nuclio/nuclio5,775 ★ · +13
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| nuclio/nuclio | 5.8k | 5.8k |
13 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What problem Nuclio solves, and for whom
The README frames the project around one sentence: "When this happens, do that." That is the whole contract. An event occurs (a record lands in Kafka, an HTTP request arrives, a timer expires) and Nuclio is responsible for the scaffolding between that event and a piece of code. The user supplies two things: what can trigger an event, and the code to run.
The target user is not someone writing a small webhook. The README describes the project as focused on data, I/O and compute intensive workloads, with support for execution over CPUs and GPUs, and lists Jupyter, Kubeflow and MLRun as integrations. In practice that means teams running inference, stream processing or record transformation who want the deployment ergonomics of functions without handing their data path to a cloud vendor. The README also states Nuclio can be used as a standalone Docker container or on top of an existing Kubernetes cluster, and through a managed service in the Iguazio Data Science Platform.
That positioning explains the trigger list. Kafka, MQTT, HTTP and timers are all first-class concerns in the README and in the repository itself: go.mod pulls in github.com/IBM/sarama for Kafka, github.com/eclipse/paho.mqtt.golang for MQTT, github.com/nats-io/nats.go for NATS, github.com/rabbitmq/amqp091-go for AMQP, plus AWS S3, Google Pub/Sub, Azure AMQP, Elasticsearch and OpenSearch clients. Those dependencies are the clearest evidence of what the project actually talks to. If your events live in one of those systems, Nuclio speaks the protocol natively rather than requiring you to write a bridge.
How Nuclio turns a trigger into a running container
The mechanism visible in the repository is a build-and-deploy loop. You describe a function (its handler, its runtime, its triggers), and Nuclio builds a container image for it and runs that image. When running outside an orchestration platform, the README says the dashboard "will simply deploy to the local Docker daemon." On Kubernetes, the deployment targets the cluster instead. The README states Nuclio is integrated with Kaniko, which it describes as a way of building Docker images at run time.
That design has a direct consequence worth naming: the function is not executed inside the dashboard process or a shared worker pool. It gets its own container. The README's quick-start confirms this by telling you to run docker ps and observe that the function was deployed in its own container. Isolation comes from the container boundary.
The repository layout matches the description. cmd/ holds the entry points, pkg/ holds the implementation, docs/ holds the concepts and setup guides, and hack/ holds build tooling. The Makefile shows how images are produced, with NUCLIO_DOCKER_REPO defaulting to quay.io/nuclio and NUCLIO_CACHE_REPO to ghcr.io/nuclio, and architecture selected from go env GOARCH with arm mapped to armhf and arm64 kept as arm64. The go.mod declares go 1.26.10, so building from source requires a toolchain at least that new.
Install Nuclio with Docker and deploy a first function
The README calls the dashboard the simplest way to explore Nuclio, and the only prerequisite it names is Docker. The command below starts the dashboard container, publishes port 8070 and mounts the Docker socket so the dashboard can create function containers on the host daemon.
docker run -p 8070:8070 -v /var/run/docker.sock:/var/run/docker.sock --name nuclio-dashboard quay.io/nuclio/dashboard:stable-amd64After that, browse to http://localhost:8070. The README instructs you to create a project and then add a function. For a first real use it suggests deploying the pre-existing template named "dates (nodejs)". Once deployed, run docker ps; the function should appear in its own container alongside the dashboard.
Invoking the function is a plain HTTP call. The README gives this example, and notes that the port number must be checked against docker ps or the dashboard because it is assigned dynamically:
curl -X POST -H "Content-Type: application/text" -d '{"value":2,"unit":"hours"}' http://localhost:37975The 37975 in that command is the port the example function happened to get, not a fixed value. Copy the port from your own docker ps output. If you are deploying to Kubernetes rather than a local daemon, the README points to separate getting-started guides for Kubernetes, Google Kubernetes Engine and Azure Container Services, and mentions nuctl, the command-line interface, as an alternative to the dashboard UI.
Where Nuclio is the wrong tool
The container-per-function model is the main constraint. Every function is an image, and images must be built. If your environment cannot build images (locked-down CI, no registry, no Kaniko support on the cluster), the deploy path described in the README does not apply to you. The Kaniko integration is presented as the production-ready way to build at run time, which implies that without a working build path you are limited to pre-built images.
Second, the project is self-hosted by design. Running it as a standalone container means the dashboard talks to a local Docker daemon, which is fine for a laptop and wrong for anything with availability requirements. Running it on Kubernetes means you now operate a Kubernetes cluster and a function platform on top of it. Teams that chose serverless specifically to avoid cluster operations will find that Nuclio moves the operational burden rather than removing it.
Third, the performance claim in the README is a claim, not a measurement you can plan capacity against. It states that a single function instance can process hundreds of thousands of HTTP requests or data records per second and that this is 10-100 times faster than some other frameworks, without naming the comparison baseline in the sentence itself. Treat those numbers as a starting hypothesis. Your own throughput will depend on the runtime, the trigger and the payload.
Nuclio compared with OpenFaaS and Knative
OpenFaaS is a useful contrast. Both deploy functions as containers on Kubernetes. The difference in emphasis is the event surface. Nuclio's README leads with data and streaming sources and ships clients for Kafka, MQTT, NATS, AMQP, S3, Pub/Sub, Elasticsearch and OpenSearch directly in go.mod. If your workload is a stream of records arriving from a message broker, that native trigger set is the reason to pick Nuclio over a framework where you would run a separate connector and call the function over HTTP.
Knative takes a different route again. It is a Kubernetes-native building block. Nuclio's own framing is that it is not tied to Kubernetes at all: the README presents the standalone Docker container as a first-class deployment, which matters for edge devices, laptops and on-prem machines where a cluster is not available. A framework that assumes Kubernetes cannot offer that.
None of this makes one project strictly better. The honest summary is that Nuclio optimizes for event and data plumbing and for portability across Docker and Kubernetes, and accepts the cost of owning image builds and, in cluster mode, of operating the platform.
Licence, releases and the cost of staying current
Nuclio is licensed under Apache-2.0, and the repository carries a LICENSE file at the top level plus a .licenserc.json for header enforcement, which the Makefile's source headers echo. Apache-2.0 permits commercial use and modification and includes a patent grant. It also requires that you preserve notices and state significant changes. That is a summary of the licence text, not legal advice; if you redistribute Nuclio inside a product, have your own counsel read the terms.
The release cadence visible in the repository is fast: 1.16.12 on 2026-10-16, 1.17.11 on 2026-10-26 and 1.16.13 on 2026-10-29, and the last push to the development branch was on 2026-11-02. Releases are being published on both the 1.16 and 1.17 lines. That gap is worth understanding before you pin a version: decide whether you track the 1.17 or the 1.16 line, and check which one your deployment guide was written against.
The upgrade cost is the part teams underestimate. Because functions are images, a platform upgrade can invalidate the build path for functions you have not rebuilt. The Makefile exposes NUCLIO_LABEL for tagging and NUCLIO_CACHE_LABEL for the cache, both defaulting to latest and unstable respectively, which means a default build is not reproducibly versioned unless you set those variables. Pin them in CI if you care about rebuilding the same artifact later.
Editorial conclusion
Adopt Nuclio if you run event-driven functions on your own Docker host or Kubernetes cluster and need triggers for Kafka, MQTT, HTTP or timers, with the option of GPU execution. Do not adopt it if you want a fully managed cloud function service with no cluster to operate, or if your team has no container build pipeline and no appetite for maintaining one. Before committing, verify three things: that the runtime you intend to use exists in the current release, that your chosen trigger is documented for your deployment mode, and that your Kubernetes version is covered by the getting-started guide for your platform. The dashboard image tag in the README is stable-amd64, so confirm an image exists for your architecture before you plan a rollout.
Frequently asked questions
How do I install Nuclio?
The README says the simplest way to explore Nuclio is to run the dashboard container with Docker, publishing port 8070 and mounting the Docker socket. For Kubernetes, it points to separate getting-started guides for Kubernetes, GKE and AKS.
What is Nuclio?
Nuclio is a high-performance serverless framework focused on data, I/O and compute intensive workloads. It takes an event from a trigger such as Kafka, MQTT, HTTP or a timer and runs user-supplied code in response, deployed either on Docker or on Kubernetes.
How does Nuclio compare with OpenFaaS?
Both run functions as containers. Nuclio's README emphasizes native data and streaming sources, and its go.mod includes Kafka, MQTT, NATS, AMQP, S3, Pub/Sub and Elasticsearch clients, while also supporting a standalone Docker deployment rather than assuming Kubernetes.
What are the alternatives to Nuclio?
OpenFaaS and Knative are common comparisons. OpenFaaS is closer in the container-per-function model, while Knative is a Kubernetes-native building block, and Nuclio's distinguishing feature is its native trigger set plus deployment on plain Docker.
How does Nuclio compare with Knative?
The README does not contain a direct feature comparison. The relevant difference it does describe is deployment scope: Nuclio runs both as a standalone Docker container and on Kubernetes, whereas Knative is a Kubernetes-native building block.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nuclio-nuclio)Star history chart for your README
[](https://hysenlabs.com/projects/nuclio-nuclio)Was this useful?