CUTLASS 4.8: CuTe DSL, Rubin SM107 Targets, and What the Beta Label Still Means
CUDA Templates and Python DSLs for High-Performance Linear Algebra
At a glance
- What is it?
- NVIDIA's CUDA template library for GEMM now ships a Python DSL alongside its C++ abstractions. This covers what the 4.8 release actually adds, how the two surfaces differ, and which architectures it targets.
- Who is it for?
- Adopt CUTLASS if you are writing CUDA kernels that target Tensor Cores on Ampere, Hopper, or Blackwell and you need tiling and data-movement abstractions you can specialize rather than a fixed library call. Do not adopt it if you want a drop-in BLAS replacement or you cannot absorb the compile-time cost of C++ template instantiation; cuBLAS remains the lower-effort path for standard shapes.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
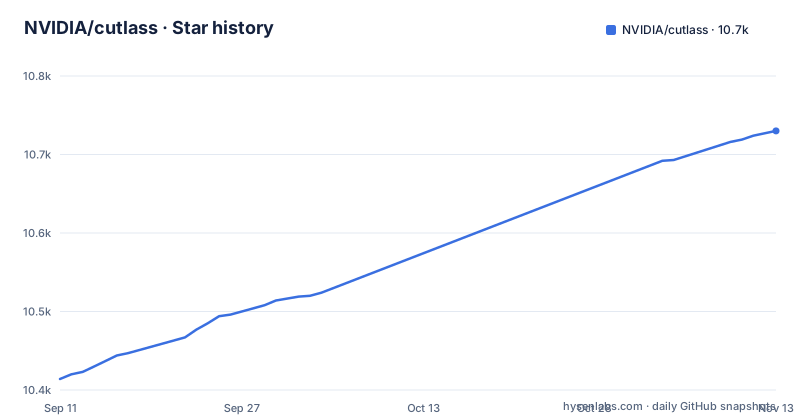
- NVIDIA/cutlass10,730 ★ · +316
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| NVIDIA/cutlass | 10.4k | 10.7k |
316 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap between cuBLAS and a hand-written kernel
CUTLASS occupies a specific slot. cuBLAS gives you a call and a result. Writing your own kernel gives you control and a long debugging session. CUTLASS sits between them: a collection of abstractions for implementing matrix-matrix multiplication and related computations at all levels and scales within CUDA, as the README puts it, with hierarchical decomposition and data movement broken into reusable, modular components. The intended user is someone who needs a GEMM that cuBLAS does not offer, whether because of an unusual epilogue, a mixed-precision combination, a fused operation, or a shape pattern that a general library handles poorly. The README frames the audience for the newer Python surface as students, researchers, and performance engineers. That is a wide net, and the two surfaces serve different parts of it. The C++ templates have existed since 2017 and carry the weight of production use. The Python DSLs arrived with CUTLASS 4 and are the part of the project still finding its footing.
How the C++ layer decomposes a GEMM
The repository's own diagram is titled Complete CUDA GEMM decomposition, and that is the design in one phrase. Rather than presenting a monolithic kernel, CUTLASS exposes primitives at each level of a conceptual parallelization hierarchy. Those primitives can be specialized and tuned through custom tiling sizes, data types, and other algorithmic policy. The practical consequence is that a GEMM becomes a composition decision: you pick how work is distributed across threadblocks, how tiles are staged through shared memory, how fragments are fed to the multiply-accumulate units, and how results are written back. Data movement is treated as a first-class concern, with async copy abstractions and, on newer architectures, TMA-based paths. This decomposition is why the same library can cover FP64 through 1-bit binary types: the arithmetic atom changes while the surrounding movement and scheduling structure stays recognizable. The cost of that generality is template instantiation. Every policy combination is a distinct compiled type, and the compile times reflect it.
CuTe DSL: same concepts, Python syntax, separate compiler
CUTLASS 4 adds Python-native interfaces for writing CUDA kernels based on core CUTLASS and CuTe concepts. The README claims no performance compromises, orders of magnitude faster compile times, and integration with deep learning frameworks without glue code. The design goal is consistency: CuTe DSL exposes layouts, tensors, hardware atoms, and control over the hardware thread and data hierarchy, mirroring the C++ CuTe abstractions rather than inventing a parallel vocabulary. That matters for anyone who has to move a prototype into a C++ codebase later, or who reads C++ examples to understand the Python ones. The beta status is stated plainly in the README, with a target of graduating by end of summer 2026. Treat that as a schedule commitment from the project, not a guarantee. The 4.8 release notes also introduce an opt-in preview of a separate compiler pipeline for CuTe DSL extensions, enabled by setting CUTE_DSL_USE_EXTENSION_COMPILER=1 before running a program. The notes say the pipeline is expected to preserve program behavior while generated PTX and SASS may differ, and that it is planned to become the default in a future release. That is a meaningful caveat for anyone who inspects generated assembly or pins to specific instruction sequences.
Getting a first kernel to build
The README points to two entry points rather than embedding instructions: the CUTLASS C++ Quick Start Guide and the CuTe DSL Quick Start Guide, both under docs.nvidia.com/cutlass. Those are the setup paths the README points to. The 4.8 notes identify Rubin kernels as SM107. For the CuTe DSL extension pipeline, the documented switch is the environment variable CUTE_DSL_USE_EXTENSION_COMPILER, set to 1, invoked as a prefix to a normal Python run. The notes describe it as required for kernels that mix the two API surfaces, meaning a kernel that calls cute_ext operations from inside @cute.jit or @cute.kernel code.
Data types, architectures, and the breadth claim
The supported type list is long and worth reading as a scope statement rather than a feature list. FP64, FP32, TF32, FP16, BF16, FP32 emulation via tensor core instructions, the 8-bit floating point formats e5m2 and e4m3, block scaled types including NVIDIA NVFP4 and the OCP standard MXFP4, MXFP6, and MXFP8, narrow integers at 4 and 8 bits signed and unsigned, and 1-bit binary types where the architecture supports them natively. The architecture list is Volta, Turing, Ampere, Ada, Hopper, and Blackwell, with Rubin appearing throughout the 4.8 notes. The phrase where architectures allow for the native support of such data types is doing real work in that sentence: the library exposes these types, but the hardware determines whether you get a fast path or an emulated one. Anyone planning around MXFP4 or 1-bit types should confirm the specific instruction support on their target part before designing around it.
Where CUTLASS is the wrong choice
Three cases stand out. First, if your workload is a standard dense GEMM at a common shape and precision, cuBLAS already covers it, is maintained by the same vendor, and requires no template instantiation. CUTLASS earns its cost when you need a shape, epilogue, or fusion that a general library does not provide. Second, if your build pipeline cannot tolerate long C++ compile times, the template-heavy design works against you. The README positions the Python DSL as addressing exactly this, but the DSL is in beta, so the compile-time relief arrives with beta caveats attached. Third, if you are not on NVIDIA hardware, none of this applies. The project is CUDA-specific by construction. There is also a narrower risk: the 4.8 notes describe the cute_ext compiler pipeline as changing generated PTX and SASS even when behavior is preserved. Teams that depend on specific generated code, whether for profiling, certification, or downstream tooling, should not enable that pipeline without inspecting the output.
What you would use instead, and how the approach differs
The obvious alternative is cuBLAS, and the difference is architectural rather than a matter of speed. cuBLAS is a closed library of pre-built kernels selected by heuristics at call time. You choose a function and a handle; the vendor chooses the tiling, the staging, and the instruction mix. CUTLASS hands those choices to you as composable pieces, which is why it can support epilogues and fusions that have no cuBLAS entry point. The trade is explicit: you take on tuning and compile time in exchange for control. A second alternative, for teams already inside a framework, is to rely on the framework's own kernel generation or its cuBLAS bindings and never touch CUTLASS directly. That is a reasonable default. CUTLASS is the layer you reach for when the default stops fitting, not the layer you start from. The README's own framing supports this, describing the components as building blocks within custom kernels and applications rather than as an end-user API.
Release cadence, licensing, and what to check before upgrading
The release history shows a fast cadence. Between late August and late October 2026 the repository published v4.8.0dev (2026-08-27), v4.8.0 (2026-09-22) and v4.8.1 (2026-10-21), and the README is now headed CUTLASS 4.8.1. That pace means the maintenance cost is not zero: staying current requires reading release notes for behavior changes, and the 4.8 notes already flag one, the opt-in compiler pipeline that alters generated PTX and SASS. On licensing, the repository metadata reports NOASSERTION, which means the automated classifier could not identify a standard licence from the files it inspected. That is not a statement about the actual terms. Anyone planning commercial use should read the LICENSE file in the repository and, where the terms matter to the business, get counsel rather than relying on the metadata field. For upgrades specifically, read the release notes for each version you skip.
Editorial conclusion
Adopt CUTLASS if you are writing CUDA kernels that target Tensor Cores on Ampere, Hopper, or Blackwell and you need tiling and data-movement abstractions you can specialize rather than a fixed library call. Do not adopt it if you want a drop-in BLAS replacement or you cannot absorb the compile-time cost of C++ template instantiation; cuBLAS remains the lower-effort path for standard shapes. Before committing, verify three things: that your toolkit and driver support the architecture you target, including SM107 for Rubin, that your target architecture is listed among Volta, Turing, Ampere, Ada, Hopper, and Blackwell, and that you are willing to track a project whose CuTe DSL is still in public beta with a stated graduation target of end of summer 2026.
Frequently asked questions
Is CUTLASS still C++ only?
No. CUTLASS 4 adds DSLs, Python native interfaces for writing CUDA kernels from core CUTLASS and CuTe concepts. The first, released with 4.0, is CuTe DSL, a low-level model consistent with the CuTe C++ abstractions, exposing layouts, tensors and hardware atoms.
Which NVIDIA architectures does CUTLASS target?
The C++ abstractions cover Volta, Turing, Ampere, Ada, Hopper and Blackwell. CUTLASS 4.8.0 adds initial Rubin support scoped to dense GEMM, with higher-throughput FP8 and FP4 Tensor Core MMA instructions and 2:4 sparsity for FP4.
What data types can CUTLASS kernels use?
FP64, FP32, TF32, FP16, BF16, FP32 emulation through a Tensor Core instruction, the 8-bit floats e5m2 and e4m3, block-scaled NVFP4 plus OCP MXFP4, MXFP6 and MXFP8, narrow 4 and 8-bit signed and unsigned integers, and binary 1-bit types on architectures that support them natively.
How do I install CUTLASS?
The project links two quick start guides on docs.nvidia.com, one for the C++ side and one for CuTe DSL. The Python package declares requires-python 3.8 or newer and depends on cuda-python 11.8.0 or newer, networkx, numpy, pydot, scipy and treelib.
What does CUTE_DSL_USE_EXTENSION_COMPILER do in CUTLASS?
Setting it to 1 opts your script into the CuTe DSL extensions compiler pipeline so cute_ext APIs can be used inside @cute.jit and @cute.kernel code. Behavior and performance are expected to be preserved, generated PTX and SASS may differ, and the pipeline becomes the default no earlier than 4.10.
What did CUTLASS 4.8.0 add?
Initial Rubin support for dense GEMM, FP8 MMA_K=64 and FP4 MMA_K=128 Tensor Core MMA instructions, B collector reuse, tensor memory extended from 512 COL to 576 COL, 328KB shared memory allocations, softmax acceleration features, 2:4 sparsity for FP4, and IKET profiler support for sm107.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Jensen is out. CUDA isn't. A Developer's Guide to Everything Nvidia Builtdev.to · Nov 13, 2026 · 7 points · 2 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvidia-cutlass)Star history chart for your README
[](https://hysenlabs.com/projects/nvidia-cutlass)Was this useful?