RunAnywhere SDKs: One C++ Core, Eight Language Bindings and a Capability Registry That Picks the Engine for You
Production ready toolkit to run AI locally
At a glance
- What is it?
- RunAnywhere runs LLMs, vision, speech, RAG and image generation on the device itself, behind one API across eight SDKs. Its README is unusually explicit about what is not implemented, which is the most useful part for anyone planning to ship with it.
- Who is it for?
- RunAnywhere fits teams that want one local-inference API across iOS, Android, web, desktop and Python and accept engines chosen by priority rather than by you. It is not a full autonomous agent framework and does not implement wake-word detection.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
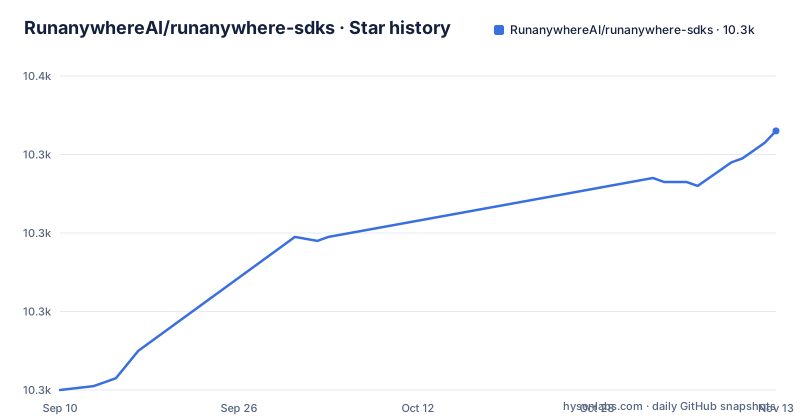
- RunanywhereAI/runanywhere-sdks10,346 ★ · +66
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| RunanywhereAI/runanywhere-sdks | 10.3k | 10.3k |
66 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A capability registry, not your code, decides which engine runs on a device
The README says your code rarely picks hardware. Engines register what they can run, and the highest-priority engine that fits the device wins. QHexRT is used on the Snapdragon Hexagon NPU, MLX on Apple silicon, and llama.cpp everywhere, with Metal on Apple, CUDA on NVIDIA as an opt-in build, and WebGPU in the browser. Sherpa with ONNX handles speech and embeddings, and Core ML handles diffusion.
The design is eight SDKs on top of one C++ core, with a registry routing every call. The consequence is portability of code, and less control over performance. If you want a specific runtime, you depend on the registry's ordering and on which engines you registered. The README also lists LiteRT and ExecuTorch as reserved framework values only: they exist in the enum but are not integrated runtimes yet, so choosing them does not give you a working backend.
Call capabilities() because an enum value does not prove an engine is installed
The README tells you to call RunAnywhere.capabilities(), described for v4, to discover what the current package and device can actually execute. Its warning is that enum presence alone does not mean an engine is installed.
This changes how an application should start. A cross-platform app can reference a model category that exists in the API and still find, at runtime, that the engine for it was not included in the build or does not suit this phone. The right pattern is to ask the capability list first and build the interface from the answer, hiding or disabling features that report as unavailable. Without that check, the failure is discovered by a user at the moment they press a button. It also means testing on real devices of each class, since the same package can report different capabilities on different hardware.
The feature list names its own gaps: no wake word, no full agent framework, gated image generation
The capability list covers LLM chat with token streaming, multi-turn history and LoRA adapters; structured output as schema-validated JSON; tool calling with stable call IDs and an agent loop; vision; speech to text; text to speech; voice agents; embeddings; RAG; and image generation. Each entry carries qualifiers.
Structured output uses constrained decoding only where the engine supports it. Parallel tool calls happen only when the engine or capability reports support. The computer-use action parser turns Fara1.5-style action strings into viewport-scaled coordinates and is explicitly not a full autonomous agent framework. The voice agent combines voice activity detection, speech to text, an LLM and text to speech, with playback scoped by SpeechHandle, and wake-word detection is not implemented. Image generation is Stable Diffusion on Core ML, plus inpainting on the Hexagon NPU, gated by platform and backend. If you need always-listening activation or Android image generation, plan separately.
The Python quick start downloads the model on first use and needs the network once
The fastest path is Python:
pip install runanywhereimport runanywhere as ra
from runanywhere import LlmOptions
ra.initialize()
# downloads on first use
print(ra.llm.generate("Explain on-device AI in one sentence.",
LlmOptions(model="qwen2.5-0.5b")).text)The comment in the code says the model downloads on first use, so the first run needs a network connection and storage for the weights, and only later runs are offline. The README's stance is private by default and offline by design, which applies after the model is on the device.
There is also a terminal route through a separate repository, RunanywhereAI/wally, which consumes the C++ desktop kit this repository publishes:
curl -fsSL https://raw.githubusercontent.com/RunanywhereAI/wally/main/install.sh | sh
wally run qwen3 "Explain on-device AI in one sentence."
Piping a remote script into a shell is convenient and requires trusting that script, so read it first.
Mobile SDKs make you register a backend explicitly before initializing
In Swift, you import RunAnywhere and a runtime module, call LlamaCPP.register(), then RunAnywhere.initialize(), build a model load request with a model id such as smollm2-360m, a language category and the llama.cpp framework, and then generate. Adding the MLX backend with MLX.register() gives Apple-native LLM, VLM, speech and embeddings on Apple silicon. Swift Package Manager installs from the repository URL.
Kotlin follows the same shape. You register LlamaCPP and call RunAnywhere.initialize with an Android context and an environment value. The Gradle dependencies pull the SDK and the llama.cpp module at version 0.20.27, with an optional ONNX module for speech and voice activity detection:
dependencies {
    implementation("io.github.sanchitmonga22:runanywhere-sdk:0.20.27")
    implementation("io.github.sanchitmonga22:runanywhere-llamacpp:0.20.27")
    // Optional: STT / TTS / VAD
    // implementation("io.github.sanchitmonga22:runanywhere-onnx:0.20.27")
}
Flutter has matching runanywhere and runanywhere_llamacpp packages. The consequence is that each engine is a separate module, so a build that omits one cannot run its capability.
Release tags track the C++ desktop kit, while SDK package versions are numbered separately
The recent GitHub releases are cpp-desktop-v0.20.43 on 2026-10-28, v0.20.42 on 2026-10-21 and v0.20.41 on 2026-10-19. They are tagged as the cpp-desktop kit, which is what the wally CLI consumes. The Kotlin artifacts in the README are 0.20.27, a different number for a different artifact.
So the release page is not a record of every SDK version. Check the package registry for your platform when you need the latest Swift, Kotlin, Flutter, React Native or web release. The last push was on 2026-11-02, which shows continuous activity. GitHub reports the licence as NOASSERTION even though the repository contains a LICENSE file, so confirm its terms yourself before shipping a product, especially because the project also offers a hosted Console for managing a fleet of devices, which is a separate commercial surface.
Three workspace roots share one generated TypeScript protocol package
The repository layout reflects the multi-language scope: bindings, core, engines, runtimes, idl, cmake and dependencies at the top, plus CMakeLists.txt, CMakePresets.json and Package.swift. The root package.json carries a long note explaining that three workspace roots reference bindings/proto-ts by different relative paths. The repo-root yarn workspace covers proto-ts, the React Native packages and the example app. The React Native directory is its own yarn workspace root, and the web SDK is an npm workspace root.
The stated reason is that each SDK lane can run standalone in CI without dragging in the others, and the note says consolidation waits on a lockfile policy decision. For a contributor this means working in a single binding often requires running install from that binding's own root, not from the top. The idl directory holds the shared interface definitions that the generated protocol types come from, so API changes start there.
Editorial conclusion
RunAnywhere fits teams that want one local-inference API across iOS, Android, web, desktop and Python and accept engines chosen by priority rather than by you. It is not a full autonomous agent framework and does not implement wake-word detection. Query capabilities() on each target device, and note that GitHub shows no detected licence, so read LICENSE before shipping.
Frequently asked questions
What is RunAnywhere?
RunAnywhere is a toolkit for running AI locally on phones, browsers, desktops and servers. It has eight SDKs over one C++ core and covers LLMs, vision, speech, voice agents, RAG, embeddings and image generation.
How do I check which features work on a device?
Call RunAnywhere.capabilities(), described for v4, to see what the current package and device can execute. The README warns that enum presence alone does not mean an engine is installed.
Does RunAnywhere support wake-word detection?
No. The voice agent pipeline combines voice activity detection, speech to text, an LLM and text to speech, and the README states that wake-word detection is not implemented.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/runanywhereai-runanywhere-sdks)Star history chart for your README
[](https://hysenlabs.com/projects/runanywhereai-runanywhere-sdks)Was this useful?