NVIDIA GenerativeAIExamples: Reference RAG and Agent Workflows Tied to NVIDIA's Stack
Generative AI reference workflows optimized for accelerated infrastructure and microservice architecture.
At a glance
- What is it?
- NVIDIA's GenerativeAIExamples repository packages RAG pipelines, agentic workflows, and vision NIM examples as Jupyter notebooks and Docker Compose apps. It is a practical starting point for teams already committed to NVIDIA NIM, NeMo, and RAPIDS, but its value depends on that ecosystem.
- Who is it for?
- Adopt GenerativeAIExamples if your team is building on NVIDIA hardware and plans to use NIM microservices, NeMo, or RAPIDS for RAG, fine-tuning, or agentic pipelines. The examples are a fast on-ramp because they show working integrations and Docker Compose commands.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
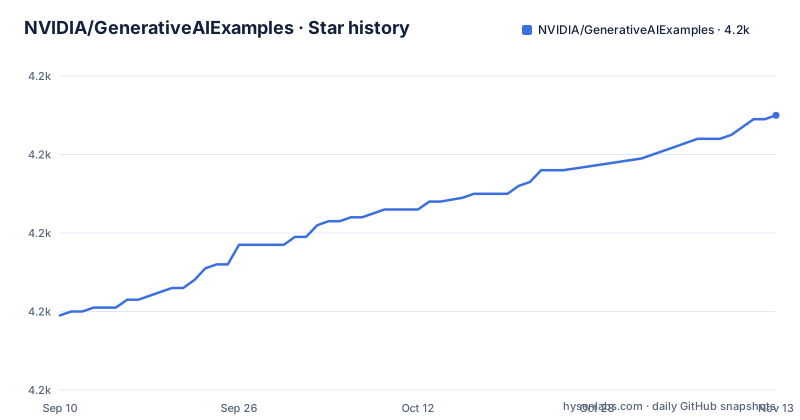
- NVIDIA/GenerativeAIExamples4,230 ★ · +51
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| NVIDIA/GenerativeAIExamples | 4.2k | 4.2k |
51 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Repository Actually Provides
GenerativeAIExamples is a collection of reference workflows, not a single product. It targets developers who want to build RAG pipelines, agentic workflows, or fine-tuning loops on NVIDIA's accelerated infrastructure. The primary language is Jupyter Notebook, which tells you the intent: these are tutorials and starting points, not drop-in libraries. The repository spans several domains: basic RAG with LangChain, knowledge graph RAG using RAPIDS, agentic workflows with Llama 3.1, NeMo-based data flywheel loops, and vision NIM workflows for tasks like video monitoring and multimodal search. The audience is engineers who already work with NVIDIA's software stack and need a working example to adapt.
How the Examples Are Organized
The repository is split into directories that mirror the workflow type. The README lists RAG notebooks under RAG/notebooks, with subfolders for langchain and other frameworks. The RAG/examples directory contains Docker Compose-based applications, such as basic_rag/langchain. The README also links to an event-driven RAG example with Morpheus and NIM microservices, pinned to the v0.7.0 tag. The vision workflows live in a submodule, so cloning recursively is required to get them. This structure means you often need to read the README inside each example to understand its dependencies. The repository uses a mix of notebooks for interactive exploration and Docker Compose for runnable services, which reflects its dual role as both documentation and a quick-start kit.
Running the Basic RAG Example
The README gives a concrete path to run a basic RAG pipeline. First, you export an NVIDIA API key from the build.ngc.nvidia.com catalog. Then you clone the repository and change into RAG/examples/basic_rag/langchain. The command docker compose up -d --build starts the pipeline, and you access a RAG Playground at https://localhost:8090/. To stop, run docker compose down. This is a real, working flow, but it assumes you have Docker and an NVIDIA API key. So the quick start is genuinely quick, but it is also a black box until you dig into the compose files.
The Data Flywheel and NeMo Microservices
A significant portion of the repository focuses on the Data Flywheel concept, which the README defines as a self-reinforcing cycle where user interactions generate data that improves models. The tutorials under nemo/data-flywheel demonstrate tool-calling fine-tuning, embedding fine-tuning, and evaluation using NeMo Microservices. For example, one tutorial fine-tunes Llama-3.2-1B-Instruct on the xLAM function-calling dataset, then evaluates and adds guardrails. This is not a simple notebook; it involves multiple microservices: NeMo Datastore, Entity Store, Customizer, Evaluator, and Guardrails. The architecture is modular and Kubernetes-oriented, which means the learning curve is steep. The value is that you see how these services fit together, but you need a Kubernetes cluster and familiarity with NeMo to reuse it.
Agentic and Safer AI Examples
The repository includes examples for agentic RAG with Llama 3.1 and NeMo Retriever NIMs. There is also a section on safer agentic AI, which shows how to audit LLMs with NeMo Auditor and run inference with parallel guardrails to reduce latency. These examples are important because they address two practical concerns: grounding LLMs with retrieval and protecting against unsafe prompts. The parallel rails tutorial is particularly useful because it shows a latency optimization, not just a safety check. However, these examples assume you have access to NIM microservices, which may require a license or an NGC account. The README links to blogs and notebooks, but the actual code is spread across directories, so you have to navigate to find what you need.
Vision NIM Workflows as a Separate Submodule
The vision NIM workflows are not in the main tree. They live in a submodule, and the README instructs you to clone with --recurse-submodules. The examples cover VLM-based video monitoring, natural language image search with NV-CLIP, text extraction combining VLMs and CV models, and few-shot classification with NVDINOv2 and Milvus. This separation is a practical choice because vision workflows have different dependencies, but it also means the main repository is not self-contained. If you clone without the submodule flag, you will miss these examples. The use of Milvus for vector storage and NVDINOv2 for embeddings shows that the vision examples are not just wrappers around a single API; they demonstrate real multimodal pipelines.
Limitations and When to Look Elsewhere
The most obvious limitation is that this repository is NVIDIA-centric. The examples are built around NIMs, NeMo and RAPIDS. If your stack is based on open-source tools like Ollama or vLLM without NVIDIA NIM, you will have to adapt significantly. The examples are also reference material, not production code. The Docker Compose setup is for local experimentation, not for deployment at scale. Another issue is version drift. The repository is actively pushed, but the release tags (v0.8.0, v0.7.0) date from mid-2024, while the last push is in 2026. That gap suggests the main branch may have unreleased changes that could break the documented commands. Finally, the reliance on NVIDIA API keys means you cannot run everything offline or with fully local models unless you set up your own NIM endpoints, which is a separate effort.
Alternatives and How They Differ
A direct alternative is LangChain's own repository of templates and integrations. LangChain offers a broader set of model providers, including local open-source models via Ollama and cloud APIs from multiple vendors. The difference is that GenerativeAIExamples is optimized for NVIDIA's hardware and microservices, while LangChain is framework-agnostic. Another alternative is Haystack by deepset, which provides RAG pipelines with a focus on production readiness and supports various vector databases and models. Haystack emphasizes modularity and testing, whereas NVIDIA's examples are more about showcasing the integration of NIMs and NeMo. If you need a vendor-neutral starting point, choose LangChain or Haystack. If you are already on NVIDIA GPUs and plan to use NIMs, GenerativeAIExamples gives you a more direct path, but you inherit the ecosystem lock-in.
Editorial conclusion
Adopt GenerativeAIExamples if your team is building on NVIDIA hardware and plans to use NIM microservices, NeMo, or RAPIDS for RAG, fine-tuning, or agentic pipelines. The examples are a fast on-ramp because they show working integrations and Docker Compose commands. Do not adopt it if you are looking for a vendor-neutral framework or you need production-ready code, because these are reference samples that assume the NVIDIA ecosystem. Before using any example, verify that your GPU drivers, CUDA version, and Docker setup match the requirements in the specific README, and check the release notes for known issues. The repository is actively updated, but each example may lag behind the latest NIM or NeMo release, so pin versions and test the exact workflow you plan to use.
Frequently asked questions
what is generative ai examples in NVIDIA's repository?
It is a starting point for developers integrating with the vendor's software ecosystem: reference workflows for retrieval pipelines, agentic systems, fine-tuning and vision, delivered as notebooks, microservice tutorials and container stacks. The repository describes itself as optimized for accelerated infrastructure and microservice architecture.
How do I run the basic RAG example?
Get an API key from the vendor's model catalogue and export it as the environment variable the readme names, clone the repository, change into the basic retrieval example directory, and run compose up detached with a build. Then open the sample playground on https at a local port, and stop the containers with compose down when you are finished.
Do I need submodules to get the vision workflows?
Yes for those workflows. The readme says to clone the repository recursively, and the workflows then appear under a directory inside the checkout. The clone command in the quick start does not pass the submodules flag, so a plain clone does not include them.
What is the Data Flywheel in these NVIDIA examples?
The readme defines it as a self-reinforcing cycle where user interactions generate data that improves models or products, better outcomes attract more users, and data quality improves further. The tutorials implement it with the vendor's microservices, covering fine-tuning, inference, evaluation and guardrails.
What is NeMo Auditor used for in these examples?
For auditing a language model to identify vulnerabilities to unsafe prompts. A separate tutorial in the same section covers running inference with multiple guardrail rails in parallel, which the readme frames as a way to reduce latency and improve throughput rather than as a safety feature.
What licence covers the NVIDIA GenerativeAIExamples repository?
Apache 2.0, recorded in the licence file at the root, alongside a separate licence file for data, which is the convention for a repository that ships example datasets. Individual external components named in the tutorials, such as the base model and the public function-calling dataset, carry their own terms.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvidia-generativeaiexamples)Star history chart for your README
[](https://hysenlabs.com/projects/nvidia-generativeaiexamples)Was this useful?