NVIDIA Merlin: a metapackage for GPU recommender pipelines
NVIDIA Merlin is an open source library providing end-to-end GPU-accelerated recommender systems, from feature engineering and preprocessing to training deep learning models and running inference in production.
At a glance
- What is it?
- Merlin is not a single library but an umbrella repository that points at six separately versioned components for feature engineering, training, sequential recommendation and Triton serving. It is worth adopting only if your data already lives on NVIDIA GPUs.
- Who is it for?
- Adopt Merlin if your recommender data is already large enough that CPU feature engineering is the bottleneck, you have NVIDIA GPUs available for both preprocessing and training, and you need a Triton-served inference graph rather than a notebook model. Do not adopt it for a small catalog that fits in memory on one machine, or if your serving stack is not Triton; the Systems component is built around Triton Inference Server specifically.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 116 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
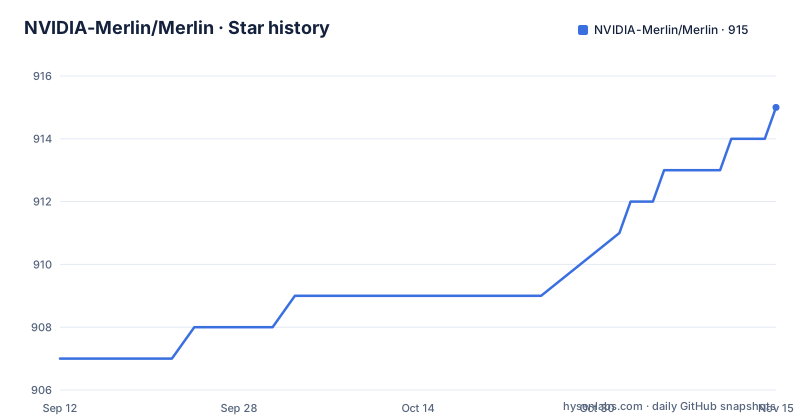
- NVIDIA-Merlin/Merlin915 ★ · +8
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| NVIDIA-Merlin/Merlin | 907 | 915 |
8 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the Merlin repository actually contains
The GitHub repository named NVIDIA-Merlin/Merlin is not the code you import. It is a coordination point. The README lists six separate open source libraries, each with its own repository, its own PyPI package and its own documentation site: NVTabular for feature engineering and preprocessing, HugeCTR for multi-GPU and multi-node training, Merlin Models for model implementations, Transformers4Rec for sequential and session-based recommendation, Merlin Systems for production serving graphs, and Merlin Core for shared dataset abstractions and operator graphs. The stated goal is an end-to-end GPU-accelerated recommender stack, from ETL through training to inference. The problem it addresses is concrete: recommender workloads are dominated by wide, sparse embedding tables and terabyte-scale interaction logs, and the standard Python toolchain handles both poorly on CPU. Merlin's answer is to keep the data on the GPU across as many stages as possible.
How the six components hand data to each other
The data flow described in the README runs in one direction. NVTabular defines transformation workflows through a high-level API and writes datasets that can exceed GPU and CPU memory. Merlin Models then maps an NVTabular dataset onto a model input layer automatically, which the README presents as a way to change the feature engineering or the model without breaking the other. HugeCTR sits underneath for the training step, with strategies for distributing embedding tables across GPUs and nodes and for loading a subset of a table into a GPU on demand during training. Transformers4Rec is the branch for sequence data: it supplies PyTorch-compatible building blocks for multiple towers, heads, tasks and losses, and integrates with NVTabular for preprocessing. Merlin Systems is the last stage, where models are combined with feature stores, nearest neighbor search and exploration strategies into graphs served by Triton Inference Server. Merlin Core is the substrate: a shared dataset abstraction, a common schema identifying key features, and a shared API for building transformation operator graphs. The schema is the load-bearing idea. It is what lets the other components automate routine modeling and serving tasks without each one reinventing column semantics.
Installing Merlin means installing components, not one wheel
What can be read from the repository is the shape of the install: each component publishes its own package, and the README shows the PyPI names nvtabular, merlin-models, Transformers4Rec, merlin-systems and merlin-core alongside the HugeCTR documentation link. The practical consequence is that there is no single pip install that gives you the whole stack, and version alignment across those packages is your responsibility. The release cadence reinforces this. The umbrella repository's most recent tags are v24.06.00 from June 2024, v23.12.00 from January 2024 and v23.09.00 from September 2023, roughly a quarterly rhythm, while the last push to the default branch is dated 2026. A tag on this repository does not guarantee that every component has a matching release, so check the individual package versions before pinning anything.
Where the GPU-only design becomes a liability
The README's claim that each pipeline stage is optimized to support hundreds of terabytes of data is also the constraint. Everything in the stack assumes NVIDIA hardware. If your team develops on laptops and deploys to a CPU-only inference cluster, you are running two different pipelines, and the automatic mapping between NVTabular output and model input layers stops being an advantage because you cannot reproduce it outside the GPU environment. The serving story has a similar shape: Merlin Systems is built on Triton Inference Server specifically, so an existing TorchServe or custom Flask endpoint is not a drop-in target. There is also a real cost to the breadth of the component list. Six libraries means six release schedules, six documentation sites and six sets of dependency constraints, and the README itself does not resolve which combinations are tested together. For a catalog with a few million interactions on a single machine, this is more infrastructure than the problem requires.
NVTabular plus PyTorch against the Merlin stack
A reasonable alternative for teams that want GPU preprocessing without the full umbrella is to take NVTabular alone and pair it with a plain PyTorch or TensorFlow training loop. The difference in approach is scope. Merlin Models exists to map NVTabular datasets onto model input layers automatically and to supply ready-made recommender architectures, so using plain PyTorch means writing that glue yourself: you handle the embedding table layout, the sparse feature plumbing and the checkpoint format. In exchange you keep a single dependency and a training loop your team already understands. HugeCTR is the other decision point. Its distinguishing feature per the README is scaling embedding tables beyond available GPU and CPU memory by distributing them across devices and loading subsets on demand. If your embedding tables fit comfortably in the memory of one GPU, that capability buys you nothing and costs you a second training framework to learn and debug.
Maintenance, licensing and what to check before you commit
The repository is licensed Apache-2.0, which permits commercial use and modification and requires that you preserve the licence and notice files; it also includes a patent grant. That is a permissive arrangement, but it governs this repository, and the README shows that the components are separate projects with their own repositories. Confirm the licence of each component you install rather than assuming the umbrella licence covers all of them. On maintenance cost, the quarterly release rhythm and the 2026 last-push date suggest the project is still receiving changes, but the gap between the newest umbrella tag and the current date means you should not read the tag list as a statement about the components. Budget for the upgrade work that comes with six aligned dependencies, and check the compatibility notes for your CUDA and driver versions in the documentation of the specific component you plan to use, since the README does not state them.
Editorial conclusion
Adopt Merlin if your recommender data is already large enough that CPU feature engineering is the bottleneck, you have NVIDIA GPUs available for both preprocessing and training, and you need a Triton-served inference graph rather than a notebook model. Do not adopt it for a small catalog that fits in memory on one machine, or if your serving stack is not Triton; the Systems component is built around Triton Inference Server specifically. Before committing, verify three things in the repository itself: that the component you need has a release newer than the v24.06.00 umbrella tag, that the README installation section resolves to a working index URL, and that your CUDA and driver versions appear in the compatibility notes of the component you intend to use.
Frequently asked questions
What is NVIDIA Merlin and what does it include?
It is a family of six open source libraries for building recommender systems on NVIDIA GPUs. The components are a tabular preprocessing library, a distributed training framework, a model library, a sequential and session-based recommendation library, a serving library built around Triton Inference Server, and a core library providing the shared dataset abstraction and schema used across the ecosystem.
How do I install NVIDIA Merlin?
The page recommends a container from the vendor's GPU cloud registry, which it says bundles all component libraries and dependencies and receives unit and integration testing. For development there is no single pip command on the page: it points at a table of per-component installation guides and says each component's environment is set up with conda or pip. The requirements file lists six Merlin packages at a floor of 23.4.0 plus the feature store library pinned at 0.31.
What version of NVIDIA Merlin is current?
The three most recent releases are v24.06.00 dated 2024-06-14, v23.12.00 dated 2024-01-15, and v23.09.00 dated 2023-09-26, while the last push on the repository is dated 2026-07-22. The setup script in the umbrella repository declares version 0.0.1 with an empty package list, so that number does not track the release tags.
How much faster is training with Merlin Models?
The page claims up to ten times faster ranking model training by using its data loaders for TensorFlow, PyTorch, and HugeCTR. It gives no dataset, hardware, baseline configuration, or methodology alongside that figure, so the claim cannot be checked from the page itself.
Which frameworks can Merlin accelerate?
The benefits list names TensorFlow, PyTorch, and FastAI for accelerating existing training pipelines through optimised data loaders. The models component names TensorFlow, PyTorch, and HugeCTR as the data loader backends behind its training speed claim. Triton Inference Server is named as the serving target for the systems component.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvidia-merlin-merlin)Star history chart for your README
[](https://hysenlabs.com/projects/nvidia-merlin-merlin)Was this useful?