Preswald promises a single file and its export command produces a folder
Preswald is a WASM packager for Python-based interactive data apps: bundle full complex data workflows, particularly visualizations, into single files, runnable completely in-browser, using Pyodide, DuckDB, Pandas, and Plotly, Matplotlib, etc. Build dashboards, reports, and notebooks that run offline, load fast, and share like a document.
At a glance
- What is it?
- Preswald packages Python data apps so they run in a browser with no server. One package serves both the native development server and the WebAssembly build by excluding its own server dependencies when the platform is the browser compiler. The claims on the page are worth reading against each other: the feature list says a single file, the export section says a directory, and the use cases section has fifteen example links with empty targets.
- Who is it for?
- Preswald fits an analyst who needs to hand a colleague or a stakeholder a self-contained dashboard they can open without installing anything, and who is comfortable that the data ships inside the artefact. It does not fit someone who needs a service with a URL, because the design has no server in the exported form, and it does not fit a team that needs a release cadence, since the newest tagged release is over a year older than the last commit.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 157 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
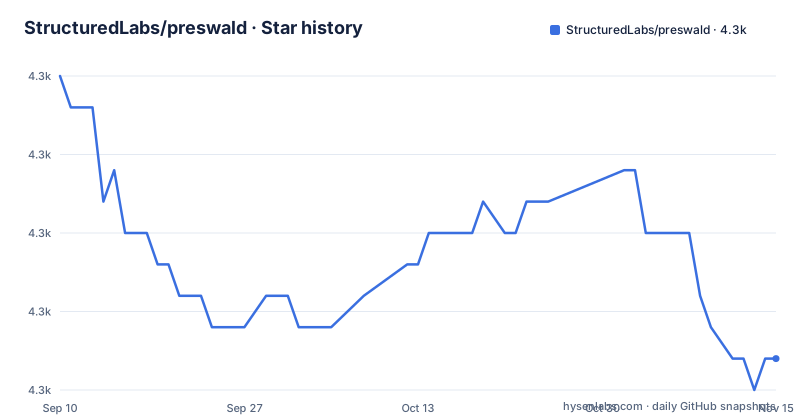
- StructuredLabs/preswald4,266 ★ · -9
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| StructuredLabs/preswald | 4.3k | 4.3k |
-9 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three different one-line descriptions for the same project
The project describes itself three times in three places and the three descriptions are not the same.
The repository description calls it a packager: something that bundles full data workflows, particularly visualisations, into single files runnable in the browser.
The page calls it a static-site generator for building interactive data apps in Python, and explains that it packages compute, data access and user interface into self-contained apps that run locally in the browser.
The packaging metadata calls it a lightweight data workflow SDK.
A generator, a packager and an SDK are three different products. In practice they are describing one thing from three vantage points: the output is a static site, the operation is packaging, and the thing a developer writes against is a library.
Which one you take from the page matters for expectations. The generator framing implies a build pipeline with a directory of output. The packager framing implies a single artefact you can email. The framework framing implies an import and a component library.
The export section settles it in practice, and not in favour of the first framing on the page.
The feature list promises a file and the export produces a folder
One feature bullet describes the file-first approach as one command creating a fully packaged application file.
The export section describes the same command differently. It builds your app into a static site inside a directory, and the folder contains all the files needed to run it locally or share it.
The bullets under that section are consistent with the folder: it works offline in any modern browser, it bundles your Python code, your data and your database queries, it preserves the interface, the logic and the reactive state, and it is shareable as a file folder or embeddable in a hosting platform.
So the single-file phrasing in the feature list and the directory in the export section are two claims about the same artefact, and only one of them matches the described output.
What the folder actually contains is worth knowing for deployment: a static site is something any file host will serve, and the data is inside it, so the size of that data is the size of your deployment.
Fifteen example links in the use cases section point nowhere
The use cases section lists five situations the tool suits, and each one ends with three links labelled as examples.
- Analyst dashboards. Build data summaries and visualizations. Share as static sites. [Example 1]() [Example 2]() [Example 3]()Those link targets are empty. Every one of the fifteen.
The five use cases themselves are specific and useful as a description of scope: analyst dashboards shared as static sites, interactive reports that update on user input, data inspection tools over files and logs, offline kits for fieldwork and air-gapped settings, and experiment panels for comparing runs.
An offline kit for air-gapped work is the most interesting of those five, because it is the one case where bundling the data inside the artefact is a requirement rather than a convenience.
What the section does not do is point at the worked examples that do exist in the repository. There are five of them, in separate directories, named for their subject matter.
So the page describes the use cases well and links to none of the code that implements them.
One package serves browser and server by excluding itself on one platform
The dependency list is where the design lives, and the mechanism is a platform marker.
Several dependencies carry a marker that excludes them when the platform system is the browser compiler. The web framework, the application server, the websocket library and a numerical library are all marked that way.
The compiler named in that marker is the one the browser runtime is built with. So the same wheel installs in two configurations: natively, with a server and a websocket layer, and inside the browser, without them.
That single marker is what makes the page's promise of no local dependencies possible. There is nothing to install because everything the browser needs is either pure Python or has a WebAssembly build.
Two details are worth noting. The database engine is not excluded, which means it has to have a build that works in both places or the browser path would not close. And the numerical library is excluded, so anything you write that calls into it will fail only in the browser.
There are also two commented-out dependency lines left in the list, one of them a plotting library with an interactive backend.
Two dependencies are pinned exactly in an otherwise ranged list
The dependency list uses ranges almost everywhere, with two exceptions that stand out.
    "pandas>=1.5",
    "toml==0.10.2",
    "plotly==5.24.1",
One configuration parser and one plotting library are pinned to an exact version with no upper and no lower flexibility, while everything around them is a floor or a bounded range.
Plotting is the one that will age worst of the two. A pinned major-and-minor of a charting library means the visualisation you built is the visualisation you get, which is what you want for a static artefact, and it also means the pin has to be revisited by hand before anything else in the stack moves.
The other pinned package is the one that reads the configuration file, which is the safer of the two to have pinned.
The rest of the list mixes three styles: a bare floor, a floor with a ceiling below the next major, and a compatible-release specifier. The last style is the strictest of the three, because it constrains the minor version too.
The interpreter floor is Python 3.10, and the linter is configured for the same target with a line length that matches the default formatting style most Python projects use.
The wheel ships a tutorial, which is what init scaffolds from
The packaging configuration lists what gets bundled into the wheel, and one of the entries is not code.
artifacts = [
    "preswald/static/*",
    "preswald/static/assets/*",
    "preswald/templates/*",
    "preswald/tutorial/*",
    "preswald/tutorial/data/*",
    "preswald/tutorial/images/*",
]
A tutorial directory, with its own data and image subdirectories, is shipped inside the distribution.
The scaffolded project the page shows contains an app script, a configuration file, a secrets file, a sample data file and a logo.
The consequences are worth stating. The wheel is larger than the code needs. Every install downloads a tutorial. And the initial project includes a secrets file, which is where API keys are meant to live, so the template's presence in every install is a small but real piece of surface area.
The console entry point is a single command, and the package itself is one importable directory rather than a set of them.
The pre-release pipeline depends on a target the file admits is missing
The build file has a target that runs the whole release sequence, and above it there is a comment.
# todo: add test-gcp
pre-release: update-version build-frontend build-wheel build-docker test-iris test-whl test-local upload-to-gcs upload-static-to-gcs
The comment is a to-do to add test-gcp. That target is declared in the file's list of phony names, but it is not among pre-release's prerequisites.
Note what the dependency list does and does not contain. There is a test target for one specific example, a test target for the built wheel, and a test target for a local run. There is no general test target for the test suite, even though the repository has both a test directory and a separate one that looks like end-to-end tests.
So the pre-release path runs three different narrow checks and the general suite is not among them.
The release path is shorter and different: it bumps the version, builds the frontend, builds the wheel, builds the container image, runs a cleanup target and uploads to the package index. The pre-release path uploads to object storage instead, twice, once for the package and once for the static assets.
The version bump is a shell script with two sed dialects
There is a target whose whole job is to increment the patch number, and it is worth reading because it is longer than the thing it changes.
It greps the packaging file for a line containing the word version, skips comment lines, takes the first match, and extracts the number with a substitution expression. If that produces nothing, it prints an error and exits with a failure.
Then it splits the number into three parts, adds one to the patch with a separate calculator program, and puts the parts back together.
The last step is the part with the branch in it.
	if [ "$$(uname)" = "Darwin" ]; then \
		sed -i '' "s/version = \"$$current_version\"/version = \"$$new_version\"/" pyproject.toml; \
	else \
		sed -i "s/version = \"$$current_version\"/version = \"$$new_version\"/" pyproject.toml; \
	fi; \
Two sed dialects, because in-place editing on one of those systems takes an argument and on the other does not.
So a patch release requires a POSIX shell, a substitution tool with two incompatible command lines, and an arithmetic program. None of that is wrong. It is just further along than a manual edit would be.
Editorial conclusion
Preswald fits an analyst who needs to hand a colleague or a stakeholder a self-contained dashboard they can open without installing anything, and who is comfortable that the data ships inside the artefact. It does not fit someone who needs a service with a URL, because the design has no server in the exported form, and it does not fit a team that needs a release cadence, since the newest tagged release is over a year older than the last commit. Before you build on it, check four things. Whether your dependencies survive the browser build, because several packages are excluded there and your code may reach for them. How large your data is, since everything is bundled into the output. Which port your development server wants, because the default is not free by convention. And what the release process does for you, because the build file carries a to-do to add test-gcp, which the pre-release pipeline does not run.
Frequently asked questions
How do I install and run a Preswald app?
Install with pip install preswald or the equivalent command for the newer installer, then initialise a project, change into it and run it. The initialisation creates an app script, a configuration file, a secrets file, a sample data file and a logo. The run command starts a development server and prints the address, which is on port 8501 by default.
What does the preswald export command produce?
It builds the app into a static site inside a dist directory, containing everything needed to run it locally or share it. The output works offline in a modern browser, bundles your Python code through the browser runtime along with your data and database queries, preserves the interface and reactive state, and can be hosted as ordinary static files.
What does Preswald need at runtime?
Python 3.10 or newer, and nothing installed locally once the app is exported. The browser build drops the web framework, the application server, the websocket library and a numerical package by excluding them when the platform is the browser compiler, while the database engine is included in both builds. The data is bundled into the exported output.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/structuredlabs-preswald)Star history chart for your README
[](https://hysenlabs.com/projects/structuredlabs-preswald)Was this useful?