OpenMetadata builds a schema-first metadata graph and now pitches it as the context layer for AI agents
The Open Context Layer for Data and AI , OpenMetadata is the open platform for building trusted data context and business semantics for humans, AI assistants, and agents.
At a glance
- What is it?
- open-metadata/OpenMetadata is an Apache-2.0 data catalog and metadata platform that joins lineage, quality, ownership, glossaries, contracts and recorded conversations into one graph, then exposes it through APIs, SDKs, semantic search and an MCP server. This piece looks at how that graph is assembled, what it cannot do for you, and what running and building it involves.
- Who is it for?
- OpenMetadata suits data teams that want one open, Apache-2.0 catalog joining lineage, quality tests, ownership, glossaries and data contracts, and that intend to feed that context to AI assistants through MCP, APIs or SDKs. It is the wrong choice for a team that only wants an AI agent to query a warehouse, because it supplies context about data rather than a path to the rows.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
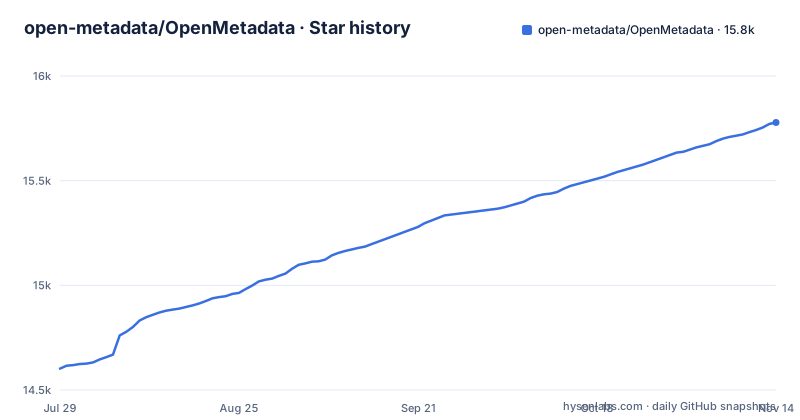
Star history
- open-metadata/OpenMetadata15,778 ★ · +1,176
| Repository | 2026-07-29 | 2026-11-14 |
|---|---|---|
| open-metadata/OpenMetadata | 14.6k | 15.8k |
1,176 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Six stages turn scattered metadata into one graph
OpenMetadata is built around an open, schema-first metadata graph, and its architecture is described as six stages. Collect pulls metadata from warehouses, lakes, BI tools, pipelines, ML platforms, messaging systems, storage systems, APIs, search systems, SaaS applications, other metadata systems, documents, conversations and agent workflows through more than 130 connectors, plus ingestion APIs, events and SDKs. Normalize maps everything onto open schemas so that an asset, a relationship, a policy, a contract, a lineage event and a memory are all represented consistently. Connect joins technical metadata, quality signals, lineage, ownership, usage, policies, conversations, semantics, domains, contracts and data products into one graph. Preserve Memory turns conversations, AI threads, decisions, assumptions, runbooks and remediation notes into governed memory nuggets tied to assets. Govern applies classifications, policies, roles, data quality, review workflows, contracts and stewardship. Activate exposes the result through Semantic Search, MCP, APIs, SDKs, events, webhooks and metadata applications.
The repository layout follows this split. openmetadata-spec holds the schemas, openmetadata-service is the server, ingestion/ is the connector side, openmetadata-ui is the web interface, and openmetadata-mcp, openmetadata-sdk and openmetadata-clients are the activation surfaces.
It describes data but is not a query path to the data
The project states its position bluntly: AI does not need another raw database connector, AI needs context and memory. A direct connection to a warehouse, lake, dashboard or pipeline exposes raw structures but does not say what the data means, whether it is certified, who owns it, which policies apply, which contract governs it, or what breaks if it changes. OpenMetadata is built to answer those questions.
The flip side matters for anyone planning an AI integration. OpenMetadata tells an agent which table holds sensitive customer information, which glossary term a metric maps to, and which dashboards sit downstream of a column. It is positioned as context, not as the engine that returns the rows. An agent that has to compute an answer still needs its own governed access to the warehouse, and you still have to wire and secure that path separately.
The second consequence is coverage. The graph only contains what was collected. A source with no connector, or a connector that was never configured, simply does not appear, and any answer about lineage or ownership will be silent about it. With 130+ connectors the list is long, but checking that your specific systems are on it is the first step of any evaluation.
Lineage reaches down to columns and accepts OpenLineage events
Lineage in OpenMetadata is tracked at several grains: upstream and downstream table lineage, column-level lineage, dashboard lineage, pipeline lineage, metric lineage, ML model lineage, and dependencies between APIs and topics. OpenLineage events are accepted as an input, which matters for teams whose orchestrators already emit them.
Column-level lineage is what makes impact questions concrete. Instead of asking which jobs read a table, you can ask which downstream dashboards, pipelines or ML models are affected by a change to one column. The same graph links lineage to ownership, so the answer can name the owners of the affected assets.
The quality side feeds into the same picture. OpenMetadata records test cases and test suites, freshness and volume checks, null, uniqueness and distribution checks, custom tests, profiling results, observability signals, incidents, alerts and quality history. A dataset marked fresh, tested and certified carries those signals with it, so a consumer or an agent does not have to treat every table as equally trustworthy.
None of those trust signals exist until someone defines the tests and certifications. A freshly connected source arrives with structure and, where connectors supply it, lineage, but whether it is tested is a statement your team has to make. Plan for that work before promising consumers a trust score.
Glossaries, contracts and standards carry the business meaning
The semantic layer covers glossaries, business terms with synonyms and related terms, metrics and KPIs, classifications and tags, domains, data products, policies, personas, lifecycle states and ontologies. Its job is to map technical names onto business meaning, so a column called cust_ltv_90d can be linked to the glossary term and metric definition the business actually uses.
Governance sits next to it: owners, stewards, teams, roles, policies, access context, certification, review workflows, lifecycle states and data contracts. Data contracts let a producer state what a dataset promises, and the graph ties that contract to the asset, its lineage and its owners.
For interoperability, OpenMetadata names a specific list of standards: DCAT, DPROD, PROV-O, OpenLineage, ODCS, RDF/OWL, JSON-LD, SHACL and JSON Schema, alongside its own APIs, events and metadata schemas. That list is useful when you already hold metadata in one of those forms or need to hand it to another catalog or knowledge graph.
The cost is human. A glossary nobody curates is an empty list of terms, and an ownership field nobody fills in answers who owns this with nothing. The platform holds the structure; deciding stewards and keeping terms current is organizational work that the software does not do for you.
Recorded conversations become memory nuggets attached to assets
The most recent direction in the project is memory. Conversations, AI threads, decisions, assumptions, runbooks, remediation notes and incident learnings can be turned into reusable memory nuggets and attached to assets, users, teams, data products and agent workflows. The architecture treats memory as part of the graph rather than a side channel, so engineers can use APIs, SDKs, MCP or AI workflows to preserve what was decided about a dataset.
The stated goal is that humans and agents inherit what the organization already learned instead of rediscovering it in every conversation. In practice that means a note explaining why a column contains nulls before a certain date, or which backfill fixed an incident, lives next to the table instead of in a chat log nobody can find.
This is also governed: memory nuggets sit under the same classifications, policies and roles as the rest of the graph. Two consequences follow. Memory only exists if someone or some workflow writes it, so the value depends on adoption by the people who make those decisions. And because agents can read it back, a wrong assumption recorded as memory travels as far as a correct one, which makes review of memory entries part of operating the catalog.
The MCP server and semantic search are how agents reach the graph
Activation is where OpenMetadata meets AI tooling. The repository contains an openmetadata-mcp module, and the platform lists MCP, Semantic Search, APIs, SDKs, events, webhooks and metadata applications as ways to use the graph. An assistant connected through MCP can ask the same questions a human would type into the catalog: what a metric means and how it is calculated, which datasets power a dashboard, who owns a data product, which contract applies, and which columns contain sensitive customer information.
The SDK route has its own examples directory, examples/python-sdk/, and openmetadata-clients holds client code for other consumers. Events and webhooks cover the push direction, letting other systems react when metadata changes instead of polling.
Because activation sits on top of governance, the context an agent receives is shaped by the same policies and roles applied to people. That is the point of calling it governed context. It also means the quality of an agent's answers about your data is bounded by the quality of the graph behind it: missing owners, stale glossary terms or untested tables come back to the agent exactly as they are stored.
Building from source spans Java, Python and a Yarn UI, with setup scripted for macOS and Linux only
The repository is a multi-language monorepo. The root has a pom.xml for the server modules, ingestion/ for the Python connector side, openmetadata-ui with a Yarn project under src/main/resources/ui, plus openmetadata-k8s-operator, openmetadata-airflow-apis, docker/ and a .devcontainer/ directory. The top-level Makefile includes ingestion/Makefile and sets PY_SOURCE to ingestion/src.
The dev_setup target is a one-call environment setup for macOS and Linux, with flags passed through ARGS. Windows is not named for that target, so contributors on Windows cannot rely on the one-call setup. The dev_check target diagnoses an environment without changing anything:
./scripts/dev_setup.sh --checkThe UI is installed and run through Yarn:
cd openmetadata-ui/src/main/resources/ui && yarn install --frozen-lockfilecd openmetadata-ui/src/main/resources/ui && yarn startEnd-to-end tests on the ingestion side pull in Playwright and a Chromium build:
python -m pip install "ingestion[e2e_test]/"
playwright install chromium --with-deps
The consequence is that a contributor needs working Java, Python and Node toolchains at once. These targets set up a development environment; they are not a production deployment recipe.
Patch releases land within days and 2.1.0 is still a release candidate
OpenMetadata ships often. 2.0.6-release was published on 2026-10-21, 2.0.7-release on 2026-10-27, and 2.1.0-rc1-release a day later on 2026-10-28. The last push to the repository was on 2026-11-02, and it is not archived.
Two tracks are visible at once: patch releases on the 2.0 line and a release candidate for 2.1.0. For a production catalog, the 2.0.x patches are the line to run, and the rc1 tag is for testing upgrades ahead of the final 2.1.0. A catalog holds state that many teams depend on, including glossaries, ownership, contracts and memory, so an upgrade should be rehearsed against a copy before it touches the live instance.
The repository also carries operational documents at the root: SECURITY.md, THREAT_MODEL.md, INCIDENT_RESPONSE.md and ARCHITECTURE.md, along with DEVELOPER.md and CONTRIBUTING.md. The presence of a threat model is relevant for a system that aggregates access context and policies for an entire data estate, and it is the file to read before exposing the MCP server or APIs beyond a trusted network.
Editorial conclusion
OpenMetadata suits data teams that want one open, Apache-2.0 catalog joining lineage, quality tests, ownership, glossaries and data contracts, and that intend to feed that context to AI assistants through MCP, APIs or SDKs. It is the wrong choice for a team that only wants an AI agent to query a warehouse, because it supplies context about data rather than a path to the rows. Before committing, confirm that your sources are among the connectors, decide who will maintain glossaries, owners and tests, and pin a 2.0.x release rather than the 2.1.0 release candidate.
Frequently asked questions
What does OpenMetadata do?
OpenMetadata collects metadata through 130+ connectors and joins lineage, quality signals, ownership, usage, glossaries, policies, data contracts and recorded conversations into one metadata knowledge graph. It exposes that graph through semantic search, APIs, SDKs and an MCP server.
Is OpenMetadata free to use?
OpenMetadata is open source under the Apache-2.0 license, and its code is published at open-metadata/OpenMetadata on GitHub.
What is lineage in OpenMetadata?
Lineage records where data came from and where it flows: table, column-level, dashboard, pipeline, metric and ML model lineage, plus API and topic dependencies. OpenMetadata also accepts OpenLineage events.
What is a glossary in OpenMetadata?
A glossary holds business terms with synonyms and related terms, and links them to technical assets so names like table columns map to business meaning. It sits alongside metrics, classifications, domains and data products in the semantic layer.
Is OpenMetadata a data catalog?
Yes. OpenMetadata is an open-source data cataloging and metadata management platform, and it presents that catalog as a context layer for AI assistants and agents.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/open-metadata-openmetadata)Star history chart for your README
[](https://hysenlabs.com/projects/open-metadata-openmetadata)Was this useful?