PikiwiDB: A Redis-Protocol Database on RocksDB That Trades Memory Limits for Disk and Asynchronous Replication
Pikiwidb is a Redis-Compatible database developed by Qihoo's infrastructure team.
At a glance
- What is it?
- PikiwiDB is a Redis-compatible key/value database from Qihoo's infrastructure team that stores full data in RocksDB and caches hot data. It targets datasets that have outgrown one machine's RAM, and it comes with replication and cluster limits worth knowing.
- Who is it for?
- PikiwiDB suits teams whose Redis data has outgrown memory and who want to keep the Redis protocol and operational habits. It does not suit workloads that need identical behavior for every Redis command or synchronous replication.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 29 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
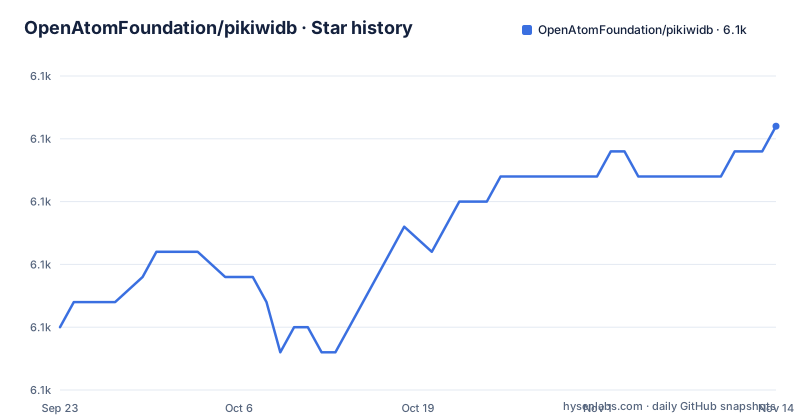
- OpenAtomFoundation/pikiwidb6,138 ★ · +8
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| OpenAtomFoundation/pikiwidb | 6.1k | 6.1k |
8 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It is positioned as a complement to Redis for datasets above 16GiB, not a replacement
The README names the problems it is aimed at. When Redis's in-memory usage exceeds 16GiB, it says, you face limited memory capacity, single-threaded blocking, long startup recovery time, high memory hardware costs, easily filled buffers, and high switching costs when one master and multiple replicas fail. PikiwiDB is described as complementing Redis, not replacing it.
The approach is to keep the Redis protocol and its operation and maintenance habits while moving the bulk of the data onto persistent storage. The system is described as high-performance, large-capacity, multi-tenant and data-persistent, with RocksDB as the storage engine. If your dataset fits comfortably in memory on one machine and your pain is something else, the pitch does not address you. It is aimed at the specific moment when memory cost becomes the constraint.
Each data structure gets its own RocksDB instance, and hot data is cached on top
In master-slave mode, the architecture is described as similar to Redis, with each data structure using a separate RocksDB instance. The feature list adds that hot data is cached while the full data is persisted in RocksDB, implementing hierarchical storage of cold and hot data. The engine uses a multi-threaded model and multiple granularity data caching.
The consequence is that performance depends on your access pattern in a way that pure Redis does not. A read that hits the cache behaves differently from one that goes to RocksDB, and the README gives no latency figures for either path. The same split explains the capacity claim: data volumes in the hundreds of gigabytes per instance, compared with Redis's in-memory storage. Before you size hardware, measure your own hot set, because the cache is what decides how often you pay for disk.
Replication is asynchronous through a binlog, so a replica can trail its master
Master-slave replication uses the slaveof command, as in Redis, and the README says the master and slave adopt binlog asynchronous replication. It also supports full and incremental data synchronization.
Asynchronous replication means a write is acknowledged by the master before replicas have necessarily applied it. If the master fails in that window, a promoted replica may be missing the latest writes. That is the same class of trade-off Redis users already know, but it is the only replication mode the README describes, so an application that needs a write to be on two machines before it returns has no option here. The README lists high switching cost on failover as one of the Redis pains it wants to reduce, yet it does not describe an automatic failover mechanism for the single-machine mode, so plan how promotion happens in your environment.
Cluster mode borrows the Codis architecture and scales by whole groups
For distribution, PikiwiDB is deployed in Codis cluster mode. The architecture adopts Codis with multiple groups, each group forms a master-slave set, and elastic scaling is based on groups. The repository carries a codis directory for this, along with a tools directory used for migration from Redis.
The practical meaning is that capacity grows by adding groups, and each group is its own master-slave pair with the asynchronous replication described above. There is an extra layer to run compared with a single node, and the Codis proxy and coordination pieces are part of your operational surface. The README promises simple scaling and shrinking, and says migration from Redis can be done smoothly with the tools, without modifying code. Those are claims to rehearse on a copy of your data before you rely on them.
The README says both fully compatible and commonly used structures, so check your commands
The text makes two compatibility statements that differ in strength. One says PikiwiDB is fully compatible with the Redis protocol and strives to completely comply with it. Another says it supports the commonly used data structures: string, hash, list, zset, set, geo, hyperloglog, pubsub, bitmap and stream, and the feature list adds ACL.
Commonly used is the safer reading. The README links a wiki page titled for the Redis interfaces PikiwiDB supports and their compatibility status, and that page, not the headline, is what you should compare against the commands your application sends. Any command you depend on that is not on the page is a candidate for a failure you only find at runtime. Redis modules and anything outside the listed structures are not mentioned at all, so treat them as unavailable until you verify them.
Building from source needs gcc 9 or newer and cmake 3.18, and the README example tag is stale
You can download a binary package from the releases page, or compile from source on Linux with CentOS or Ubuntu, or macOS. Required tools are a gcc and g++ supporting C++17 at version 9 or higher, make, cmake at version 3.18 or higher, autoconf and tar. The first steps are:
git clone https://github.com/OpenAtomFoundation/pikiwidb.gitThen pick a release instead of building the default branch, which is unstable:
git tag          # Check the latest release tag (e.g., v3.4.1)
git checkout TAG # Switch to the latest version (e.g., git checkout v3.4.1)
The example tag v3.4.1 is older than the current releases. v4.0.4 and v3.5.7 were both published on 2026-10-16, and a v4.0.4-alpha came on 2026-09-01. Two release lines are live, so decide whether you want 3.5 or 4.0 before you check out a tag. The rest of the compile instructions are not reproduced here, so follow the README for the final build steps.
Old names remain in the links, and the platform lists do not agree
The project was previously called Pika, and traces remain. The build badge points to travis-ci.org for Qihoo360/pika, the chart images and the Chinese README link point to OpenAtomFoundation/pika, and the binary download link goes to Qihoo360/pikiwidb. Several of these are services or locations you cannot assume are current. The repository also still contains a .travis.yml.
Platform support is described twice with different lists. The architecture section names CentOS, Ubuntu, macOS and Rocky Linux, while the compilation section lists CentOS, Ubuntu and macOS. If you run Rocky Linux, test the build rather than trusting either list. The user showcase names 360 with 10,000+ instances of 1.8TB each, Weibo with 10,000+ instances, Ximalaya with 6,000+ instances above 120TB, and Getui with 300+ instances above 30TB. Those are the project's own statements of adoption, with no independent source attached.
Editorial conclusion
PikiwiDB suits teams whose Redis data has outgrown memory and who want to keep the Redis protocol and operational habits. It does not suit workloads that need identical behavior for every Redis command or synchronous replication. Check the Redis interface compatibility page for your commands, and test failover before moving production data.
Frequently asked questions
Is PikiwiDB a replacement for Redis?
No. The README says it is not meant to replace Redis but to complement it, by using RocksDB persistent storage once the data volume gets too large for memory.
What deployment modes does PikiwiDB support?
A single-machine master-slave mode using slaveof with binlog asynchronous replication, and a Codis cluster mode where each group is a master-slave set and scaling happens by group.
What do I need to build PikiwiDB from source?
A gcc and g++ with C++17 support at version 9 or higher, make, cmake 3.18 or higher, autoconf and tar, on CentOS, Ubuntu or macOS. Check out a release tag rather than the unstable branch.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openatomfoundation-pikiwidb)Star history chart for your README
[](https://hysenlabs.com/projects/openatomfoundation-pikiwidb)Was this useful?