MiniCPM5-2B: public weights, a legacy requirements.txt, and no MiniCPM5 notebook
MiniCPM5: SOTA on-device LLMs, small yet powerful.
At a glance
- What is it?
- OpenBMB ships MiniCPM5-2B as BF16, GGUF, MLX and GPTQ weights together with the training data behind it, but the repository's install file still describes the 2024 stack and its example notebooks stop at the fourth generation.
- Who is it for?
- MiniCPM5-2B fits if you are targeting a phone, an edge box or a Mac, and you want the training corpus to inspect alongside the weights. It is the wrong entry point for multimodal work or for teams that want one documented environment instead of a cookbook per engine.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
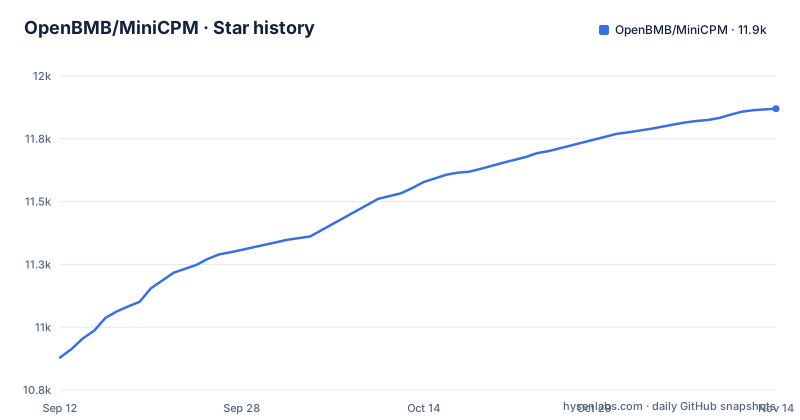
- OpenBMB/MiniCPM11,870 ★ · +991
| Repository | 2026-09-12 | 2026-11-14 |
|---|---|---|
| OpenBMB/MiniCPM | 10.9k | 11.9k |
991 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The 2B card scales the same recipe and ships the corpus with it
MiniCPM5-2B is a dense 2B Transformer that scales up the training recipe used for MiniCPM5-1B, and the project positions it for on-device, local and resource-constrained deployment. The performance claim is scoped carefully: state of the art among open-source models of similar size within the comparison set the team used, competitive overall with 4B-class models, with the stated advantages sitting in coding, mathematics, long-context understanding, tool use and agentic tasks. What arrives alongside the weights is the training corpus, published as four datasets in the UltraData family: UltraX, a high-quality web pre-training set; UltraData-Code, which manages code data in L0 to L3 tiers; UltraData-SFT-Agent-2609 with 500K agent training samples; and UltraData-RL-2609 with 80K or more reinforcement learning samples spanning mathematics, code, general knowledge and long-context reasoning. That is a rare thing for a small model release and it cuts both ways. You can read what the model was trained on.
requirements.txt describes the 1B and 2B series, not the model you are downloading
The top-level requirements.txt opens with a comment that sends you elsewhere. It states that for the current release, MiniCPM5-1B, the install commands live with each backend or framework cookbook under docs/deployment/ and docs/finetune/, because the supported version range differs per engine across vLLM, SGLang, transformers, llama.cpp, MLX, Ollama and LM Studio. The file then pins the legacy stack for the older MiniCPM 1B and 2B series, and those floors are what pip resolves if you install it and stop reading:
# For MiniCPM5-1B (the current release), the install commands live with each
# backend / framework cookbook under docs/deployment/ and docs/finetune/, since
# the supported version range differs per engine (vLLM / SGLang / transformers /
# llama.cpp / MLX / Ollama / LM Studio). This file pins the legacy stack that
# still works for the older MiniCPM 1B / 2B series.

# for MiniCPM-2B hf inference
torch>=2.0.0
transformers>=4.36.2
gradio>=4.26.0

# for vllm inference
# vllm>=0.4.0.post1

# for openai api inference
openai>=1.17.1
tiktoken>=0.6.0
loguru>=0.7.2
sentence_transformers>=2.6.1
sse_starlette>=2.1.0

# for MiniCPM-V hf inference
Pillow>=10.3.0
timm>=0.9.16
sentencepiece>=0.2.0
Read it as a historical artifact rather than a setup path. The torch and transformers entries are lower bounds with no ceiling, so a fresh resolve pulls current releases, and the vllm line is commented out, so nothing here installs a server. The file itself says the install commands for the current release live in the cookbooks under docs/deployment/ and docs/finetune/.
Seven artifacts per size, and nothing tells you which one the demo loads
The download table for MiniCPM5-2B lists seven distinct artifacts: the main card, plus -SFT, -Midtrain and -Base, plus -GGUF, -MLX and -GPTQ. Every one of them is mirrored on both Hugging Face and ModelScope. The names sort the family each belongs into, a base pretraining card, an intermediate midtrain card, a supervised fine-tuning card, while the format suffixes point at the runtime list named in the requirements.txt comment, where llama.cpp, MLX, Ollama and LM Studio appear as supported consumers. No row in the download table spells out the behavioural difference between those cards. Read the engine cookbook before assuming a format suffix matches the loader you already have installed.
The notebook tree ends at minicpm4 in a repository whose language is Jupyter Notebook
Three example directories ship with the project: demo/minicpm/, demo/minicpm3/ and demo/minicpm4/. Those are the example files the repository advertises, and they line up with the three earlier generations. No directory named for MiniCPM5 appears among them, even though MiniCPM5-2B was announced on 2026.09.07 and MiniCPM5-1B on 2026.05.19, which makes the gap hard to ignore in a project whose primary language is listed as Jupyter Notebook. The consequence is concrete rather than cosmetic. You get no reference notebook for the model currently being pushed, so you assemble the load call yourself from the cookbook for whichever engine you chose. Older notebooks target earlier generations.
quantize/ is routed to BitCPM4, not to the 2B card
A top-level quantize/ directory sits next to docs/, finetune/, minicpm_sala/ and skills/. The README's quick links route BitCPM4 quantization and MiniCPM4 applications to ./docs/README-legacy.md, so that directory may belong to an older compression line rather than the current card. Prebuilt weights narrow the gap, because the download table offers MiniCPM5-2B-GGUF and MiniCPM5-2B-GPTQ alongside the BF16 original. If your target is a llama.cpp workflow or a GPTQ serving stack you have something loadable today and need nothing from the scripts. If you need another bit width, another format or a calibration set of your own, check whether quantize/ applies to the 5 series before relying on it.
Tool use is claimed as a strength, but no tool-call format is published
The highlights list tool use and agentic tasks among the areas where the 2B card shows its advantages over models of comparable size, and the repository backs the claim with a dedicated top-level tool_parsers/ directory plus the 500K-sample UltraData-SFT-Agent-2609 agent dataset. Both MiniCPM5 releases were also published with deployment and fine-tuning Agent Skills under a top-level skills/ directory. The difficulty is fragmentation across directories. Three separate directories, skills/, finetune/ and tool_parsers/, each own a slice of one workflow.. That matters the moment you attach an agent harness, because an integration expecting OpenAI style function calls with names and arguments as JSON cannot be assumed to work, and if the parsers emit a different representation you are writing or swapping a parser instead of passing a base URL. Check the format your engine cookbook expects before you write the loop that calls your tools.
Two hosting orgs with different capitalization, and release tags that skip three versions
Every MiniCPM5-2B and MiniCPM5-1B artifact is published twice, once under openbmb on Hugging Face and once under OpenBMB on ModelScope, so the same model has two URLs that differ in capitalisation. Any script, Dockerfile or lockfile that hardcodes one org string fails against the other mirror, and a retry that assumes the fetch was transient will not fix a path that was wrong from the start. Version tags are no cleaner. The published releases are 5.0 for MiniCPM5-1B dated 2026-05-26 and 2.4.2, labelled as the first release, dated 2025-07-01, with no 3.x or 4.x tag between them, so tag numbers do not track model generations and pinning a 2.x release gets you the 2025 stack. The repository is not archived and the last push to main landed on 2026-09-21, close enough to today that the download table and the skill set can still change under you.
Editorial conclusion
MiniCPM5-2B fits if you are targeting a phone, an edge box or a Mac, and you want the training corpus to inspect alongside the weights. It is the wrong entry point for multimodal work or for teams that want one documented environment instead of a cookbook per engine. Before committing, confirm which checkpoint and format your loader actually accepts, and take the install command from the docs/deployment/ cookbook for your engine rather than from the top-level requirements.txt.
Frequently asked questions
What is the MiniCPM model?
MiniCPM is OpenBMB's family of small on-device models. The current release is MiniCPM5-2B, a dense 2B Transformer built by scaling up the same training recipe as MiniCPM5-1B, with weights offered in BF16, GGUF, MLX and GPTQ formats.
How does MiniCPM compare to other LLMs?
The Highlights section claims state of the art among open-source models of similar size, staying competitive with 4B-class models, and names coding, mathematics, long-context understanding, tool use and agentic tasks as the advantages. The 2024.09.05 MiniCPM3-4B entry names Phi-3.5-mini-instruct, GPT-3.5-Turbo-0125, Llama3.1-8B-Instruct, Qwen2-7B-Instruct and GLM-4-9B-Chat, and the 2024.02.01 MiniCPM-2B entry names Mistral-7B, Llama2-13B, MPT-30B and Falcon-40B.
is minicpm good
It depends on the constraint you are solving. The team positions MiniCPM5-2B for on-device, local, resource-constrained deployment, claims advantages over comparable-size models in coding, mathematics, long-context understanding, tool use and agentic tasks, and claims it stays competitive with 4B-class models overall.
minicpm vs qwen
The Highlights section compares against unnamed open-source models of similar size and against 4B-class models. The one entry naming Qwen is the 2024.09.05 MiniCPM3-4B release, which lists Qwen2-7B-Instruct among 7B to 9B parameter models it is compared against, next to Llama3.1-8B-Instruct and GLM-4-9B-Chat.
minicpm vs llava
The current cards in this repository are dense Transformers. Vision work lives in the separate MiniCPM-V repository linked from the README, and requirements.txt still lists Pillow, timm and sentencepiece under a heading for MiniCPM-V inference.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openbmb-minicpm)Star history chart for your README
[](https://hysenlabs.com/projects/openbmb-minicpm)Was this useful?