llm_interview_note ships no licence file and no releases
Mainly documents knowledge and interview questions for LLM algorithm (application) engineers.
At a glance
- What is it?
- This is a set of Chinese-language notes on large language model engineering, organised as ten numbered chapters and published as a static site rather than as code. The depth is uneven by design: distributed training gets nine entries, architecture gets six subsections, and the training-data chapter lists a single note. Alongside the notes sit four practice repositories and a deployed small model, so the author's actual curriculum is the combination rather than the notes alone.
- Who is it for?
- The notes suit someone preparing for an LLM engineering interview who wants the shape of the field mapped before reading papers, and who will check anything important against a primary source. Two things to know before relying on them.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 152 days ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
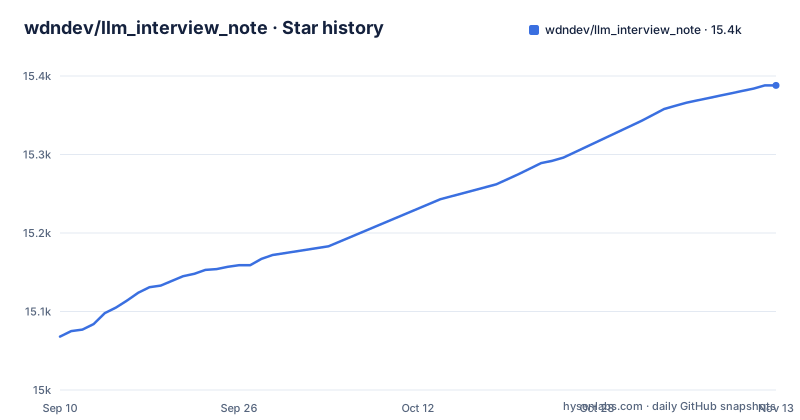
- wdndev/llm_interview_note15,388 ★ · +320
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| wdndev/llm_interview_note | 15.1k | 15.4k |
320 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
There is no licence file anywhere in the tree
List what is at the top of the repository and look for a licence.
There are ten numbered chapter directories, two numbered appendices for related courses and reference materials, the readme, two navigation files, the site entry point, a directory of generated notes, and a file that disables processing for the site generator.
There is no licence file. And the licence recorded as metadata for the project carries no value either.
That combination means there is no grant of any kind. In the absence of a licence, the default position under copyright is that you may read a public repository but not copy it, redistribute it, or build on it. Publishing the material on a public site does not change that, and neither does it being open in the sense of readable.
So this is a distinction worth being clear about. The project is open in the sense that anyone can read it and anyone can check the author's work. It is not open in the sense of having terms that permit reuse.
If you want to fork it, mirror it, quote it at length, or use the structure for your own notes, that is a question for the author rather than something the repository settles.
There is a companion repository for general machine learning notes that the front page links alongside this one, so the same question applies across the set.
The author states the answers are their own and invites corrections
There is a short note near the top of the readme that establishes what kind of document this is.
It says the repository covers concepts related to large model interviews, that it was compiled by the author from web resources, and that the answers were written by the author, with a request that anyone who finds something unreasonable point it out and suggest a fix.
That is an unusually direct epistemic statement to make about your own reference material, and it does more work than a disclaimer normally would. It tells you three things at once: the material is second-hand in its sources, the synthesis is first-hand, and the author is not claiming the answers have been checked.
For an interview preparation document that framing is arguably the right one. The value is not in the answers being authoritative but in them being organised around what gets asked, and in a reader knowing which claims to verify before repeating them in an interview.
It does mean the material carries the same status as any set of personal study notes. If a question matters for your preparation, read the primary source rather than the summary, and use the structure as a map rather than the content as authority.
Distributed training gets nine entries and the application chapter is the thinnest
The chapter structure is the clearest signal of what this field asks about, because the depth is not even.
Chapter four, on distributed training, has nine numbered entries: an overview, data parallelism, pipeline parallelism, tensor parallelism, sequence parallelism, multidimensional hybrid parallelism, automatic parallelism, parallelism for mixture-of-experts models, and a summary. It then adds sections on one widely used training framework, on a well-known tensor-parallel framework, on training acceleration, on useful articles, and on interview questions including one specifically about memory.
Chapter one, on foundations, has five subsections covering language models, tokenisation and word vectors, basic language model knowledge, deep learning, and a set of questions.
Chapter two, on architecture, is the widest in absolute terms, with subsections on the transformer itself broken into six parts, then attention variants, decoding strategy, one well-known encoder-only model, common large models, and mixture-of-experts material including several papers.
So the emphasis is on training and architecture, with the three-part mixture-of-experts treatment in chapter two and the nine-part parallelism breakdown in chapter four telling you where the questions actually come from. Applications, retrieval, evaluation and reinforcement learning each get a chapter or two.
That distribution is more informative about the interview market than the individual answers are.
The architecture chapter stops at Llama 2 and 3, which dates the notes
Read the chapter on common large models and the practical sections of the fine-tuning chapter together, and the vintage becomes visible.
The architecture chapter has entries for the Llama model family, another well-known open model family, a code walkthrough of Llama 2, and Llama 3.
The practical fine-tuning chapter has two worked examples: fine-tuning Llama 2, and fine-tuning a Chinese open model at version 3.
So the hands-on material is written against Llama 2 and a generation-3 open model, and the newest model named in the common-models section is Llama 3. The default branch last took a push on 2026-06-14.
There is no release history here and no changelog file, so the only signal of currency is the commit date, and a commit date on a documentation repository is weak. It tells you someone edited something, not that anything was reviewed.
The practical consequence is that the theory chapters, which cover decoder-only architectures, attention variants and decoding strategy, remain largely valid, while the framework-specific and model-specific parts are as current as the last time the author updated them. Check those against current documentation before you rely on them.
This is the normal half-life of personal notes, and it is worth stating rather than discovering during an interview.
This is a published site, so there is nothing to build or install
Look at what the repository is made of and the tooling question answers itself.
The primary language recorded for the project is HTML. At the top level there is a site entry point, a navigation file, a sidebar file, and a file whose name is the conventional opt-out for a site generator, which tells the host not to process the site itself.
So this is a static site published to a project's pages domain, and the readme links an online reading address rather than describing a build.
There are no dependencies to install, no test suite, no container and no configuration. If you want to read it you open the site, or you clone and read the Markdown in any viewer, since the chapters are directories of notes with a navigable index.
The one generated artefact directory is a set of notes converted to a portable document format, which is a convenience for reading rather than part of the build.
This shape has a practical upside worth naming. Because there is no build, there is no toolchain to become stale, and cloning the repository gives you the same content the website serves, with the Markdown files in the shape the author wrote them.
The real curriculum is four sibling repositories and a deployed model
The readme spends as much space pointing at other projects as describing this one, and that is the design.
There is a repository for building a small-parameter Chinese language model from scratch, described as covering pre-training, fine-tuning and reinforcement learning so you can practise on modest hardware.
There is a retrieval project implementing a simple system with multi-path recall and reranking.
There is a model context protocol project implementing both a server and a client using prompting and function calling, aimed at building agent projects quickly.
And there is a from-scratch implementation of a current open model family that can load the official released weights and debug on a local machine with sixteen gigabytes of memory.
That last detail is the one that makes the set coherent. The small Chinese model from the first repository is also deployed on ModelScope so anyone can try it.
So if you are deciding whether this is worth your time, the notes are the map and the four repositories are the practice. Reading the map without doing the practice gives you the same impression of understanding that reading documentation about a language always does, and the author clearly built the set to prevent that.
Agent is filed as a subsection of the retrieval chapter
One structural choice is worth noticing because it will save you looking in the wrong place.
Chapter eight is titled for retrieval-augmented generation, and it contains two subsections. The first covers retrieval augmentation, with entries on retrieval-augmented generation itself and on the technique by that name.
The second subsection is titled for agents, with a single entry on large model agent techniques.
So agent work is filed as an extension of retrieval rather than as a chapter in its own right.
That is a defensible taxonomy if you think of an agent as a loop that retrieves and acts, which is roughly how a tool-using agent works: it decides what it needs, goes and gets it, and acts. It also reflects how much of the practical agent literature in the period these notes were written was retrieval-shaped, with the difference being what happens between the retrieval and the action.
It does mean that if you are scanning the table of contents for agent material and do not read carefully, you will conclude the notes do not cover it. They do, in one file.
The same numbering quirk appears elsewhere, since two appendices are numbered in the high nineties for related courses and reference materials, so the last numbered chapter is not the last thing in the book.
Editorial conclusion
The notes suit someone preparing for an LLM engineering interview who wants the shape of the field mapped before reading papers, and who will check anything important against a primary source. Two things to know before relying on them. There is no licence file, so there is no stated permission to copy or redistribute the text, which matters if you were planning to build a study guide on top of it. And the author writes that the answers are their own and asks for corrections, so treat the content as working notes rather than reviewed reference.
Frequently asked questions
What are some common questions related to LLMs?
The notes group their question sets by chapter. The distributed training chapter is the most detailed, with notes on data, pipeline, tensor and sequence parallelism, hybrid parallelism, automatic parallelism and mixture-of-experts parallelism, plus question sets on distributed training and on memory. Other question sections cover natural language processing concepts, fine-tuning and pre-training, inference, and reinforcement learning including a set on RLHF.
What is LLM in brief?
The foundation chapter the notes build on covers language models, tokenisation and word vectors, word embeddings and a Chinese word-segmentation library, part-of-speech tagging, parsing, and classic word vector approaches including Word2Vec and the three main neural feature extractors. It also contains a section on why large language models use a decoder-only architecture.
What are some common interview questions about fine tuning in LLM programs?
The fine-tuning chapter has a theory section covering basic concepts, prompting, adapter tuning and low-rank adaptation, a practical section with worked examples of fine-tuning two model families, and a question set split into fine-tuning and pre-training. The reinforcement learning chapter carries a further set covering preference optimisation from human feedback.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wdndev-llm-interview-note)Star history chart for your README
[](https://hysenlabs.com/projects/wdndev-llm-interview-note)Was this useful?