GeoAI publishes under three names, and the change-detection library it advertises is commented out in its own requirements file
GeoAI: Artificial Intelligence for Geospatial Data
At a glance
- What is it?
- GeoAI is a MIT-licensed Python package for applying deep learning to geospatial data, with a QGIS plugin, an agent toolkit and a container image in the same repository. The distribution name differs between registries, the base requirements list contains two commented-out libraries one of which the README names as an integration, three separate version mechanisms assign the number, and the container installs the published package and then overwrites it from source.
- Who is it for?
- Use GeoAI if you want one high-level interface over the usual geospatial deep learning stack rather than assembling it yourself, and if you are working in Python 3.12 or newer. The six capabilities it claims, imagery search and download, dataset preparation with chips and labels, training, inference, visualisation and a desktop plugin, are the standard pipeline and having them behind one import is the point.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
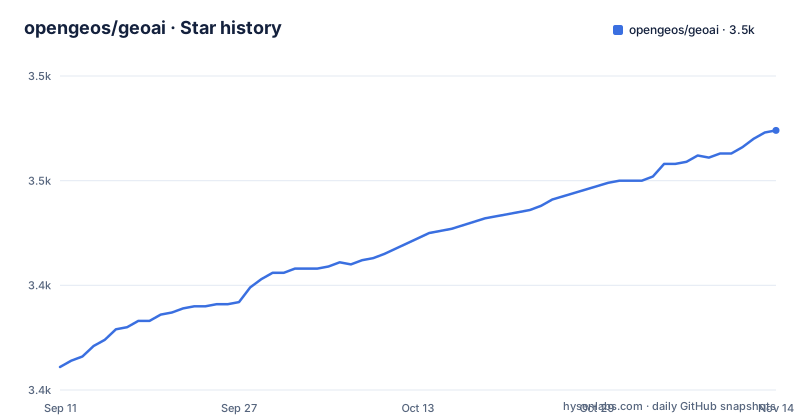
- opengeos/geoai3,474 ★ · +113
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| opengeos/geoai | 3.4k | 3.5k |
113 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One project, three distribution names
The repository is named for the package without a suffix. The package on the Python registry has a suffix. The package on the other registry does not.
The manifest's name field is the suffixed one, and the console script it installs is named after the unsuffixed one. The README's badges point at the suffixed package on the registry's old web domain, at the unsuffixed package on the other registry twice, and at the feedstock repository that builds the other-registry package.
So a reader who searches for the repository name finds a package that does not match it, and a reader who installs from the other registry gets a different name for the same code.
Two of those names are also legacy in a smaller way. The badge for the first registry uses that registry's retired web domain rather than its current one, so the link resolves through a domain that no longer serves package pages.
None of this is unusual for a project that published first on one index, and none of it is documented in the README either.
The library the README promotes is commented out in the requirements file
The introduction names the frameworks GeoAI integrates, and one of them is switched off in the file that installs them.
The list is a deep learning framework, a transformer library, a segmentation model library, and then a phrase about specialised geospatial libraries for change detection, with a link.
Here is what the requirement file actually contains.
# segment-geospatial
# torchange
Both of the two commented lines are in that list. The change-detection library the introduction promotes is one of them.
The rest of the requirement file is thirty entries with floors on about five, which is a reasonable shape for a package of this size. It also includes a headless build of the computer vision library, which is the correct choice for a package meant to run in a container or a notebook server.
But the comment is not explained. There is no note saying the library is optional, or that it is broken, or that it is installed through one of the extras. The introduction presents it as an integration, and the requirement file removes it, and the two statements are four hundred lines apart in two different files.
Three version mechanisms and a table named tool with nothing in it
Count how many things assign this project's version number.
The manifest declares a version and also declares its dependencies dynamic. A separate configuration section for a version-bumping tool sets a current version and tells it to commit and to tag, with a tag name template.
And the container image sets an environment variable that tells a different tool what version to pretend the package has, hard-coded to zero point zero point zero, with a comment about what happens when the version-control directory is missing from the build context.
So the version lives in the manifest, is maintained by one tool, and is overridden at image build time by another. Three mechanisms for one number.
In the same file there is a table whose only content is its own name. An empty section named tool appears between the entry-points table and the packaging configuration, with nothing under it.
That is harmless to every tool that reads it and alarming to a human reading the file, because a section named for a namespace and containing nothing looks like a merge accident. It also tells you the file is edited by several people who each added their own section and nobody removed the empty one.
A universal wheel for a package that requires Python 3.12
One line in the packaging configuration contradicts the line above it.
The project requires Python 3.12 or newer, and its classifiers enumerate three interpreter versions starting at 3.12.
Then the wheel configuration declares itself universal.
A universal wheel is the old convention for a wheel that works on any Python version, from the era when a package could support both major versions of the language at once. It marks the artefact so that installers can skip the version check.
For a package that cannot run on anything older than 3.12, the declaration buys nothing. The interpreter requirement will be enforced by the resolver regardless, so nothing is gained functionally, and what is lost is a signal: an installer or a tool that reads only the wheel tag will see a wheel that claims compatibility with every Python.
It reads like a default left in a template from years earlier, which is consistent with a project whose configuration also carries an empty section and three version mechanisms.
The container installs the published package and then overwrites it
The container is built in seven numbered sections, and section five is the interesting one.
The base is a notebook server image, tagged with the floating latest tag. Git is installed as the only system package. Then the package and one of its data dependencies are installed from the other registry into the base environment, and permissions are fixed.
Two environment variables are set for the geospatial libraries' data directories, and a third for a local tile server's URL prefix. The source is copied in, and the working directory moves there.
Then section five deletes the source tree's build metadata directory and installs the project from source with pip.
So the image contains two installations: the one from the other registry, which brought its own transitive dependency tree along, and the one from the source that was just copied in, which shadows it. The first install is not removed; it is overwritten in import order at best and coexisting at worst.
The version recorded by that second install is not the project's version. An environment variable tells the version tool to pretend it is zero point zero point zero, so a container built today reports a different version than the release it came from.
The base requirements include a notebook proxy and a tile server
Look at what the base requirement list installs and the shape of the package becomes clear.
There are the obvious modelling entries: the deep learning framework with a floor, the transformer library with a floor, a tokenizer library with a floor, a vision library, a training-data library with a floor, and the usual numerical and geospatial stack.
There are also four entries that have nothing to do with modelling. A notebook server proxy. A local tile server, which also appears in the optional extras with an exact version pin. A map library and a map rendering library. And a progress bar.
That is a serving stack, not a library stack. The package is built to be run, not only imported, and the requirement list reflects that: you install it and you get a way to look at your results in a browser.
Which also explains the container image. It is built from a notebook server base, installs the package from a package index, sets a tile server path prefix as an environment variable, and runs as a non-root notebook user. The Dockerfile is not packaging a library for someone else's application; it is packaging the application's own runtime.
Three transitive dependencies are floored because of security alerts
The resolver configuration contains three minimum versions and one comment explaining why.
The comment says the constraints exist to enforce minimum versions for transitive dependencies so that security alerts can be resolved. The three packages named are an asynchronous HTTP client, a general HTTP client, and a cryptography library, with floors at versions well above their long-standing defaults.
Flooring transitive dependencies is unusual, because those packages are chosen by other libraries and pinning them in the consuming project is a way to fight the resolver. Here it is deliberate and documented, which makes it defensible: the project wants a known-safe floor for three packages that its own dependencies pull in indirectly.
Two things are worth noting. First, these floors live in the unified-archive resolver's configuration, not in the requirement file, so a pip-only install of the package gets the default transitive versions rather than the safe ones. Second, the requirements file does carry floors for five other packages, so the project does both, using two mechanisms for the same intent.
Nothing here is wrong. It is the shape of a project that depends on a wide stack and has had to react to advisories in it.
The competitive case names three projects and calls them excellent
The statement of need is the most useful paragraph in the file, because it names its competitors.
It lists three existing projects by name and link, and says they provide excellent foundational tools for geospatial deep learning. Then it says there remains a gap for comprehensive, high-level interfaces, and positions this package as filling it.
That is an unusually clean positioning statement: acknowledge the foundations, claim the interface layer. The three named projects are all real and all plausibly foundational, and naming them with links is the honest way to differentiate.
What is missing is any comparison on substance. There is no statement of which tasks each project handles better, no feature matrix, no migration note. The argument is that the foundations are excellent and the interface is missing, which is a claim about a gap rather than a claim about a difference.
For a reader choosing between them, that means the README tells you who not to use instead of what to use it for. It also explains the shape of the package itself: it is a wrapper by design, and the wrapper's case for existing is that the wrapped things already work.
Editorial conclusion
Use GeoAI if you want one high-level interface over the usual geospatial deep learning stack rather than assembling it yourself, and if you are working in Python 3.12 or newer. The six capabilities it claims, imagery search and download, dataset preparation with chips and labels, training, inference, visualisation and a desktop plugin, are the standard pipeline and having them behind one import is the point. Three things to check before you install. Which distribution you actually get, because the repository, the PyPI name and the conda-forge name are three different strings and only one of them matches the repository. Which optional extras your task needs, since there are about ten groups and the agent toolkit alone pulls three model providers. And what the base install actually contains, because the requirement list is thirty entries long and includes notebook-serving and tile-serving infrastructure rather than only modelling libraries, which tells you the package is as much an application as a library.
Frequently asked questions
what is GeoAI
It is a MIT-licensed Python package for applying artificial intelligence to geospatial data, bridging deep learning with satellite imagery, aerial photographs and vector data. It claims six core capabilities: search and download of remote sensing data, dataset preparation with image chips and labels, training for classification, detection and segmentation, inference on new datasets, interactive visualisation, and a QGIS plugin. It integrates PyTorch, Transformers, a segmentation model library and a change-detection library, and its site is at opengeoai.org.
how to use geoai in qgis
The package ships a dedicated QGIS plugin, described as letting users run AI-powered geospatial workflows directly inside the QGIS desktop environment without writing code. The plugin has its own directory in the repository and its own page linked from the README badges, and it is the sixth of the package's six core capabilities.
Is GeoAI free?
The manifest declares the MIT licence and the README carries an MIT badge. There is no statement about paid tiers. The README does ask readers to cite a Journal of Open Source Software paper and an independently published book to support the author's work, and the book is listed with a separate PDF edition and print edition identifier.
how to install geoai
The README's badges point at three channels: a package on the Python registry under a suffixed name, the same code on a conda-forge channel under the unsuffixed name, and the feedstock repository that builds the conda-forge package. The manifest requires Python 3.12 or newer and classifies 3.12, 3.13 and 3.14. The repository also ships a container image built from a notebook server base.
What does GeoAI depend on?
The base requirement file has about thirty entries with floors on about five, including a floor on the deep learning framework, the transformer library, the tokenizer library and a training-data library, plus a headless build of the computer vision library. Ten optional extras add more, including an agent toolkit with three model providers, an inference server, a detector and a super-resolution model. Three transitive dependencies are floored in the resolver configuration because of security alerts, which an install that does not use that resolver will not get.
Which geospatial formats can GeoAI read and write?
The introduction names GeoTIFF, JPEG2000, GeoJSON, Shapefile and GeoPackage among the supported input formats. Segmentation results can be exported to GeoJSON, Shapefile, GeoPackage and GeoParquet. The data preparation section also describes vector-to-raster and raster-to-vector conversion utilities aimed at model training workflows.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opengeos-geoai)Star history chart for your README
[](https://hysenlabs.com/projects/opengeos-geoai)Was this useful?