ART: serverless RL with pinned torch, and six notebooks with no comparison
Agent Reinforcement Trainer: train multi-step agents for real-world tasks using GRPO. Give your agents on-the-job training. Reinforcement learning for Qwen3.6, GPT-OSS, Llama, and more!
At a glance
- What is it?
- ART is a Python framework for training multi-step agents with GRPO, sold on a managed backend. The version pins in its optional dependency groups and the empty benchmark cells in its notebook table are the two things to read before you budget GPU time.
- Who is it for?
- Adopt ART when you want to try GRPO on an agent task without owning GPUs, and accept that the base model, the reward function and the evaluation are yours to write. Do not adopt it on the strength of the vendor cost and speed figures, since the README gives no baseline to compare them against and most notebook rows have no comparative performance.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
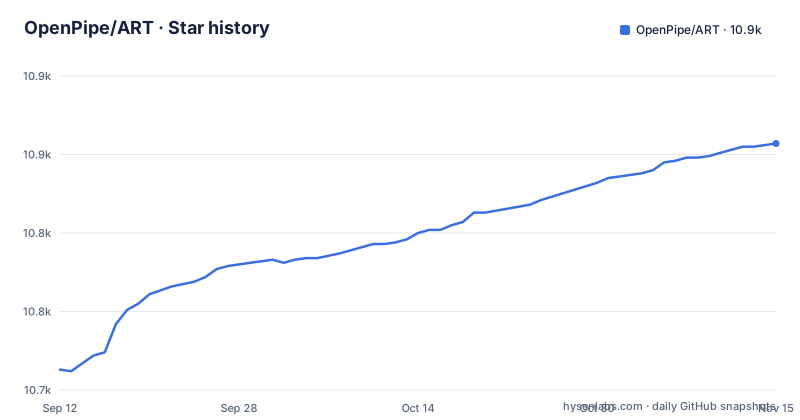
Star history
- OpenPipe/ART10,857 ★ · +144
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| OpenPipe/ART | 10.7k | 10.9k |
144 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The whole first run is a model, a backend and a register call
The README's quickstart is the shortest useful description of the API. You name a base model on a `TrainableModel`, construct a backend, and register one against the other:
from art.serverless.backend import ServerlessBackend

model = art.TrainableModel(
  project="voice-agent",
  name="agent-001",
  run_name="agent-001",
  base_model="Qwen/Qwen3.6-27B"
)

backend = ServerlessBackend(
    api_key="your_wandb_api_key"
)
model.register(backend)
Three things are decided by that call. `base_model` picks the weights training starts from, so a project is defined by which models you can load. `project`, `name` and `run_name` are three separate labels, which means a single named agent can accumulate runs and the naming of those runs is your problem, not the tool's. And the backend is an object you can swap, since the environment file's opening comment refers to a local backend for an ssh session while the notebook table labels two of its rows as serverless.
What the snippet does not contain is the part that decides whether training works: the rollout environment and the reward function. The framework is a harness for GRPO, and the harness is what you are getting.
Serverless RL is sold on a cost figure with no baseline attached
The pitch for the hosted path is W&B Training, described as the first publicly available service for flexible reinforcement learning training, with training and inference infrastructure managed so you focus on data, environment and reward function.
The claims are specific numbers. 40% lower cost, attributed to multiplexing on a shared production-grade inference cluster. 28% faster training, from scaling to 2000 or more concurrent requests across many GPUs. Instant deployment, with every checkpoint available through W&B Inference. The framing before the code block is a `RuntimeError: CUDA error: out of memory`, which tells you the comparison case is a self-managed GPU box that ran out of memory.
Read those figures as the vendor's own claims: the Key Benefits list gives no baseline or workload for the 40% or the 28%. The defensible part is the mechanism: sharing an inference cluster is how the cost claim could be true, and multiplexing is the reason a training run is not waiting on a single dedicated GPU. What you cannot check from here is whether your workload behaves like the one in that claim.
The backend extra pins torch, unsloth and transformers to exact versions
The dependency groups in `pyproject.toml` are the part of this project most likely to cost an afternoon. The base install carries libraries for calling models and moving data around, including `anthropic>=0.77.0`, `openai>=2.14.0,<3`, `litellm>=1.71.1,<=1.82.0` and `polars>=1.26.0`. GPU work is not in that list. It arrives with extras, and the `backend` group pins hard:
- `torch==2.11.0+cu128` on Linux and Windows, `torch==2.11.0` on macOS - `unsloth==2026.3.3` and `unsloth-zoo==2026.3.1`, pinned to a dated build - `transformers==5.2.0`, plus `accelerate==1.7.0` and `torchao==0.16.0` - `bitsandbytes>=0.45.2,!=0.50.0`, with one specific release excluded - `trl==0.20.0`, `wandb==0.28.0` and `peft>=0.14.0`
Every one of those is an exact pin except the two that are bounded. That is a deliberate choice in a stack where the layers below are versioned together, and the cost shows up the moment a transitive dependency releases a new version: the resolver is not free to move, and if a pin goes stale your options are a patch release from this project or a fork. The two CUDA groups are the sharp edge. `distributed` asks for `torch==2.11.0+cu128` on Linux and `distributed-cu130` asks for `torch==2.11.0+cu130` on Linux, so installing both extras on that platform asks for two different torch builds at once.
Platform markers put the GPU path on Linux and Windows, not macOS
Every CUDA dependency in this project is gated by a platform marker, and reading them together tells you which machine can actually train. The `distributed` extra asks for `torch==2.11.0+cu128` where `sys_platform == 'linux' or sys_platform == 'win32'`, and for plain `torch==2.11.0` on `darwin`.
So on a Mac the same install resolves to a CPU build of the same torch version. Nothing fails, which is worse: the install succeeds and you discover the absence of CUDA when the run is slow. The `distributed-cu130` group is narrower still, with its CUDA pin restricted to `sys_platform == 'linux'` and no marker for anything else, so on a Mac there is no CUDA torch to resolve at all and the group contributes nothing but the non-torch entries.
The floor for the language is higher than most projects in this space. `requires-python = ">=3.12"` applies to the whole package, base extras included, so an environment on 3.11 is excluded before any of this matters. The practical reading is that this is a Linux-first tool: the local paths, the multi-node examples and the CUDA groups all assume you are somewhere the accelerators are.
Ten example notebooks, and six with the comparison left as Link coming soon
The entry point for trying ART is a table of Colab notebooks, one per task, and reading the table closely says more about the project's maturity than the feature list does.
The tasks are real agent work rather than toy prompts. A Qwen 3.8 27B agent learning to search email, the same model learning to play 2048, a Qwen 2.5 7B LangGraph agent doing email search, a Qwen 2.5 3B model mastering the NWS MCP server, Tic Tac Toe and Codenames with 3B models, a Temporal Clue puzzle, a distillation notebook going from Qwen 3 235B to Qwen 3.8 27B, and a summarizer warmed up with SFT before RL. Separate directories under `examples/` back these up, including `multinode/`, `mcp-rl/`, `openenv_echo.py` and a self-play variant of Tic Tac Toe.
Now the column that should help you decide. Of the ten complete rows, six carry a comparative performance cell that says `Link coming soon`, including the LangGraph and MCP rows. Only 2048, Tic Tac Toe, Codenames and ART•E have benchmark notebooks linked. The consequence is direct: if your question is whether GRPO training beats a prompted baseline on your task, this repository does not answer it, and the cells that would have are unfilled. The repository description also advertises Qwen3.6, GPT-OSS and Llama while every listed notebook trains a Qwen model, so treat the model range as aspirational until you see the weights load.
Your first run needs a W&B key, and a gated model needs a HuggingFace token
The `.env.example` file is the honest inventory of what this project asks of your machine, and it names several separate providers.
WANDB_API_KEY=YOUR_WANDB_API_KEY
HF_TOKEN=YOUR_HUGGINGFACE_TOKEN
OPENPIPE_API_KEY=YOUR_OPENPIPE_API_KEY
TOGETHER_API_KEY=YOUR_TOGETHER_API_KEY
`WANDB_API_KEY` is the one you cannot avoid on the serverless path, since `ServerlessBackend` takes an `api_key` argument. `HF_TOKEN` is optional for most models and, per the file's own comment, necessary for gated ones such as Llama 3.1, so training a gated base model converts an optional variable into a required one. `OPENPIPE_API_KEY` and `TOGETHER_API_KEY` are marked optional, the latter for deploying a trained model to Together.
Two of those requests deserve a second look. `GITHUB_TOKEN` is listed because committing on a new machine may need write access to the private `agent-reinforcement-training` repository, which is a wider grant than reading public code. And the S3 block, `AWS_ACCESS_KEY_ID`, `AWS_SECRET_ACCESS_KEY`, `AWS_REGION` and `BACKUP_BUCKET`, exists for log and model backups, so a run that streams checkpoints to a bucket hands the cluster long-lived cloud credentials. If your environment policy counts cloud keys in a training job, that line is where the review starts.
Two inference runtimes sit in the tree, and the README names neither as the default
The repository layout suggests more infrastructure than the quickstart admits. Alongside `src/`, `tests/`, `docs/`, `dev/`, `docker/` and `scripts/`, there are two runtime directories, `megatron_runtime/` and `vllm_runtime/`, plus `requirements/`, a `uv.lock`, and `skypilot-config.yaml` with a `.skyignore`, which points at SkyPilot for launching the cluster. Agent instruction files sit at the top level as `AGENT.md` and `CLAUDE.md`, alongside `.agents/` and `.claude/`.
Between the two runtimes, SkyPilot configuration, a container directory and a requirements directory is the shape of a project that expects you to be running a cluster, not a laptop, even though the entry point is a Colab notebook.
Licence handling follows the pins. ART itself is Apache-2.0, and the tree carries `LICENSE`, a `licenses/` directory and a `THIRD-PARTY-NOTICES` file, which is what you would expect given that unsloth, bitsandbytes, torch, duckdb and pyarrow appear in the dependency groups. Before shipping a trained artefact, read those files, because your obligation is set by the pinned stack and not by the headline licence.
Editorial conclusion
Adopt ART when you want to try GRPO on an agent task without owning GPUs, and accept that the base model, the reward function and the evaluation are yours to write. Do not adopt it on the strength of the vendor cost and speed figures, since the README gives no baseline to compare them against and most notebook rows have no comparative performance. Before installing, decide which CUDA build you need, because `distributed` and `distributed-cu130` pin different torch releases and cannot coexist on Linux.
Frequently asked questions
What does ART do in Python?
ART is an open-source reinforcement learning framework that trains multi-step agents with GRPO, letting models learn from experience. You define the data, environment and reward function, and the harness handles the training loop.
How do I start training an agent with ART?
Create an `art.TrainableModel` with a project, name, run name and `base_model`, construct a `ServerlessBackend` with your W&B API key, and call `model.register(backend)`. The README points at Colab notebooks as the hands-on introduction.
What Python version and GPU platform does ART require?
`requires-python = ">=3.12"` for the whole package. CUDA builds of torch are marked for Linux and Windows, with a plain torch on macOS, and the `distributed-cu130` group pins a CUDA build for Linux only.
Can I install ART's distributed and distributed-cu130 extras together on Linux?
Not as written. The `distributed` group pins `torch==2.11.0+cu128` on Linux and `distributed-cu130` pins `torch==2.11.0+cu130` on Linux, so the two groups ask for different torch builds at once.
Does ART publish benchmark comparisons for its trained agents?
Partly. The notebook table links benchmark notebooks for 2048, Tic Tac Toe, Codenames and ART•E, while six of the ten complete rows show `Link coming soon` in the comparative performance column.
Is OpenPipe ART free or paid?
The repository is Apache-2.0 licensed and its own quickstart runs against a hosted W&B Training backend that requires a W&B API key. Check the W&B Training documentation linked from the README for the hosted service's pricing.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openpipe-art)Star history chart for your README
[](https://hysenlabs.com/projects/openpipe-art)Was this useful?