UCC collectives are enabled at launch, not at build time
Unified Collective Communication Library
At a glance
- What is it?
- UCC is a collective communication library written in C that sits underneath message passing stacks rather than replacing them. It builds with autotools, depends on UCX, can drive AMD and NVIDIA hardware offload engines alongside fabrics, and is switched on per component with a priority number on the launcher command line.
- Who is it for?
- UCC suits a cluster operator who wants one collective implementation underneath both message passing and shared memory programs, with hardware offload engines available without changing application code. It does not suit someone who wants collectives without building from source, since there is no package installation path in the documentation, only an autotools sequence.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
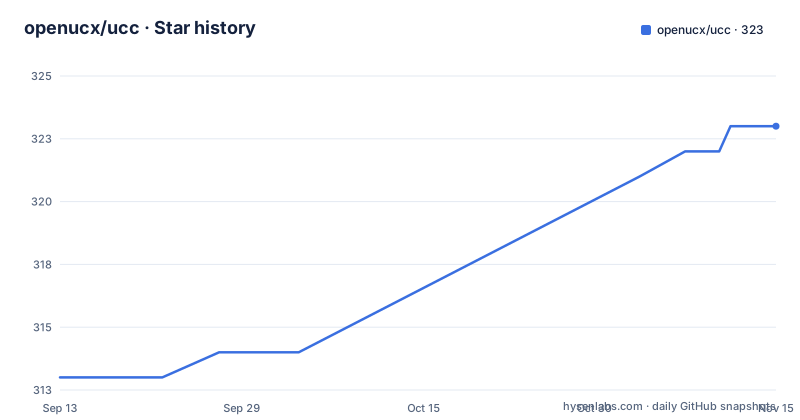
- openucx/ucc323 ★ · +10
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| openucx/ucc | 313 | 323 |
10 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Enabling UCC is a launcher flag with a priority number
The way UCC is switched on tells you most of what it is.
For a message passing program, two parameters are passed to the launcher: one enabling the UCC collective component and one setting its priority.
mpirun -np 2 --mca coll_ucc_enable 1 --mca coll_ucc_priority 100 ./my_mpi_appFor a shared memory program, the command is the same except the component prefix differs.
mpirun -np 2 --mca scoll_ucc_enable 1 --mca scoll_ucc_priority 100 ./my_openshmem_appThree things follow. First, activation is a runtime decision taken by the message passing layer, not a compile-time choice, so the same build can use a different collective implementation per job. Second, priority is numeric, which means UCC competes with the built-in components rather than replacing them, and 100 is a value chosen to win rather than a default. Third, both surfaces are named through the same mechanism, so a site that adopts UCC for message passing has one flag pattern to learn and a second to remember.
The two-rank example is the smallest case that exercises the wiring; a real run changes only the rank count.
The transport list mixes fabrics with hardware offload engines
The supported transports section lists seven entries, and they are not the same kind of thing.
One is the general-purpose component library, UCX over its point-to-point layer, and under it sit four fabrics: InfiniBand, RDMA over Converged Ethernet, Cray Gemini and Aries interconnects, and shared memory.
The other six are named individually. In-network aggregation appears as SHARP. Three GPU paths appear as CUDA, NCCL, and RCCL, which are the vendor collective libraries for NVIDIA and AMD hardware respectively. And MLX5 appears last, which is a specific vendor offload library rather than a fabric or a protocol.
So the list spans at least three levels: a transport abstraction, a network-attached processing engine, and vendor collective engines that offload work into the network card or the GPU.
That breadth is the point of the library as described, since its design goals name hardware collectives as a first-class citizen rather than an optimisation. It also means the meaningful question for an adopter is which of these your fabric can actually reach, since a shared memory node has none of them and a modern InfiniBand cluster has most.
One dependency is required and two accelerator toolchains are optional
The required packages section is short, and one entry carries all the weight.
The communication layer is required, and UCC uses the utilities that layer's separate descriptor component provides. Everything else is optional.
CUDA is optional and enables CUDA collectives, with a stated minimum toolkit version of 11.0 or above. HIP is optional and covers AMD GPUs, with the installation instructions delegated to the vendor documentation rather than restated.
Doxygen sits in the list but is neither a build dependency nor an accelerator dependency. It is there because UCC generates its API documentation with it.
That minimum CUDA version is a hard floor rather than a soft preference, and the repository carries a shell script whose name suggests it exists to compare CUDA versions. That matters for a library whose supported-accelerator list is part of its pitch: the toolkit version decides which of the seven transports you can actually compile.
Note also what is not listed. No MPI implementation appears as a build dependency, because UCC is consumed by message passing stacks rather than by applications, and the documented integration builds one explicitly as a separate step.
Two build systems coexist and the docs build still configures
The build section shows an autotools sequence, and the file listing shows a CMake directory beside it.
A developer's build is three steps: bootstrap, configure with an install prefix and a path to the installed communication layer, then make.
./autogen.sh
./configure --prefix=<ucc-install-path> --with-ucx=<ucx-install-path>
make
Documentation has its own path, and it is the interesting one. It runs the same bootstrap and the same configure, but replaces the path to the communication layer with a flag that asks for documentation only, and then runs a documentation target instead of make.
So a docs-only build still generates the configure script and still runs configuration. It avoids needing UCX installed, not needing the build system.
The file listing supports the two-build-system reading: an autoconf-style configure definition with a matching makefile template, a bootstrap script, a pkg-config template for consumers, and a CMake directory that arrived alongside. Formatting and static analysis configuration for the C sources are also at the root, which is what you would expect from a library that accepts outside patches.
The integration path means building three repositories in order
The Open MPI section is really a build order, and it is the part a new user needs most.
First the communication layer: clone it, change into it, bootstrap, configure with an install prefix, and install with parallelism.
Second UCC itself, cloned into the same style of sequence, with its configure pointing at the prefix where the communication layer was just installed.
Third the message passing stack, cloned from its own project, configured with paths to both, and installed.
The bootstrap script is not the same for all three. UCC and the communication layer use a shell script; the message passing stack uses a Perl script. That is a small thing that stops a copy-paste of the three blocks from working.
The message passing configure takes two path options rather than one, which confirms the layering: the stack needs the communication layer for its transport and UCC for its collectives, and neither is optional once you have decided to use them.
After all that, running is a launcher command, which is the same command from the previous section.
The design goal that matters is initialising once
Seven design goals are listed, and one of them is the reason a dedicated library exists at all.
That goal is repetitive collective operations, described as initialising once and invoking multiple times. In a loop-heavy application, a collective that re-initialises its buffers on every call pays that cost per iteration, and the overhead can dominate.
The others cluster around flexibility. Nonblocking operations that cover several programming models. A flexible resource allocation model. Support for a relaxed ordering model alongside a flexible synchronous one, so a caller can trade ordering guarantees for parallelism.
Two more are about scope and hardware. The first goal is scaling and performance for high performance computing, machine learning, and input/output workloads, which is three different bottlenecks rather than one. The last names hardware collectives as a first-class citizen, which is the same claim the transport list makes.
Read together, the goals are about being the layer underneath, not about being a new interface. There is no application-facing API described here, which is consistent with the whole integration story.
Contribution runs through two consortium policies and an automated reviewer
The contributing section is four sentences and two policy names.
Contributors are pointed at a single file for the technical and legal guidelines. Then a constraint is stated: all contributors must comply with two named policies from the consortium that governs the project, one a voluntary consensus standard for membership and one covering export-compliant contribution submissions.
That is unusual for a library hosted under an organisation, and it has a practical consequence. The export policy in particular is not a code-style matter, so a patch that touches certain areas may need review beyond the project's own maintainers.
The file listing shows the rest of the governance. An authors file and a news file sit at the root, which is the conventional way to record who did what and what changed in a project with a long history. A code style configuration and a static analysis configuration cover the C sources.
One configuration stands out: a file for an automated code review service, which means outside review is part of the pipeline rather than something bolted on later. There are also two separate continuous integration directories, suggesting more than one provider runs builds.
Editorial conclusion
UCC suits a cluster operator who wants one collective implementation underneath both message passing and shared memory programs, with hardware offload engines available without changing application code. It does not suit someone who wants collectives without building from source, since there is no package installation path in the documentation, only an autotools sequence. Before you commit, check which offload engine your fabric actually has, build UCX first since UCC configures against its install path, and remember that enabling the component is a launcher flag rather than a build option.
Frequently asked questions
How do I build UCC from source?
Run `./autogen.sh`, then `./configure --prefix=<ucc-install-path> --with-ucx=<ucx-install-path>`, then `make`. The communication layer must be installed first, and you point the configure at its install path. A documentation-only build uses the same bootstrap and configure with a docs flag instead of the path.
What does UCC require beyond a compiler and UCX?
UCX is the one required package, for the utilities in its descriptor component. CUDA 11.0 or above is optional and enables CUDA collectives, HIP is optional for AMD GPUs, and Doxygen is used to generate the API documentation. No message passing implementation is a build dependency.
How do I enable UCC inside Open MPI at run time?
With two launcher parameters: one enabling the UCC component and one setting its priority. For message passing programs the prefix is `coll_ucc_`, for shared memory programs it is `scoll_ucc_`, and the documented example enables the component and sets priority 100 with two ranks.
Which transports does UCC support?
The general-purpose component library over InfiniBand, RDMA over Converged Ethernet, Cray Gemini and Aries interconnects, and shared memory, plus in-network aggregation through SHARP, GPU paths through CUDA, NCCL, and RCCL, and a vendor offload library through MLX5.
What are the design goals of UCC?
Scalable, performant collectives for high performance computing, machine learning, and input/output workloads; nonblocking operations covering several programming models; a flexible resource allocation model; support for a relaxed ordering model; a flexible synchronous model; repetitive operations where you initialise once and invoke many times; and hardware collectives treated as first-class.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openucx-ucc)Star history chart for your README
[](https://hysenlabs.com/projects/openucx-ucc)Was this useful?