OVMS: a C++ inference server whose package.json still says MediaPipe
A scalable inference server for models optimized with OpenVINO™
At a glance
- What is it?
- OpenVINO Model Server serves language, vision and classic models over OpenAI-compatible and KServe endpoints, and the details worth reading are in the flags rather than the feature list: two spellings of the HTTP port, a documented client key of "unused", preprocessing baked into the launch line, and a leftover MediaPipe manifest.
- Who is it for?
- Two quick starts, one server, and the documentation is precise enough that a careful reader can predict how it will fail. Check the port flag your deployment scripts assume, because the language model path uses rest_port and the classic path uses port.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
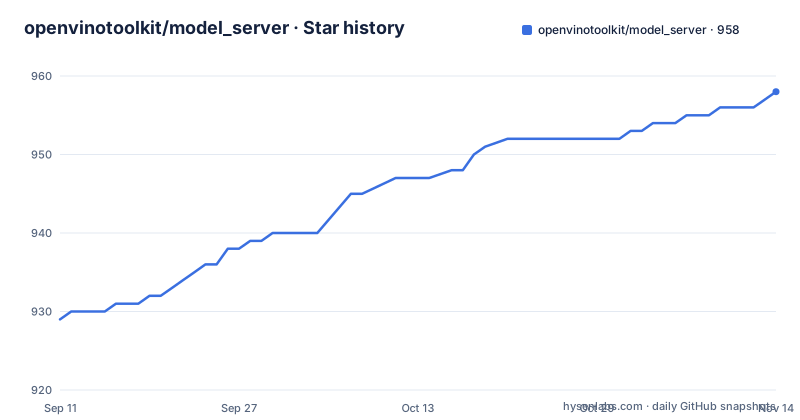
- openvinotoolkit/model_server958 ★ · +29
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| openvinotoolkit/model_server | 929 | 958 |
29 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The package manifest belongs to a MediaPipe repository
The repository that ships an Apache-2.0 C++ inference server, built with Bazel and released as v2026.4.0 on 2026-09-17, contains this at its root:
{
  "name": "medipipe-dev",
  "version": "0.0.0-alphga",
  "description": "MediaPipe GitHub repo",
  "devDependencies": {
    "@bazel/typescript": "^5.7.1"
  }
}
Two things are wrong with it on its face. The name and description belong to MediaPipe, and the version string misspells alpha, so `0.0.0-alphga` cannot be parsed as a prerelease tag. Its only dependency is the Bazel TypeScript toolchain, which also explains the `yarn.lock` sitting in a C++ project.
The confusion has a source. This server does support MediaPipe graphs, listed among the classic model formats alongside TensorFlow, ONNX, PaddlePaddle and OpenVINO IR, so a MediaPipe-named manifest is not impossible here. It is still a manifest that describes something other than what the tree contains, and any tool that reads a repository's package metadata, from a license scanner to a dependency auditor, will read that description first.
The same HTTP port has two flag names and the binary has two
The two quick starts in the root file set the listening port differently. Serving a language model ends with `--rest_port 8000`:
docker run --rm -p 8000:8000 \
  --user $(id -u):$(id -g) -v ${HOME}/models:/models:rw \
  openvino/model_server:latest \
  --source_model OpenVINO/Qwen3-4B-int4-ov \
  --model_repository_path /models \
  --rest_port 8000
Serving ResNet-50 through the KServe API ends with `--port 9000`, in the same position and doing the same job. A deployment script written against one quick start and reused for the other silently listens somewhere else, or not at all.
The Windows examples have the same split. The language model example invokes `ovms.exe`, while the classic model example invokes `ovms`. Both are described as the binary package, and the difference is never explained.
What is consistent across all four is the shape of the command: a model identity, a path to it, preprocessing values, and a port. That consistency is what makes the two port spellings and the two binary names easy to miss, since nothing else in the examples varies.
The reference client sends an unused key to a published port
The language model quick start publishes the container's port straight to the host and then queries it with the official OpenAI client:
client = OpenAI(base_url="http://localhost:8000/v1", api_key="unused")
stream = client.chat.completions.create(
    model="OpenVINO/Qwen3-4B-int4-ov",
    messages=[{"role": "user", "content": "What are the 3 main tourist attractions in Paris?"}],
    stream=True,
    extra_body={"chat_template_kwargs": {"enable_thinking": False}}
)
The key is literally the string `unused`, on `http://localhost:8000/v1`, reached through a `-p 8000:8000` mapping. The OpenAI client insists on a non-empty key, so a placeholder is needed to make the constructor happy, and nothing in this documented path adds a real credential. The `extra_body` field is the more informative part: turning thinking off is not a first-class parameter of the OpenAI schema, it rides along as a chat template keyword, which tells you the server is passing it to the model's own template machinery.
Compatibility is also split across two dialects. Text generation, embeddings at `/v1/embeddings`, image generation at `/v1/images/generations` and speech recognition and text to speech are described as OpenAI-compatible. Reranking is described as Cohere-compatible instead, so a client library that speaks only one of those two shapes covers part of the surface.
The model repository is mounted read-write and can fill itself from HuggingFace
The language model example passes `--source_model OpenVINO/Qwen3-4B-int4-ov` and does not download anything itself. The server fetches the model from HuggingFace on first start and writes it into the repository path, which is why the volume is mounted `:rw` and why the container runs as `--user $(id -u):$(id -g)` so the downloaded files belong to the host user rather than to root.
That single flag makes the first start of a language model a network operation with a disk side effect. The directory is created with `mkdir -p ${HOME}/models` before the container starts, and everything after that depends on the hub being reachable. The classic model quick start takes the opposite approach: two `curl -L` calls pull `resnet50.bin` and `resnet50.xml` into the working directory yourself, and the container mounts `${PWD}` read-write at `/models` while running as `-u $(id -u)`.
The repository abstraction is wider than either quick start. Local storage is one backend among several, alongside S3, GCS, Azure Blob and the HuggingFace Hub, and the repository supports model versioning plus hot-reload and online configuration changes. Note that HuggingFace appears twice, once as a manual download target and once as a repository backend, which means the same hub can be either a source you fetch or a location the server manages.
Preprocessing arguments belong to the launch line, not the request
The classic quick start puts image normalization in the server invocation:
docker run --rm -d -u $(id -u) -v ${PWD}:/models -p 9000:9000 \
  openvino/model_server:latest \
  --model_name resnet --model_path /models/resnet50.xml \
  --mean "[123.675,116.28,103.53]" --scale "[58.395,57.12,57.375]" --layout "NHWC:NCHW" \
  --port 9000
The mean and scale are the ImageNet channel values and the layout converts NHWC input to NCHW, all three fixed at startup. A client cannot send them per request, so correcting a normalization mistake means restarting the server with different arguments rather than fixing a payload.
The client side stays correspondingly thin. It opens the image as bytes and hands them over as an object array:
inputs = [grpcclient.InferInput("image", [1], "BYTES")]
inputs[0].set_data_from_numpy(np.array([image_bytes], dtype=object))
result = client.infer(model_name="resnet", inputs=inputs, outputs=outputs)
output = result.as_numpy("output")  # (1, 1000) FP32
Transport is gRPC through `tritonclient`, and the result is a raw `(1, 1000)` FP32 vector, so the `argmax` that turns it into a class label happens in the example, not on the server. The sample image itself comes from this repository's own demos directory, fetched over HTTPS from the raw content URL on github.com. Inference on the serving path is gRPC rather than the REST interface used for the language models, and the repository separately advertises gRPC streaming endpoints.
Windows is built by a dozen scripts that Linux does not have
The root tree is asymmetric in a way that shows where the packaging effort went. Linux has two Dockerfiles, `Dockerfile.ubuntu` and `Dockerfile.redhat`, and two matching driver scripts, `install_ubuntu_gpu_drivers.sh` and `install_redhat_gpu_drivers.sh`, plus `prepare_gpu_models.sh`, `prepare_llm_models.sh`, `run_unit_tests.sh`, `create_package.sh` and `install_va.sh`.
Windows has its own chain, and it is long: `windows_build.bat`, `windows_clean_build.bat`, `windows_create_package.bat`, `windows_install_build_dependencies.bat`, `windows_prepare_python.bat`, `windows_prepare_llm_models.bat`, `windows_test.bat`, `windows_parse_tests.bat`, `windows_setupvars.bat`, plus two Python helpers, `windows_set_ovms_version.py` and `windows_change_test_configs.py`. Environment setup is duplicated as well, with both `setupvars.bat` and `setupvars.ps1` present.
Two details from that chain are worth knowing before you build. Windows runs its own model preparation step, so language models are fetched during the Windows build rather than at first start as they are on Linux. And version stamping is a script, meaning the version in a Windows package is written by `windows_set_ovms_version.py` at build time.
GPU acceleration on Linux follows the same explicit pattern in both quick starts: switch to the `latest-gpu` tag and pass `--device /dev/dri --group-add $(stat -c '%g' /dev/dri/render* | head -n1)` so the container can reach the render device.
The Makefile counts cores two ways and its licence header has a stray word
Build parallelism comes from a core count that is computed differently per platform. On Darwin it is `sysctl -n hw.physicalcpu`. Everywhere else the Makefile shells out to `lscpu` and parses two lines with awk, reading cores per socket and the socket count, then multiplies them. Either way the result lands in `JOBS ?= $(CORES_TOTAL)`, so an exported `JOBS` overrides the guess and an unset one inherits it.
The same file carries a workaround with a large constant in it: `BUILDKIT_STEP_LOG_MAX_SIZE=500000000` and `BUILDKIT_STEP_LOG_MAX_SPEED=10000000`, commented as a fix for Docker clipping build step logs. Proxy settings are taken from the lowercase `http_proxy`, `https_proxy` and `no_proxy` environment variables rather than their uppercase forms, which is the shell convention rather than the HTTP one.
Style checking is configured with a long exclusion list. `STYLE_CHECK_OPTS` passes `--output=vs7` to cpplint, sets a line length of 120, and disables a dozen checks by name, among them include order, namespace indentation, string and whitespace rules, casting, explicit constructors and todo readability.
One artefact is worth reporting as an artefact. The Apache 2.0 header at the top of the Makefile ends its standard final clause with `limitations under the License.got`, so the word got is appended to the last line of the licence boilerplate. It changes nothing legally, and it is the kind of typo that survives because nobody reads the fourteenth line of a licence header.
Editorial conclusion
Two quick starts, one server, and the documentation is precise enough that a careful reader can predict how it will fail. Check the port flag your deployment scripts assume, because the language model path uses rest_port and the classic path uses port. Assume the documented endpoints carry no authentication, since the reference client passes an unused key against a published port, and put a gateway in front of it before it leaves a trusted network. Remember that mean, scale and layout are launch arguments rather than request fields, so changing preprocessing means a restart. And ignore the package manifest, which describes a MediaPipe repository and carries a misspelled version string.
Frequently asked questions
What is OpenVINO Model Server?
It is an Apache-2.0 C++ inference server from the OpenVINO project that exposes machine learning models over standard network APIs, targeting Intel hardware. It serves generative and agentic workloads such as LLMs, VLMs, image generation and audio, as well as classic models like object detection, classification and OCR.
Which API dialects does OpenVINO Model Server expose?
Text generation, embeddings at /v1/embeddings, image generation at /v1/images/generations and speech recognition and text to speech are OpenAI-compatible, while classic model inference uses the KServe APIs. Reranking is Cohere-compatible rather than OpenAI-compatible, so a client needs both shapes to cover the surface.
How do you set the HTTP port when starting OpenVINO Model Server?
The flag depends on which quick start you follow. The language model example uses --rest_port 8000, while the classic model example uses --port 9000, both at the end of the same command shape.
Does OpenVINO Model Server require an API key from clients?
The documented reference client passes api_key="unused" against http://localhost:8000/v1, because the OpenAI client requires a non-empty key. The quick start publishes the port to the host with -p 8000:8000 and adds no credential of its own.
Where does OpenVINO Model Server get models from?
The repository backend supports local storage, S3, GCS, Azure Blob and the HuggingFace Hub, with model versioning and hot-reload on top. The language model quick start passes --source_model OpenVINO/Qwen3-4B-int4-ov and lets the server download it from HuggingFace into the repository path on first start.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openvinotoolkit-model-server)Star history chart for your README
[](https://hysenlabs.com/projects/openvinotoolkit-model-server)Was this useful?