alibaba/zvec: an in-process vector database that trades a server for a file path
A lightweight, lightning-fast, in-process vector database
At a glance
- What is it?
- Zvec is an embedded C++ vector database with Python, Node.js, Go, Rust and Dart SDKs, Apache-2.0 licensed, and it puts dense vectors, sparse vectors, full-text search and structured filters behind one local collection object. The judgement: it fits single-writer applications that want ANN search without operating a service, and it is the wrong tool the moment you need concurrent writers or a shared index across machines.
- Who is it for?
- Adopt zvec if your application is the only writer to its index and you want vector, sparse and full-text search without a separate service to deploy: the Python quickstart is a pip install, a CollectionSchema, and a create_and_open call on a local path. Do not adopt it if two processes must write the same collection at once, since the README states writes are single-process exclusive, or if you need a network endpoint that many clients share.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
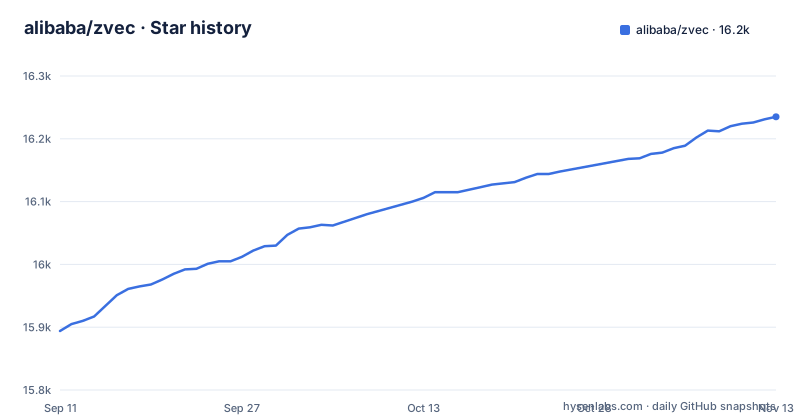
Star history
- alibaba/zvec16,235 ★ · +341
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| alibaba/zvec | 15.9k | 16.2k |
341 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The server you delete, not the database you add
Most vector search deployments start with a service. You provision a node, expose an endpoint, manage credentials, and then write application code whose only job is to make a network round trip to an index that lives somewhere else. For a laptop tool, a CLI, a notebook, a mobile app or a single-process agent runtime, that entire layer is overhead. Zvec removes it. The README describes the project as an in-process vector database designed to embed directly into applications, and the quickstart bears that out: a collection is created at a filesystem path, not registered with a server. The audience is therefore narrow and specific. It is the engineer building a retrieval component inside a larger program, who wants approximate nearest neighbour search, keyword search and metadata filtering available as function calls in the same process, and who is willing to accept the constraints that come with owning the storage file. If you need a shared index that ten services query over HTTP, this is not the shape of tool you are looking for, and the README does not pretend otherwise.
Collections, schemas and where the vectors actually live
The unit of organisation is the collection. In the Python example, a CollectionSchema takes a name and a VectorSchema that declares a field name, a data type (VECTOR_FP32 in the sample) and a dimension. Documents are inserted as Doc objects carrying an id and a mapping from field name to vector. Queries are constructed as a Query with a field_name and a vector, plus a topk argument. That is the whole surface for the simplest case, and it is deliberately small. What sits underneath is where the design decisions are. The feature list mentions dense and sparse embeddings, multi-vector queries, and a selection of index types that scale from memory to disk, with a link to a concepts page on vector index types. The v0.8.0 release notes name several of them: IVF, DiskANN, HNSW with RaBitQ, Vamana graphs and Uniform quantizers, and say DiskANN now extends to Windows, Android and iOS. Those are the mechanisms that determine whether your collection fits in RAM and how fast it answers, and they are selectable, which means the index type is a decision you make rather than a default you inherit.
Hybrid search is the actual differentiator, not the ANN index
Standalone ANN libraries are plentiful. The reason to pick zvec over a bare index library is the query layer. The feature list describes hybrid search as fusing vector similarity, full-text search and structured filters in a single query. That matters because real retrieval rarely reduces to cosine distance. You want the top-k nearest neighbours that also match a tenant id, or a keyword that must appear in the text, or both ranked together. Doing that outside the database means fetching a large candidate set and re-ranking it in application code, which is where latency and correctness bugs accumulate. Zvec's full-text search is described as native keyword search over string fields, with natural-language or structured expressions, and v0.8.0 embeds the default Jieba dictionary and HMM model, so Chinese tokenization needs no separate dictionary files or path configuration. This is the part of the project that a thin ANN wrapper cannot replicate, and it is the strongest argument for adopting the whole thing rather than a component of it.
Getting a collection open: the commands and the config surface
Installation is per language and the README lists them plainly. Python is pip install zvec, with a stated requirement of 64-bit Python 3.10 through 3.14. Node.js is npm install @zvec/zvec. Rust is cargo add zvec-rust. Dart and Flutter get it through flutter pub add zvec. Go bindings are linked from a separate repository rather than a package manager command. The README lists Linux, macOS, Windows, Android and iOS as supported platforms, and v0.8.0 added Intel Mac and Windows ARM64 builds, wheels and SDKs. The runtime configuration surface is small by design. You choose a path, you choose a schema, you choose an index type. There is no server config file, no port, no cluster settings. That is the pitch: the README says pure local, no servers, no config. The one configuration decision that carries real consequences is the index type, since that is what determines whether the collection lives in memory or on disk. The documentation points to a separate concepts page for the index type list, so the README alone will not tell you which to pick for your data.
WAL durability and the single-writer constraint
Two storage properties are stated explicitly, and they pull in opposite directions for some workloads. First, durability: the README says write-ahead logging guarantees persistence, with the claim that data is not lost even on process crash or power failure. That is a stronger statement than most embedded stores make, and it is the right one for an index that a user spent hours embedding. Second, concurrency: multiple processes can read the same collection simultaneously, but writes are single-process exclusive. Read that constraint carefully, because it eliminates a whole class of architectures. You cannot run two worker processes that both ingest into one collection. You cannot have a background indexer and a foreground writer sharing a file. The workaround is a single writer process that owns the collection and serves reads to others, which is a design you have to build yourself, and at that point you have reintroduced a small server. The honest reading is that zvec's concurrency model matches its intended deployment: one application process, one collection, many reads within that process. If your ingestion is naturally parallel, this is a friction point.
Where zvec is the wrong tool, and what to use instead
The clearest case against zvec is a shared index behind a network boundary. If several services, languages or machines need to query the same vectors, an embedded library forces you to either replicate the collection to each consumer or wrap it in your own service. A server-based vector database such as Milvus, Qdrant or Weaviate takes the opposite approach: the index is a long-running process with an HTTP or gRPC API, replication and sharding are the database's problem, and clients are thin. The trade is operational weight against architectural flexibility. Zvec moves the index into your process, which removes the network hop and the deployment, and in exchange you own the file lifecycle, the writer serialisation and the upgrade path. There is a second, less obvious alternative worth naming: a general-purpose embedded store with a vector extension, or a plain ANN library plus SQLite for the metadata. That combination can cover filtered vector search, but it pushes fusion between keyword and vector results into your application code, which is precisely the work zvec's hybrid query is designed to absorb. Choose zvec when the fusion and the local file are the point. Choose a server when sharing is the point.
Upgrades, prebuilt binaries and what Apache-2.0 leaves you to decide
Release cadence is visible from the tags: v0.8.0-beta on 2026-10-19, v0.8.0-beta2 on 2026-10-20 and v0.8.0 on 2026-10-21. v0.8.0 is a large release by the notes' own account, adding platform targets, built-in Chinese tokenization, cheaper index builds and faster distance computation and search. For an embedded library, a fast cadence cuts both ways. You get the index improvements without waiting, but every upgrade is a dependency bump inside your own binary, and the release notes show platform-level changes (Intel Mac and Windows ARM64 builds, DiskANN on Windows, Android and iOS) that alter what your build links against. The licence is Apache-2.0, which is permissive and includes an explicit patent grant, and the practical implication is that embedding it in a closed-source product is permitted. That is a statement about the licence text, not legal advice; if you are redistributing the prebuilt SDK binaries or modifying the C++ core, have your own counsel read the NOTICE and attribution requirements. The maintenance cost that matters most is not the licence. It is that you now own a native dependency with a fast release train and a single-writer storage file, and neither of those is something the library can absorb for you.
Editorial conclusion
Adopt zvec if your application is the only writer to its index and you want vector, sparse and full-text search without a separate service to deploy: the Python quickstart is a pip install, a CollectionSchema, and a create_and_open call on a local path. Do not adopt it if two processes must write the same collection at once, since the README states writes are single-process exclusive, or if you need a network endpoint that many clients share. Before committing, verify three things against your own data: which index type your collection uses, whether the disk-based path (DiskANN) is what you actually benchmarked, and how the WAL behaves on an unclean shutdown in your deployment target.
Frequently asked questions
What is Zvec?
An open-source in-process vector database with a native C++ backend, built to be embedded directly into an application rather than run as a separate service. It supports dense and sparse vectors, full-text search, hybrid search, write-ahead logging, and bindings for Python, Node.js, Go, Rust and Dart.
Can two processes write to the same Zvec collection?
No. Multiple processes can read the same collection simultaneously, but writes are single-process exclusive. That constraint is the main reason to choose it for a local or embedded application rather than for a service with several writers.
How do I install Zvec for Python?
Run pip install zvec, which the installation notes say requires 64-bit Python 3.10 to 3.14. Node.js, Rust and Dart packages are also published, with the Go bindings hosted in a separate repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/alibaba-zvec)Star history chart for your README
[](https://hysenlabs.com/projects/alibaba-zvec)Was this useful?