iOS local inference runs the file named inference_android, and the SDK floor appears twice
A unified cross-platform AI client supporting seamless transitions between standard cloud APIs and on-device, offline execution of custom and uncensored language models.
At a glance
- What is it?
- A Flutter chat client that runs quantised models on a phone through a hand-written plugin wrapping a C++ inference engine, and falls back to four cloud APIs. The build notes are unusually candid about what will break an app store update.
- Who is it for?
- Use this client if you want a chat app that keeps working without a network connection and runs a model you downloaded yourself, and if you are on Android or willing to sideload on iOS. Four things to know before you build it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
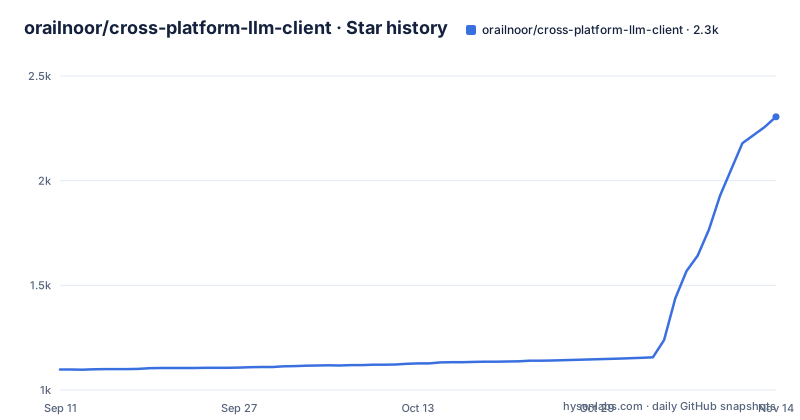
- orailnoor/cross-platform-llm-client2,305 ★ · +1,207
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| orailnoor/cross-platform-llm-client | 1.1k | 2.3k |
1,207 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
iOS local inference runs the file named for Android
Local inference is selected at compile time and there are only two implementation files for three platforms. Android maps to the real engine file. The web maps to a stub that is cloud only, with local inference described as coming later. iOS maps to the same file as Android, and the note explains that it is the full engine reached through the other graphics backend instead. So the claim in the opening paragraph, that local on-device inference is an Android feature, is narrower than the platform table, which gives iOS a yes for local inference and names its acceleration path, and narrower still than the fact that the iOS build literally reuses the Android implementation file. The interface exposes a flag so the user interface can hide the local model controls where they would not work, which is the right handling for a platform that cannot do it yet.
One release is tagged 1.0.3 and titled 1.0.4
The version history is two entries and they do not line up. The newer one is tagged 1.0.5 and titled with the app name and that same number. The older one is tagged 1.0.3 while its title says 1.0.4, so a version exists in the project's naming but not in its tags. Since Android upgrades depend on signing rather than versions, and iOS installs here are sideloaded from a zip rather than from a store, nothing in the delivery mechanism would have caught this. It matters for two reasons: anyone pinning a version to reproduce a bug has to know which of the two numbers is the installable one, and the next release skips nothing but leaves a gap in the tag sequence that will confuse a changelog. The most recent push to the repository is dated 2026-07-21, the same day as the newer release.
The Android floor is stated twice and the two values differ
The build prerequisites say the Android software development kit is required at version 26 or newer. The supported platforms table, in the same file, says the minimum is 28. There is no note reconciling them. The gap is one platform version, and in practice the effective floor is whatever the build configuration says, but the number a reader copies into a checklist depends on which section they read. It is the kind of inconsistency that survives because both values are plausible and because the project is developed on hardware that satisfies either. The table does add a useful detail that the prerequisites do not mention, which is that the offload path on Android relies on the instruction set extension for those processors rather than on a discrete GPU.
The signing key must never change and the build number must always climb
Three sentences in the Android section carry more operational weight than the rest of the file. Release builds require a stable signing key, configured by copying an example properties file and filling in the keystore values, and you are told to keep both the key and a backup of it. The reason is given plainly: the platform accepts an upgrade of an installed application only when the new package is signed with the same key. Then two instructions follow, one never to rotate that key between releases and one to keep increasing the build number for the per-processor packages. That combination means a lost key ends the update path for every existing install, and a re-run of a release cannot produce an installable upgrade. The build itself is split per processor architecture, which is what makes the per-package build number requirement matter. The two commands are short:
cp android/key.properties.example android/key.properties
flutter build apk --release --split-per-abi
Four cloud APIs become one, and one of them is already the first one
The cloud layer is a single service that normalises four request shapes into one interface, and the differences are named. One is the standard chat completions path. One is a messages API where the system instruction is a separate parameter rather than a message in the list. One takes content generation with images supplied inline as base64. And the fourth is described as an OpenAI-compatible endpoint, which means the first two lines of the adapter are doing all the work and the fourth is a configuration. Locally, the same client keeps chats, tasks and settings in an on-device database, and the claim is that nothing leaves the device unless you pick cloud mode. Credentials are described as living in that same store and going only to the provider they belong to.
Five phones at four steps, then a sixth phone at twenty
Two italic lines near the top carry the only performance claims in the file, and they do not describe the same run. The first says image generation was tested on five devices, naming a Snapdragon part in three of them, a MediaTek part in one and a Tensor part in one, at four steps. The second says a sample image was generated on a different phone entirely, a Pixel 6, at twenty steps. So the test matrix and the example are not the same hardware, not the same step count, and not even the same model of phone within the same product line. Read the first as a compatibility claim and the second as a quality setting, which is a reasonable thing to have written, but written as two adjacent lines they read as one result. The device tier logic elsewhere in the file, which picks a thread count from a tier, is the machinery these two lines are describing.
Five seconds idle, 180 seconds hard, and a fallback prompt builder
The local inference path is described as a five-step runtime sequence, and the first three are about the hardware rather than the model. It queries the graphics capability through a low-level interface to decide how many layers to offload, it picks a thread count from a device tier with four named levels, and it loads the quantised model while streaming progress. Token generation goes through a chat call with native support for four chat template families, and if those native templates fail the client falls back to building the prompt by hand, which is the kind of degradation that keeps a phone app usable against a model it does not recognise. On top of that sit two timeouts, an idle threshold of five seconds and a hard limit of 180, both justified as keeping the interface responsive on underpowered hardware.
A local app with a hosted web presence and two stray screenshots
The repository root tells you this is a normal Flutter application with a few extras. There is the usual project metadata and the platform directories, plus an assets folder and a tests folder. Then there is a Firebase configuration file and a Firebase JSON, which is where the push messaging integration comes from, and a submodule file and a local plugins directory, which is where the inference plugin lives. At the top of the README, the first link goes to a hosted web build on a subdomain named after the account, so the same code is also running as a web application on someone else's domain. The image files at the root are a project screenshot under a sensible name and a second one under a camera default filename, which is the kind of thing that ends up in a repository and stays there.
Editorial conclusion
Use this client if you want a chat app that keeps working without a network connection and runs a model you downloaded yourself, and if you are on Android or willing to sideload on iOS. Four things to know before you build it. The web target is cloud only, so a browser install is a different product with a different promise. The iOS path reuses a file named for Android, which is a naming problem rather than a functional one but will confuse anyone reading the tree. The Android minimum version is stated two different ways in the same file. And the release procedure depends on a signing key that must never change and a build number that must always increase, which means releases cannot be redone.
Frequently asked questions
What is the minimum Android version for cross-platform-llm-client?
The file states it twice and the values differ. The build prerequisites say the Android SDK at version 26 or newer, and the supported platforms table says a minimum of 28, with the offload path using the processor instruction set extension.
Does the iOS build of PrivateLM run a local model?
The platform table says yes, with acceleration through the other graphics backend, and the compile-time mapping points iOS at the same implementation file as Android. The opening paragraph only claims local inference for Android.
How does the client normalise the cloud providers?
One service maps four request shapes onto a single interface: a standard chat completions path, a messages API with a separate system parameter, a content generation call that takes images inline as base64, and one provider that is simply an OpenAI-compatible endpoint.
What happens to a release if the Android signing key changes?
Existing installs cannot be upgraded, because the platform only accepts an upgrade signed with the same key as the installed package. The build notes say never to rotate the key between releases and to keep increasing the per-architecture build number.
Can I run a local model on the web build?
No. The web target maps to a stub implementation described as cloud only, with local inference coming later, and the platform table marks web local inference as unsupported while cloud access works.
How is the iOS app installed?
By sideloading. A zip named for iOS is downloaded from the releases page, extracted, and the package inside is installed with one of three sideloading tools. Phone support is described as experimental, with tablets recommended because of the memory local models need.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Run local LLMs on multiple Android, iOS phonesHacker News · Nov 6, 2026 · 2 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/orailnoor-cross-platform-llm-client)Star history chart for your README
[](https://hysenlabs.com/projects/orailnoor-cross-platform-llm-client)Was this useful?