Beta, a pinned Postgres commit, and one status marker
OrioleDB – building a modern cloud-native storage engine (... and solving some PostgreSQL wicked problems)
At a glance
- What is it?
- OrioleDB replaces what PostgreSQL does below the table access method, which is why it is a patched-server project rather than a drop-in extension. The page is unusually clear about its own limits: public beta, not recommended for production, and a build that refuses to compile unless your PostgreSQL is at the commit recorded in a file in the repository. The interesting detail is one word, planned, attached to the feature the design section implies is already there.
- Who is it for?
- OrioleDB is interesting if you are willing to run a patched server, because the ideas it claims, undo instead of vacuum, no buffer mapping, copy-on-write checkpoints and a row-level write-ahead log, are exactly the ones that are hard to retrofit. Decide on two things first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
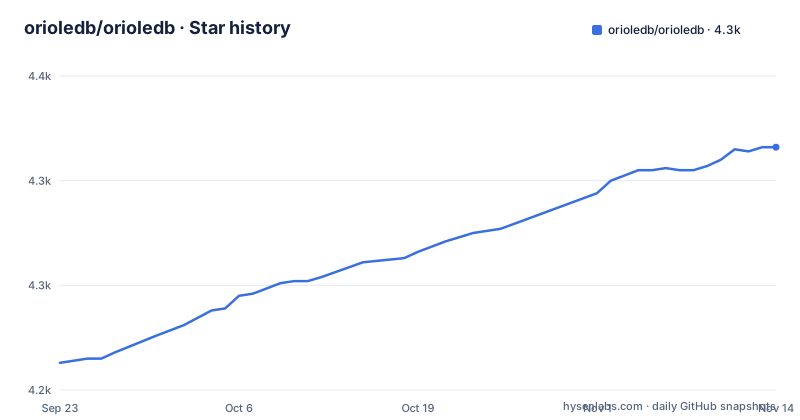
Star history
- orioledb/orioledb4,316 ★ · +103
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| orioledb/orioledb | 4.2k | 4.3k |
103 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Status section says not for production
There is a short Status section and it does not hedge. OrioleDB has public beta status, is recommended for experiments, testing and benchmarking, and is not recommended for production usage. Anyone interested in the production benefits is invited to make contact at an address on the project's own domain.
The three newest release entries are v1.10.1, beta19 and beta18, dated 2026-11-02, 2026-10-01 and 2026-09-23.
What that means in practice is that the compatibility promise comes from somewhere other than the tags. Any question about whether a given beta works with a given PostgreSQL version has to be answered by asking, or by reading the documentation directory, which the README points at for an introduction, a getting started page and an architecture overview.
For a storage engine, that is a normal place to be, and saying so plainly is better than the alternative.
It replaces what PostgreSQL does under the table access method
OrioleDB is a PostgreSQL extension built on the table access method framework, which is the interface a storage engine implements to be used for tables. That single design choice explains most of what follows.
Three motivations are given. The first is hardware, described as avoiding legacy CPU bottlenecks on servers with dozens and hundreds of cores and making use of SSD and NVRAM. The second is maintenance: an undo log plus page merges remove the need for dedicated garbage collection, and default 64-bit transaction identifiers remove the transaction id wraparound problem. The third is distribution, through a row-level write-ahead log with parallel apply, described as optimized for raft consensus replication.
The three differentiations then go into mechanism. No buffer mapping, where in-memory pages hold direct links to storage pages and reading does not involve atomic operations, so page reads are lock-less. MVCC based on an undo log, where old row versions are evicted into undo chains and page-level undo records let space be reclaimed quickly, which together with page merges removes most bloat and makes dedicated vacuuming unnecessary. And copy-on-write checkpoints, which give a structurally consistent snapshot at every moment, suit SSDs, and make row-level write-ahead logging practical.
So the claims are specific and testable rather than aspirational, which is what you want from a storage engine at beta stage.
One word tells you which part has not shipped
The active-active multimaster story appears twice and is stated differently each time.
In the motivation list, the third point says the row-level write-ahead log is optimized for raft consensus-based replication, allowing the implementation of active-active multimaster. In the differentiation list, the same feature is described as row-level logging being easy to parallelize, marked as done, easy to compact, and suitable for active-active multimaster, marked as planned.
That parenthetical is doing a lot of work. Parallel apply is described as something that exists; the multimaster capability is described as something the architecture suits but has not delivered. Since active-active replication is usually the reason an organisation considers a storage engine at all, that single word is the difference between a beta you can test and a roadmap item.
Everything else in the differentiations list is written in the present tense without qualification, so a reader who wants to know what is real has one marker to look for and one sentence to check.
The build refuses to run against any other PostgreSQL
Building from source is the supported path for development, and it starts with a constraint rather than a command: a PostgreSQL build with the project's extensibility patches, checked out at the exact commit listed in a file called `.pgtags`. The page states that the build verifies this and refuses to compile against any other patchset.
The file holds one commit per major version, and the page prints both as an example:
17: 7050019fd74d0d841040edc49ee1e16364a8b589
16: e5ef9e6a6d21f8e69e1d4bddcd4cdb83f054ca0b
The surrounding commands warn against using those values, saying to substitute what is in `.pgtags` and not to copy-paste, because it moves. The example extracts the value for the major version with awk rather than hard coding it.
The failure path is documented too, which is rarer than it should be. If the configured server is at the wrong commit, the build prints:
Wrong orioledb patchset version: expected <hash>, got <hash>
Rebuild and install patched orioledb/postgres using commit '<hash>'
After the build, one configuration line is required before use, `shared_preload_libraries = 'orioledb.so'`, and it needs a server restart. The other stated prerequisites are the libzstd development package and python 3.5 or newer with testgres for the tests.
Docker is the easy route and it opens with a locale constraint
Container images are provided for two architectures, amd64 and arm64v8, built on Alpine Linux, and the tag in the example carries the PostgreSQL major version:
docker pull orioledb/orioledb:latest-pg17The run command is the ordinary one for a PostgreSQL image, with one addition and one warning:
# !Don't forget to set default locale to C, POSIX or use icu-locale
docker run --name some-postgres -e POSTGRES_PASSWORD=... -e POSTGRES_INITDB_ARGS="--locale=C" -d -p5432:5432 orioledb/orioledb:latest-pg17
The locale is not optional here: the database is initialised with `--locale=C`, and the alternative named is an ICU locale.
That connects to a short Collations section, which states that OrioleDB tables support ICU, C and POSIX collations. So collation support is a documented area with a documented default, and the container route bakes the safe default in rather than leaving it to the operator.
The engine links curl and OpenSSL, and the test stack is a cloud toolkit
The extension's own build file links four libraries:
SHLIB_LINK += -lzstd -lcurl -lssl -lcryptoA storage engine that links an HTTP client and TLS is not only reading local pages, which is consistent with the S3 loader that sits in the repository root. It also explains the shape of the Python test requirements, which are a cloud and web stack rather than a database one.
That file pins 36 packages with exact versions. Among them are an AWS SDK with its transfer manager, a mocking library for those services, a web framework with cross-origin support, a pure-Python PostgreSQL driver alongside the C one, the test harness named in the README, a diff library, a port-picking helper, an XML to dictionary converter and a response-mocking package.
The pairing is coherent: a storage engine with an S3 loader needs something that can stand in for S3 during tests, and a mock library is the lightest way to get it. It is also a much larger surface than the two prerequisites the README names, which are libzstd and python 3.5 with testgres.
Generated headers and a make flags file you supply yourself
The build has a generated-file pipeline, and it lists the outputs in EXTRA_CLEAN so make clean removes them:
EXTRA_CLEAN = include/utils/stopevents_defs.h \
			  include/utils/stopevents_data.h
The tree explains where those come from: a stopevents file and a generator script named after it sit at the root, alongside a second generator for typedefs. So a meaningful part of the C headers is produced by a script at build time rather than edited by hand, which is worth knowing before you go looking for the definitions.
The other build-time decision is local. The Makefile opens by including a make flags file if one exists and then exporting, so anything set there reaches sub-makes as an environment variable:
-include make.flagsThe repository ships an example file rather than the real one, which means the flags your build used are yours and are not recorded in the repository. That is the right default for machine-specific settings, and it is also one more thing to write down when a colleague needs the same build.
Around that sit the other things a project of this size carries: a Valgrind suppression file, a Python formatter configuration, a CI directory, a docker directory, a performance directory and a documentation directory the README points at by name.
Editorial conclusion
OrioleDB is interesting if you are willing to run a patched server, because the ideas it claims, undo instead of vacuum, no buffer mapping, copy-on-write checkpoints and a row-level write-ahead log, are exactly the ones that are hard to retrofit. Decide on two things first. Whether you can operate a PostgreSQL build that is not a stock release, since the build checks the commit and refuses to proceed, and whether public beta is acceptable for your data, because the page recommends it for experiments and explicitly not for production. On the licence side there is little to resolve: it is dual licensed, contributions land under both terms, and a separate patent grant exists for anyone who needs one.
Frequently asked questions
What is oriole db?
OrioleDB is a storage engine for PostgreSQL, delivered as an extension built on the table access method framework. It states three differentiations: no buffer mapping with lock-less page reads, MVCC based on an undo log with page merges instead of vacuum, and copy-on-write checkpoints with a row-level write-ahead log.
what is postgres with orioledb
It is PostgreSQL with a different table access method. The extension is loaded by adding shared_preload_libraries = 'orioledb.so' to the server configuration and restarting, and it must be built against a patched PostgreSQL at the exact commit recorded in the repository's .pgtags file.
Is OrioleDB ready for production?
The project states public beta status, recommends it for experiments, testing and benchmarking, and says it is not recommended for production usage. The newest releases are v1.10.1, beta19 and beta18, and a contact address is given for production enquiries.
What licence is OrioleDB under?
Dual licensed, with your choice of the Apache License 2.0 or the PostgreSQL License, under the SPDX identifier Apache-2.0 OR PostgreSQL. All contributions are made under both, and a separate patent grant is provided by Supabase and described in PATENTS.txt.
Does OrioleDB support collation settings?
OrioleDB tables support ICU, C and POSIX collations. The container instructions tell you to initialise the database with the C locale, and name icu-locale as the alternative.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/orioledb-orioledb)Star history chart for your README
[](https://hysenlabs.com/projects/orioledb-orioledb)Was this useful?