Oumi's install paths diverge on ARM64, uv, and conda
Easily fine-tune, evaluate and deploy Qwen, Gemma, or any open weight LLM!
At a glance
- What is it?
- Oumi wraps data preparation, training, evaluation, and deployment for open-weight models. Its packaging says more about what you will hit than its news list does: the container drops the GPU extra on ARM64, the Transformers band is set as a uv override, and the default test run skips every GPU marker.
- Who is it for?
- Oumi fits if you want one process for SFT, DPO, GRPO, judging, and serving across the Llama, Gemma, Qwen, DeepSeek, GLM, and Phi families, and you are willing to work inside packaging that still calls itself alpha. It does not fit if you need a stable dependency contract, a Python newer than 3.14, or GPU acceleration on ARM64 hardware.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
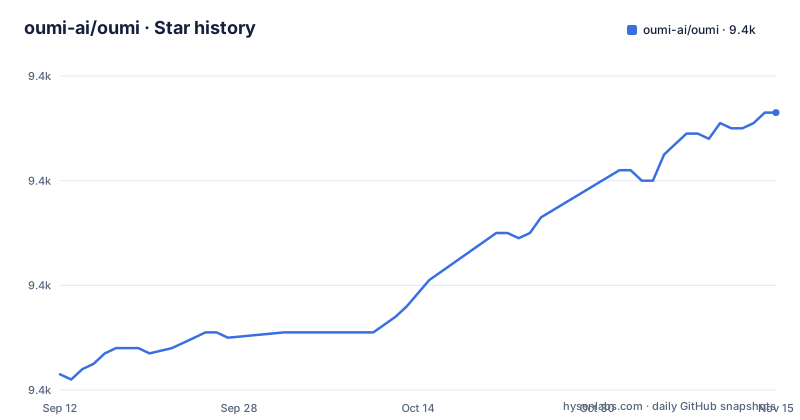
- oumi-ai/oumi9,433 ★ · +50
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| oumi-ai/oumi | 9.4k | 9.4k |
50 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The index says alpha while tagged releases keep arriving
The packaging metadata and the release history disagree about how finished this is. pyproject.toml declares Development Status :: 3 - Alpha and Intended Audience :: Developers, yet three tagged releases landed in nine months: v0.7 on 2026-01-29, v0.8 on 2026-05-07, and v0.9 on 2026-09-16, with the default branch last pushed on 2026-10-30. Nothing in the file says what would move it out of alpha, and the classifier is the only stability signal an index will show you, so anything gating on that field treats this the same as an abandoned experiment. The version itself is declared dynamic and handed to setuptools_scm with default configuration, which means the number on a built artifact is read from repository tags rather than typed into the file. A tree with no tags behind it has no version to stamp, and there is no fallback literal in pyproject.toml to catch that case.
The Transformers band only binds when uv is the installer
Dependency resolution is where the stack shows its strain. The uv section carries a single override and a pre-release policy:
prerelease = "if-necessary-or-explicit"
override-dependencies = ["transformers>=5.5,<5.17"]
A comment above them explains the first line: Oumi uses an Omegaconf dev release because uv refuses pre-releases by default, and if-necessary-or-explicit permits one when a package is pinned explicitly or when nothing stable satisfies the requirement, with opentelemetry-semantic-conventions named as a case that only ships beta builds on PyPI. The Transformers band is narrow, and the project has already crossed a major version boundary, upgrading to Transformers v5 in March 2026 after pairing with Transformers v4.56 in v0.4.1. The catch is that override-dependencies is a uv setting, so other installers do not read it.
ARM64 images install the CPU-only build and say nothing about it
The Dockerfile splits the base image by architecture before a line of Python is written:
FROM --platform=linux/amd64 pytorch/pytorch:${PYTORCH_VERSION}-cuda${CUDA_VERSION}-cudnn9-runtime AS base-amd64
FROM --platform=linux/arm64 python:${PYTHON_VERSION}-slim-bookworm AS base-arm64
The dependency step then branches on TARGETARCH, setting OUMI_EXTRAS to an empty string on arm64 and to [gpu] everywhere else, with build-essential added to the apt list on arm64 only. Defaults are PyTorch 2.8.0, CUDA 12.8, and Python 3.11, and the CUDA minor version is rewritten into a short string for the PyTorch wheel index. Build on an ARM64 host, such as an Apple Silicon machine or an ARM server, and you get a CPU-only install, so a recipe that assumes an accelerator has to be rewritten rather than merely retried.
The default test filter excludes every GPU and end-to-end marker
The Makefile carries a single variable that decides what a routine test run touches:
UNIT_TEST_MARKERS := not e2e and not e2e_eternal and not single_gpu and not multi_gpuA comment states that it mirrors the unit-test workflow in .github/workflows/pretest.yaml, and the README badges point at that file and at a separate gpu_tests.yaml, so GPU coverage lives in a different job from the one this filter copies. The default goal is help, and the target list it prints includes test and coverage. Practically, a green local run proves the CPU-only paths and nothing else: single_gpu and multi_gpu tests need hardware the filter assumes you lack. Adding a marker to that line changes what your green run means, so treat the variable as part of the contract when you read a passing suite.
The host range stops at 3.14 while the image runs 3.11
Python support is stated once and pinned twice:
requires-python = ">=3.10,<3.15"Classifiers enumerate 3.10, 3.11, 3.12, 3.13, and 3.14, and the upper bound is a hard exclusion rather than a preference, so an environment on 3.15 is refused by the installer instead of being allowed to fail later. The Dockerfile defaults PYTHON_VERSION to 3.11 for the ARM64 base image, meaning a container can run a different interpreter than the newest one the package claims to support. The two ranges also moved at different speeds: v0.6.0 added Python 3.13 support in December 2025, and v0.7 added Python 3.14 alongside PyTorch 2.9 in January 2026, while the container's base default is 3.11. If your pipeline pins a 3.11 interpreter for the image and a 3.13 interpreter for the training host, you are running two supported combinations at once.
Every local target routes through a conda env named oumi
The Makefile presumes one environment manager and one name:
CONDA_ENV := oumi
CONDA_RUN := conda run --no-capture-output -n $(CONDA_ENV)
CONDA_INSTALL_PATH := $(HOME)/miniconda3
CONDA_ACTIVE checks conda info --envs for an active environment, and CONDA_RUN wraps commands in conda run -n oumi. The help list names setup, upgrade, check, torchfix, ty, format, test, coverage, docs, and docs-serve. The help target is the default goal, so the target list is the project's own documentation of what exists. Two costs come with that design: a plain virtualenv or a minimal container without conda has to reconstruct the commands, and CONDA_INSTALL_PATH assumes miniconda3 lives directly under the home directory. The repository root does offer non-conda routes, an install.sh and a Dockerfile, but the local development loop the Makefile describes has no equivalent for them.
Jinja templates are matched only at the package root
One stanza decides what travels inside the Python package:
[tool.setuptools.package-data]
oumi = ["LICENSE", "README.md", "*.jinja"]
The glob *.jinja is written against the oumi package directory itself. The same stanza also places the LICENSE and README.md inside the package directory rather than only at the distribution root. The repository root keeps configs/, data/, notebooks/, platform/, docs/, scripts/, and tests/ as siblings of src/, and this stanza declares data for the package alone, so anything meant to accompany an installed copy has to be located inside it.
oumi deploy and oumi-mcp appear only as release notes
The command surface has widened faster than its documentation. The v0.8 entry in May 2026 added a `oumi deploy` CLI for dedicated inference endpoints, an `oumi-mcp` MCP server for Claude and Cursor integration, and batch API support across Anthropic, Fireworks, and Together, and a March 2026 entry added deploying to endpoints on Fireworks and Parasail. v0.6.0 in December 2025 introduced `oumi analyze`, v0.7 in January 2026 added Fireworks and OpenRouter as inference engines plus rule-based evaluation judges, and v0.9 in September 2026 added tool-calling SFT and DPO, executable tool environments, GRPO over any Oumi environment with verl, and a multi-criteria `RubricJudge`. Each of those is a surface with its own arguments, its own credentials, and its own failure modes.
Editorial conclusion
Oumi fits if you want one process for SFT, DPO, GRPO, judging, and serving across the Llama, Gemma, Qwen, DeepSeek, GLM, and Phi families, and you are willing to work inside packaging that still calls itself alpha. It does not fit if you need a stable dependency contract, a Python newer than 3.14, or GPU acceleration on ARM64 hardware. Before you start, open the recipe for your model under configs/recipes and confirm which Transformers build your environment resolved.
Frequently asked questions
Is the Oumi app safe?
There is no app in this repository. What ships is an Apache-2.0 licensed Python package, a Dockerfile, an install.sh, and a platform/ directory, with SECURITY.md and CODE_OF_CONDUCT.md at the root.
How does Oumi work?
Oumi is a fully open-source platform covering the lifecycle of a foundation model, from data preparation and training to evaluation and deployment, whether on a laptop, a cluster, or in production. It names SFT, LoRA, QLoRA, DPO, and GRPO for models from 10M to 400B+ parameters, synthetic data curation with LLM judges, vLLM and SGLang for serving, and tool environments of the database, HTTP endpoint, lookup, and simulated kinds.
What is the meaning of the name Oumi?
The site linked in the badges is oumi.ai. In packaging the name appears in three places: the distribution name, the import package, and the container user, which is created with groupadd -r oumi and useradd -r -g oumi -m -s /bin/bash oumi.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oumi-ai-oumi)Star history chart for your README
[](https://hysenlabs.com/projects/oumi-ai-oumi)Was this useful?