amazon-scraper: one command, five CSV columns, no license file
Free Trial Amazon Scraper API for extracting search, product, offer listing, reviews, question and answers, best sellers and sellers data.
At a glance
- What is it?
- The free half of this repository takes the URL of an Amazon department page, runs it through Selenium, and writes a CSV with five columns. The other half is a sales page for a paid API with seven named data sources, and the two are joined by a note telling you to switch over when your project gets bigger. There is also no license file anywhere in the tree.
- Who is it for?
- Use the free tool if your task is genuinely one page of products and you want a spreadsheet to look at, because the scope is narrow, the output is defined, and out of stock items are reported rather than silently dropped. Three things to settle first.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
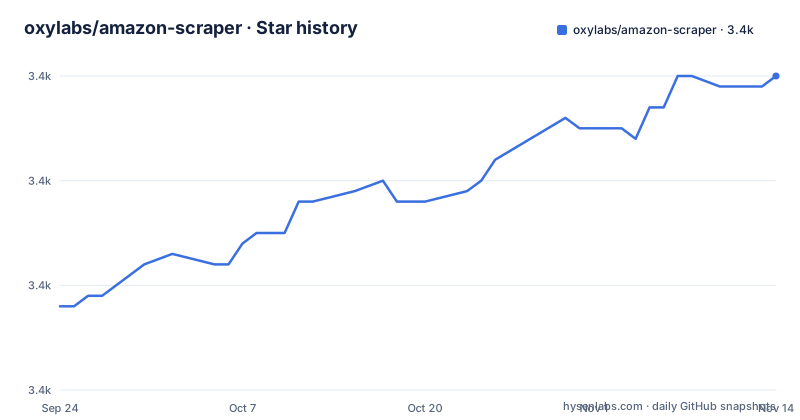
- oxylabs/amazon-scraper3,420 ★ · +22
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| oxylabs/amazon-scraper | 3.4k | 3.4k |
22 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The top of the file is an affiliate link, and the free tool ends in a pitch
The first thing in the repository is a link to the vendor's product page, and it carries campaign parameters: a source and medium marking it as coming from a repository, a campaign name, and a transaction identifier. There is also a group identifier in a second copy of the link further down.
That matters for how you read the rest. The document is arranged as a tutorial that teaches the free tool and then hands you to the paid one. The Notes section says that if the code does not work, or if your project is of bigger scale, you should refer to the second part of the tutorial, where it shows how to scrape public data with the vendor's scraper API.
The paid half is presented as an all-in-one solution designed to handle Amazon's own automated request management systems through adapting infrastructure that automates proxy rotation, web access management and parsing, with a link to claim a free trial.
So the repository is doing two jobs at once: it is a working example and it is the top of a sales funnel. Neither is hidden, and both are worth naming before you decide how much to build on the free path.
The install target pins the package manager to one exact version
Installation is one make target, and the first thing it does is install the build tool itself:
install:
	pip install poetry==1.8.2
	poetry install
Poetry is pinned to an exact patch version rather than a range, so the toolchain is fixed at that release for anyone who follows the instruction. That is deliberate reproducibility for a tutorial, and it is also a toolchain from a specific era that the rest of the dependency list has moved past.
The interpreter requirement is stated twice. The tutorial says you need Python 3.11 installed in your system, and the project file declares the same floor as a caret range on 3.11. A version file at the root of the repository pins the interpreter as well, which is what makes a checkout reproducible for an editor or a version manager.
The run target guards its own input. If the URL variable is empty it prints a usage line telling you to pass a URL and exits with a failure code, and otherwise it invokes the package as a module with the URL passed as an argument. That guard is why the tutorial spends a paragraph on quoting.
The entire tool is one command, and the output is five columns
The input is a URL you copy yourself. Open Amazon, pick a department, and copy the address of the listing page; the tutorial uses the computers and accessories department as its worked example. That URL is the only input the free tool takes.
make scrape URL="<amazon_department_page_url>"The output is a single file named amazon_products.csv, written into the current directory, with five columns. Four are identity and location: the product title, the URL of the product's own page, the unique ASIN code, and the URL of the image. The fifth is the price.
The price field has a documented empty case. It can be blank when the product is out of stock, and the tool also prints a message when it meets one during the run. So an out of stock item shows up as a row with no price rather than disappearing, which is the behaviour you want when you are counting a catalogue and the behaviour you do not want if you assume every row is purchasable.
There is no pagination control and no scheduling in the free path. One department page per run is the whole contract.
Quoting matters because the example URL is full of ampersands
The tutorial includes one instruction about the command line that is easy to skim and expensive to ignore: surround the URL with quotation marks, otherwise the tool might have trouble parsing it.
The worked example explains why. The department URL it prints is not a clean path. It carries a search identifier, a numeric browse node, a percent-encoded filter value with encoded colons and commas, a reference token, and several raw ampersands separating the parameters. Any one of those ampersands, left unquoted, ends the argument at the shell and turns the rest of the filter into a separate thing the program never sees.
This is the ordinary hazard of passing a filtered search URL through a shell and then through make's own variable expansion, and it is worth understanding rather than memorising. The URL is not an identifier you invent; it is whatever the browser shows after you navigate to a department listing, which means its shape is decided by Amazon's own front end and can change without notice.
So the tool inherits the fragility of its input. A department listing that loads correctly in a browser produces a URL that has to survive two layers of shell handling before the scraper sees it.
The paid path is a different architecture with seven named sources
The second half of the document describes a hosted service, and its data model is a list of named sources rather than a URL you supply. Seven are offered. One accepts any Amazon URL and returns whatever the URL implies. The others take a specific target: a taxonomy node for best sellers, an ASIN for pricing, an ASIN for the product page, an ASIN for questions and answers, a search term for search results, and a seller for seller information. Six of the seven return structured data; the URL-based one depends on what you gave it.
That source value is one of six query parameters for the URL mode, and the parameter table is where the interesting defaults are. The source and the URL are required. A device type parameter defaults to desktop. A render flag turns on JavaScript rendering. A callback parameter takes a URL for a push delivery endpoint. And a parse flag, defaulting to false, returns structured data when the submitted URL matches a page type the service knows how to parse.
The URL mode makes a promise worth noting: parameters are not stripped and URLs are not altered in any way. For a service that exists to normalise messy pages, declining to normalise the input is a deliberate boundary between what the caller asked for and what the service decided.
The implementation drives a real browser and intercepts its requests
The dependency list explains how the free tool works, and it is not a request library.
Selenium is there, so a browser is launched. A web driver manager is there, so the browser binary is fetched for you. And an intercepting driver package is there, so the traffic that browser generates can be observed rather than only the rendered page. Those three together are a browser-automation stack with network visibility.
The rest is ordinary data plumbing: a dataframe library for the CSV, a command line library for the argument, a validation library and a settings library for configuration, which suggests the scrape is described by typed settings objects rather than loose arguments.
One entry in the list is worth noting on its own. The signalling library is pinned below a specific version with an exact upper bound, and it is written without spaces around the equals sign while every other entry has them, so it was added by hand and differently from the rest. That is the shape of a compatibility workaround rather than a normal requirement.
The result is a heavier footprint than a script that fetches a page would need, and in exchange it handles pages that only exist after scripts have run.
Four lint tools, a src layout, screenshots in the root, and no license
The development setup is thorough in a way that the tutorial never mentions. There is a Flake8 configuration, a pre-commit configuration, a mypy section with a long list of strictness flags including incomplete definitions and unused config warnings, and an import sorter configured against the Black profile with two blank lines after imports and one between types.
Four tools covering the same files is more than most tutorials carry, and it is consistent with a project that wants the sample to look like production code.
The layout is a src directory with the package inside it, named with underscores while the project is named with a hyphen, which is the standard way to keep an importable package and a distribution name distinct.
The screenshots are committed at the repository root, and their filenames contain spaces and start with capitals, which means a shell command touching them needs quoting. Small thing, and it is the sort of thing that breaks a script on a fresh checkout.
The one real gap is licensing. GitHub records no license identifier for this repository, and there is no license file in the tree. Nothing in the project states what you may do with the code, which is worth resolving with the authors before you copy any of it into something you intend to maintain.
Editorial conclusion
Use the free tool if your task is genuinely one page of products and you want a spreadsheet to look at, because the scope is narrow, the output is defined, and out of stock items are reported rather than silently dropped. Three things to settle first. There is no license, so nothing in the tree tells you what you are allowed to do with the code, and that matters more than usual for a repository whose first action is installing packages into your environment. The second half of the file is a commercial pitch with affiliate tracking on its own links, so evaluate the tool on what it does rather than on how the page is arranged. And the paid path is a different architecture rather than a scaled version of the same one, since it replaces a local browser with a hosted service that handles request routing on their side.
Frequently asked questions
What does the amazon-scraper tool actually scrape?
One Amazon department page at a time. You copy the URL of a department listing from your browser and pass it to the make scrape command, and the tool writes a CSV of the products listed on that page.
Which columns does the amazon-scraper CSV contain?
Five: title, url, asin_code, image_url and price. The price field can be empty when a product is out of stock, and the tool prints a message when it encounters one during the run.
How do I install amazon-scraper?
Run make install, which installs poetry pinned to version 1.8.2 and then runs poetry install. The project declares a Python 3.11 floor, and a version file at the repository root pins the interpreter.
What license does oxylabs/amazon-scraper use?
None is stated. The repository records no license identifier and the tree contains no license file, so the terms for reuse are not written down anywhere in the project.
Does the amazon-scraper README say whether scraping Amazon is legal?
No. It says it retrieves publicly available data, and it describes a paid service that handles Amazon's automated request management systems, but it takes no position on the legal question.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oxylabs-amazon-scraper)Star history chart for your README
[](https://hysenlabs.com/projects/oxylabs-amazon-scraper)Was this useful?