Oxylabs AI Studio Python SDK: five apps, one API key, and an archived repository
Structured data gathering from any website using AI-powered scraper, crawler, and browser automation. Scraping and crawling with natural language prompts. Equip your LLM agents with fresh data. AI Studio python SDK for intelligent web data gathering.
At a glance
- What is it?
- A small Python client for the Oxylabs AI Studio services, wrapping crawl, scrape, browser agent, search and map behind one class each. Output formats decide whether you need a JSON schema, JavaScript rendering is a flag that quietly becomes a string on one endpoint, and search reroutes itself to an instant endpoint under a threshold. The repository is archived, with one release published and a manifest version three patches ahead of it.
- Who is it for?
- Oxylabs AI Studio SDK suits a Python developer who already has an API key and wants the five extraction endpoints behind one import each, with a schema helper for the structured formats and a credit ceiling per call. It does not suit a team starting a new integration, because the repository is archived and the single published release is older than the version in its own manifest, so a fresh project should check whether the service and its SDK are still the maintained path.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- No. The owners have archived the repository on GitHub, so it is read-only and no longer receives changes.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on October 6, 2026, and from our analysis. They are not legal advice.
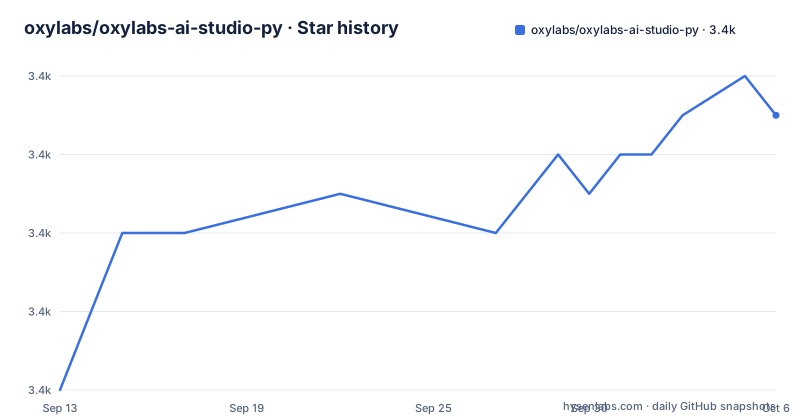
Star history
- oxylabs/oxylabs-ai-studio-py3,397 ★ · +7
| Repository | 2026-09-13 | 2026-10-06 |
|---|---|---|
| oxylabs/oxylabs-ai-studio-py | 3.4k | 3.4k |
7 Stars in the last 23 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
An archived repository, one release, and a manifest three patches ahead
The repository state deserves stating before the API does. It is marked archived, and the most recent commit on the default branch is dated 21 August 2026. The published release history contains a single entry, version 0.2.19 from November 2025, while the project manifest in the same repository declares version 0.2.22. So the version you install from the package index and the version the source tree describes are not the same number, and the repository is not the place where changes are still landing. The licence is MIT and the project points at a hosted service as its home, since this is a client for someone else's API rather than a tool you run yourself. Everything the SDK does happens on that service, with your key.
Five apps, one class each, and an API key in the constructor
The SDK is organised as five classes, each in its own module under a package named for the apps, and each takes the API key when you construct it. Crawl takes a site and a natural language prompt and walks it. Scrape takes a single URL. The browser agent takes a URL and a prompt and drives a page before capturing it. Search takes a query. Map takes a site and returns a picture of it. Map is also the endpoint with the widest parameter set in the documented examples, combining a crawl depth limit, a result limit, a list of search keywords to steer the crawl, a flag to include the site's sitemap, a credit ceiling, and two booleans that decide whether the crawl may leave the starting host: one for subdomains and one for other domains entirely. Construction looks the same in every case:
from oxylabs_ai_studio.apps.ai_crawler import AiCrawler

crawler = AiCrawler(api_key="<API_KEY>")
The stated requirements are Python 3.10 or newer and an API key, and installation is a single pip command for the package name. Results come back on a data attribute of the returned object rather than as a bare value, which is the one convention worth internalising before writing the calling code.
The output format decides whether you owe it a schema
Every endpoint takes an output format, and the set of allowed values differs by endpoint: crawl offers json, markdown, csv and toon; scrape adds a screenshot option; the browser agent adds html as well. The rule underneath is consistent. If the format is json, csv or toon, a schema is required, and the schema is a JSON schema describing the fields you want back. Markdown and screenshot need nothing. That makes the structured path two-step: describe what you want in a prompt, ask the SDK to turn it into a schema, then pass that schema with the scrape or crawl call. The helper is a method on the client itself, taking the same kind of natural language sentence the rest of the SDK uses.
JavaScript rendering is off everywhere, and a string only on one endpoint
A rendering flag appears on crawl, scrape, search and map, and its default is False in all four cases, which means the fast path is assumed and pages that build their content in the browser come back empty. The scraper is the exception that matters: its flag accepts either a boolean or the string auto, where auto asks the service to detect whether rendering is needed. The other endpoints do not document that option. The scraper also takes a list of browser instructions, actions to run before the capture, such as clicking, typing and waiting, but that list requires rendering to be switched on, and its format follows the browser instruction format of the vendor's separate web scraper API.
Search quietly switches endpoints when you ask for less
The search endpoint has a threshold behaviour that is worth knowing before you benchmark it. A normal search takes a limit that defaults to ten and tops out at fifty, and a flag that decides whether the results include page content, defaulting to on. The separate instant search takes a limit capped at ten and returns immediately. The automatic part: when the limit is ten or less and content retrieval is switched off, the ordinary search call does not poll, it uses the instant endpoint instead. The location parameter differs between the two as well, documented in one place as a two letter code, a country name or coordinates, and in the instant path as Google's canonical location name. So a request that looks like a normal search can travel a different route depending on two booleans and an integer.
Location, user agent, and a ceiling on credits
Three parameters show up across the endpoints and are the ones that shape a bill. A location parameter takes a two letter country code or a country name and points the request at a proxy in that place, with the list of accepted values documented on the vendor's developer site and linked from each endpoint. A user agent parameter on the scraper sets the request header, documented on the same site. A max credits parameter, optional, appears on crawl and map and caps what a single call can spend, which is the mechanism for keeping one expensive request from consuming a month of allowance. The scraper also has an option that trims output to the main page content, on by default, which produces cleaner and smaller markdown when you only need the article body.
A uv lockfile, a hatchling build, strict typing and a wide lint rule set
The packaging tells you the project was set up with current tooling. The manifest requires Python 3.10 or newer, builds with hatchling, and declares five runtime dependencies: an async HTTP client, the validation library and its settings companion, a dotenv loader, and a retry library. A separate development group adds a type checker, a linter and the package upload tool. The type checker runs in strict mode with missing imports ignored, and the linter targets Python 3.12 with a broad rule selection covering style, bug patterns, comprehension simplification, import sorting, naming, return style, upgrade suggestions and the bandit security checks, with one exception carved out for bare excepts. The repository root carries a uv lockfile, a lowercase makefile, a guide for agentic coding, and eleven example scripts covering every endpoint. Those examples are where the parameter combinations live that the documentation does not spell out: one pair differs only by whether content comes back with the results, another generates its schema before scraping, and two of them pass a Pydantic model rather than a plain dictionary, which is the practical reason the validation library is a runtime dependency instead of a development one.
Editorial conclusion
Oxylabs AI Studio SDK suits a Python developer who already has an API key and wants the five extraction endpoints behind one import each, with a schema helper for the structured formats and a credit ceiling per call. It does not suit a team starting a new integration, because the repository is archived and the single published release is older than the version in its own manifest, so a fresh project should check whether the service and its SDK are still the maintained path. Three things to verify before writing code against it: whether your output format forces a schema, since json, csv and toon all require one and markdown does not; whether your crawl needs JavaScript rendering, because the default is off everywhere and the scraper is the only endpoint that accepts an automatic detection mode; and how a search call behaves at small limits, because below ten results with content retrieval disabled it silently switches to a different endpoint that returns without polling.
Frequently asked questions
How do I install the Oxylabs AI Studio Python SDK?
Install the package with pip install oxylabs-ai-studio. You need Python 3.10 or newer and an API key, and every client class takes that key when you construct it, for example AiCrawler(api_key="<API_KEY>"). The service itself lives at the AI Studio site, and the SDK is only a client for it.
What can the Oxylabs AI Studio Python SDK do?
Five things, each behind its own class: crawl a site from a natural language prompt, scrape a single URL, run a browser agent that drives a page before capture, run a search, and map a site. Crawl, scrape, search and map also take a JavaScript rendering flag, and crawl and map take an optional maximum credits value.
When does the Oxylabs SDK require a JSON schema?
Whenever the output format is json, csv or toon. Markdown and screenshot output need no schema. Both the scraper and the browser agent expose a generate_schema method that turns a natural language description of the fields into a schema you then pass to the call.
How do I render JavaScript with the Oxylabs SDK?
Pass render_javascript, which defaults to False on crawl, scrape, search and map. The scraper also accepts the string auto, which asks the service to decide whether rendering is needed. The scraper's browser_instructions list, covering actions such as clicking, typing and waiting, only works when render_javascript is True.
What is the difference between search and instant search in the Oxylabs SDK?
Instant search returns immediately without polling and caps its limit at ten results. The ordinary search defaults to a limit of ten with a maximum of fifty and returns page content by default, and when the limit is ten or less and content retrieval is off it automatically uses the instant endpoint instead.
Is the Oxylabs AI Studio Python SDK still maintained?
The repository is marked archived, and its only published release is version 0.2.19 from November 2025. The last commit on the default branch is dated 21 August 2026, and the project manifest declares version 0.2.22, so the source tree is ahead of the released package.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oxylabs-oxylabs-ai-studio-py)Star history chart for your README
[](https://hysenlabs.com/projects/oxylabs-oxylabs-ai-studio-py)Was this useful?