SEO Machine: eight empty context files decide how good the output is
A specialized Claude Code workspace for creating long-form, SEO-optimized blog content for any business. This system helps you research, write, analyze, and optimize content that ranks well and serves your target audience.
At a glance
- What is it?
- SEO Machine is a Claude Code workspace for long-form blog content rather than a library: slash commands for research, writing, analysing and rewriting, ten specialised agents, four of which run automatically after /write, and Python scripts for Google Analytics 4, Search Console and DataForSEO. The setup work is not the install, it is the eight template files in context/ that ship empty, which is where the quality ceiling actually sits.
- Who is it for?
- Adopt it if you already publish regularly and can supply your own brand voice, style guide, keyword research and three to five example posts, because that context is what the whole system runs on. Do not adopt it expecting finished posts, since the write command targets a word count and the scoring is the model reading its own output.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 22 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
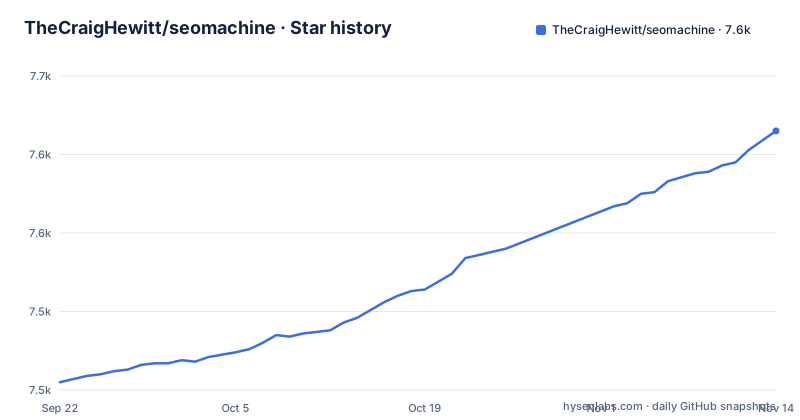
- TheCraigHewitt/seomachine7,615 ★ · +160
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| TheCraigHewitt/seomachine | 7.5k | 7.6k |
160 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every context file ships empty, and that is the real setup work
The installation section is three commands long:
git clone https://github.com/TheCraigHewitt/seomachine.git
cd seomachine
followed by `pip install -r data_sources/requirements.txt` for the analysis modules and `claude` to open the workspace. Then it stops and tells you the part that matters. Step four is marked Important, and it asks you to fill out eight template files in context/: brand-voice.md for voice and messaging, writing-examples.md for three to five exemplary blog posts from your site, features.md for your product or service features, internal-links-map.md for the pages you want linked, style-guide.md, target-keywords.md for your keyword research and topic clusters, competitor-analysis.md, and seo-guidelines.md. All of them are templates. The project ships a filled-in reference at examples/castos/, described as a complete real-world example for a podcast hosting SaaS company, which is the fastest way to understand what good looks like in these files. The consequence is blunt. A fresh clone is a competent workflow with no knowledge of your business, so whatever the commands produce before context/ is filled in will be generic, and the quality ceiling is set by those eight files rather than by the tooling.
Four agents fire on their own after the write command runs
The new content path is three commands, and the middle one does more than it says. `/research [topic]` performs keyword research, analyses the top ten competitors, identifies content gaps and writes a research brief into /research/. Then `/write [topic or research brief]` creates a 2000-3000+ word article, maintains the brand voice from context/brand-voice.md, integrates keywords, includes internal and external links, adds meta elements, and saves into /drafts/. The part worth planning around is the agent auto-execution that follows: after writing, the SEO Optimizer produces on-page recommendations, the Meta Creator generates several meta title and description options, the Internal Linker proposes specific links, and the Keyword Mapper analyses placement and density, all without you invoking them. Finally `/optimize [article file]` runs the audit, validates the elements, produces a publishing readiness score and writes an optimization report. So your review point is the file in /drafts/, not the command that produced it.
Existing content is scored before it is rewritten, and the rewrite is a new file
The refresh path is the more interesting one for a site with an archive. `/analyze-existing [URL or file path]` takes either a live URL or a file path, fetches and analyses the current content, evaluates its SEO performance, identifies outdated information, assesses competitive positioning, assigns a content health score from 0 to 100, and recommends update priority and scope, saving the analysis into /research/. From there `/rewrite [topic or analysis file]` updates the content based on those findings, refreshes statistics and examples, adds sections to fill the gaps, keeps what already worked, tracks what changed, and writes to /rewrites/ rather than overwriting anything. The output paths make that explicit: research briefs go to research/brief-[topic]-[date].md, drafts to drafts/[topic]-[date].md, rewrites to rewrites/[topic]-rewrite-[date].md, and analyses to research/analysis-[topic]-[date].md. Dated filenames and a separate rewrites directory mean nothing published is overwritten, which is the right default when a model is doing the editing.
Three scores from 0 to 100, all produced by the same workspace reading its own files
Numbers appear in several places and it is worth being clear about what they are. The overview lists an SEO quality rating from 0 to 100 as part of the advanced analysis, alongside search intent detection, keyword density and clustering, content length comparison and readability scoring. The analyse-existing command produces a content health score from 0 to 100. The optimise command produces a publishing readiness score. Three separate scores, one producer. That is not a criticism so much as a boundary: these are judgements made by a language model reading the draft and the context files, in the same session that wrote the draft. They are useful as a checklist surface, because the optimize command also validates that elements meet requirements and writes an optimization report you can read. They are not measurements of how the page will behave. If you want a number tied to reality, that comes from the analytics integrations rather than from the scores in the workflow.
Eleven Python scripts sit at the root, outside the Claude workspace
The repository root is not only a workspace. Alongside the directories for topics, research, drafts, published, output, rewrites and context, there is a row of standalone scripts: research_competitor_gaps.py, research_performance_matrix.py, research_priorities_comprehensive.py, research_quick_wins.py, research_serp_analysis.py, research_topic_clusters.py, research_trending.py, seo_baseline_analysis.py, seo_bofu_rankings.py and seo_competitor_analysis.py, plus test_dataforseo.py. The odd one out is test_dataforseo.py, which reads as a connectivity check for the DataForSEO credentials rather than an analysis. The practical consequence is that there are two ways to use this project. If you only want the commands, ignore the scripts.
Three credentials, two JSON files, and two different .env locations
The integrations are the part that needs real setup, and the environment file spells it out. Google Analytics 4 wants a GA4_PROPERTY_ID and a GA4_CREDENTIALS_PATH pointing at a service account JSON file. Google Search Console wants a GSC_SITE_URL, which the example notes must include https:// and a trailing slash, and a GSC_CREDENTIALS_PATH that can be the same service account file as GA4. DataForSEO wants a login email and an API password. There are also optional settings: BLOG_PATH, which defaults to /blog/ and exists so it matches your URL structure, plus COMPANY_NAME, COMPANY_DOMAIN and TARGET_INDUSTRY as context hints. The file opens with a warning never to commit a .env with real credentials, and the credentials directory is mounted as a volume in Docker. Note the two locations in play: the example environment file sits at the repository root, while both the README and docker-compose.yml point at data_sources/config/.env for the container.
The Dockerfile installs dependencies before it copies any of your code
The container is deliberately plain. It starts FROM python:3.12-slim, sets a working directory of /app, installs build-essential, gcc, libxml2-dev and libxslt1-dev with the comment that they are needed by scientific and XML Python packages, copies data_sources/requirements.txt to /tmp, installs it with pip and no cache, and only then copies the project in. That ordering is what makes the image cacheable: editing your content changes the final layer and nothing above it, while a change to requirements.txt invalidates the install. In practice the requirements come from data_sources/requirements.txt, which the installation section describes as bringing in the Google Analytics and Search Console integrations, the DataForSEO client, NLP libraries such as nltk and textstat, scikit-learn and beautifulsoup4. The compose file mounts context, drafts, output, published, research, rewrites, topics and credentials into the container, and it also mounts .claude, which is one more than the list of persisted directories the README enumerates.
Editorial conclusion
Adopt it if you already publish regularly and can supply your own brand voice, style guide, keyword research and three to five example posts, because that context is what the whole system runs on. Do not adopt it expecting finished posts, since the write command targets a word count and the scoring is the model reading its own output. Before you run anything, fill in context/ rather than skipping to /write, and decide whether the eleven root-level Python scripts or the Docker path is the surface you actually want to maintain.
Frequently asked questions
What is SEO Machine?
It is a Claude Code workspace for producing long-form blog content, not a library you import. It ships custom commands including /research, /write, /rewrite, /analyze-existing and /optimize, ten specialised agents such as an SEO optimizer, meta creator, internal linker and keyword mapper, 26 marketing skills, and integrations with Google Analytics 4, Google Search Console and DataForSEO. Content is organised into dated directories for research, drafts and rewrites.
How do I install SEO Machine?
Clone the repository, install the Python dependencies with pip install -r data_sources/requirements.txt, then open the directory with claude. You need Claude Code installed with a Claude subscription or Anthropic Console API billing, plus a DataForSEO account. After that, fill in the eight template files under context/, starting with brand-voice.md, writing-examples.md and target-keywords.md, since the commands read them to produce anything specific to your business.
Do I need Google Analytics and DataForSEO credentials to use SEO Machine?
Google Analytics and Search Console are optional integrations, but the README lists a DataForSEO account as a prerequisite. The example environment file lists GA4_PROPERTY_ID, GSC_SITE_URL, DATAFORSEO_LOGIN and DATAFORSEO_PASSWORD plus paths to two service account JSON files, and there is a test_dataforseo.py script at the repository root that reads like a connectivity check. Without those credentials the performance and competitor parts of the workflow have no data behind them.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thecraighewitt-seomachine)Star history chart for your README
[](https://hysenlabs.com/projects/thecraighewitt-seomachine)Was this useful?