PapersGPT indexes Zotero locally, then hands your questions to a cloud model
A powerful Zotero AI and MCP plugin with ChatGPT, Gemini 3.7, Claude Fable 5, Claude Opus 5, DeepSeek V4, Grok, OpenRouter, Kimi k3, GLM 5.3, SiliconFlow, GPT-oss, Gemma 4, Qwen 3.8
At a glance
- What is it?
- A Zotero plugin whose structural index is built and stored on your own machine while the model answering your questions can be a hosted API. The local claim is narrower than the header suggests, and the manifest tells a different version story from the release tags.
- Who is it for?
- Adopt PapersGPT if your Zotero library is large enough that indexing cost matters and you want the index on your own disk, and pair it with a local model through Ollama or a custom OpenAI-compatible endpoint when the documents are sensitive. Do not adopt it on the strength of the header claims: the page defers hardware specifications to benchmark.md, npm test exits 1 on purpose, and the manifest version reads 0.0.16 while the newest release tag is papersgpt-v1.7.0.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
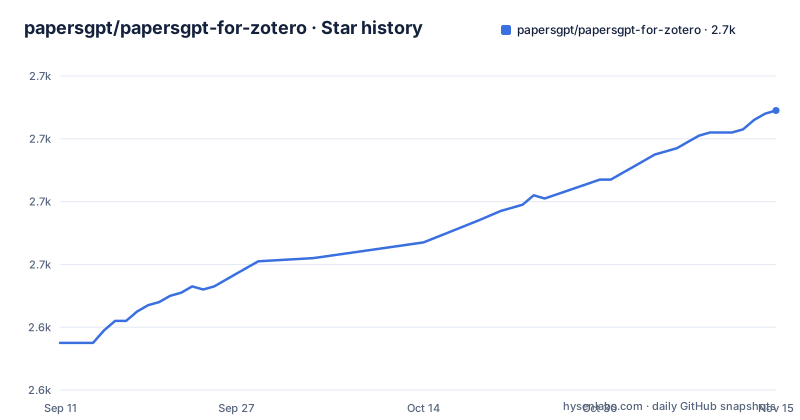
Star history
- papersgpt/papersgpt-for-zotero2,709 ★ · +74
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| papersgpt/papersgpt-for-zotero | 2.6k | 2.7k |
74 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Indexing is local, the model answering often is not
The README header reads "100% Local. Zero Hallucinations." Further down, the same page describes switching between a list of hosted models including DeepSeek, Claude, GPT, Gemini, GLM and Kimi, plus Grok and OpenRouter. Those two statements are not compatible, and the README itself gives the narrower version of the claim: parsing, indexing and searching your Zotero documents happen locally with no reliance on the cloud, and it is the structural index that runs 100% on your machine.
So the honest division is this. Your PDFs never leave the disk during indexing and search. The tokens you send to a hosted model when you ask a question still go out, and the promise of "zero-byte" data leakage is attached specifically to the combination of a local LLM with local document processing.
That combination is reachable. Three routes are offered: integrated open-source models such as Gemma 4 12B and Qwen3.5 4B, a custom OpenAI-compatible endpoint you deploy yourself, and any model already running under Ollama. The Airplane Mode line sits in the same breath as the first route, and selecting one of those models triggers an automatic download from Hugging Face, so a first run needs the network even if later queries do not.
The benchmark table has no machine under it
Two rows of numbers carry the performance argument, and neither row names the hardware.
| Library Size | Raw Data Size | Indexing Time | Avg. Query Time | Memory (RSS) | Index Size | | :--- | :--- | :--- | :--- | :--- | :--- | | 1,000 PDFs | 4.2 GB | 51.5s | 13.1 ms | 353 MB | 100 MB | | 10,000 PDFs | 42 GB | 421s (7m 01s) | 19.5 ms | 2.21 GB | 901 MB |
Ten times the documents means 9 times the index on disk, from 100 MB to 901 MB, and resident memory climbing from 353 MB to 2.21 GB, which sits awkwardly beside the page's promise of minimal RAM usage. The headline number above the table, 10,000 PDFs and 170k pages totalling 42GB indexed in 7 minutes, matches the 421s cell.
What the page does not give is the machine. Specifications, the README says, are in benchmark.md at the repository root. Automatic memory offloading is what the page credits for the footprint, and it does not quantify what gets offloaded or when.
package.json says 0.0.16 while the tags say v1.7.0
The manifest and the release history do not agree. package.json declares version 0.0.16, while the published tags are papersgpt-v1.7.0 from 2026-09-29, papersgpt-v1.6.0 from 2026-09-24 and papersgpt-v1.5.0 from 2026-09-11. The manifest version is not a build number anyone should cite; the tag is what identifies a release.
The description field has drifted the same way. The manifest still advertises ChatGPT, Gemini, Claude, DeepSeek, DeepSeek-R1-Distill-Llama, DeepSeek-R1-Distill-Qwen, Llama 3.2, QwQ-32B-Preview, Gemma and Mistral, while the repository description leads with a different and much longer provider list. Treat the model roster as marketing copy that moves faster than the manifest.
One date is worth noting: the newest release tag is dated five days after the last push to the branch, on 2026-09-24. The license is AGPL-3.0-or-later in the manifest, which for a plugin distributed as an .xpi means anyone modifying and redistributing it inherits the same obligation. Get that right with your own counsel rather than from a README.
npm test exits 1, and releasepage is an empty string
The build and run surface is short enough to quote in full, and two entries in it deserve attention:
    "build-dev": "cross-env NODE_ENV=development node scripts/build.js",
    "build-prod": "cross-env NODE_ENV=production node scripts/build.js",
    "tsc": "tsc --noEmit",
    "start-z6": "node scripts/start.js --z 6",
    "start-z7": "node scripts/start.js --z 7",
    "stop": "node scripts/stop.js",
    "release": "release-it"
The --z flag is the Zotero major version, so both 6 and 7 are covered and you choose at start time. `tsc --noEmit` type-checks without emitting, which means the compiled output comes from the build script and webpack path rather than from tsc.
Then the update configuration:
  "config": {
    "addonName": "PapersGPT",
    "addonID": "[email protected]",
    "releasepage": "",
    "updaterdf": ""
  },
Both update fields are empty strings even though update.json, update.rdf, update-template.json and update-template.rdf sit at the repository root, and the test script is `echo "Error: no test specified" && exit 1`. There is no automated test suite to run, which matters more here than usual because the README asks you to strip the caret constraints and retry when plugins fail to resolve.
Two vector database clients sit in a local-indexing plugin
The declared dependencies include @pinecone-database/pinecone at ^0.0.14 and chromadb at ^1.3.1. Both are client libraries for hosted or separately deployed vector stores, and both appear in a project whose pitch is that indexing happens on your machine with no external API. Either they are used for something the README never mentions, or they are leftovers.
Alongside them sit @dqbd/tiktoken for token counting, @iktakahiro/markdown-it-katex for math rendering in answers, crypto-js, dotenv, compute-cosine-similarity, ansi-styles and blueimp-md5. Two entries are stranger: `crypto` at ^1.0.1 and `fs` at ^0.0.1-security are names Node already provides, declared as runtime dependencies of a plugin that executes inside Zotero's own runtime.
The dependency list on the manifest page ends partway through an entry beginning with gp, so this is a partial view of what ships. What can be said from the visible portion is that the dependency surface is wider than a purely local index needs, and that no configuration file for any of it is documented anywhere in the README.
Installing means downloading an .xpi from the v1.7.0 release
There is no build step for a user. Step one is to download papersgpt-v1.7.0.xpi from the v1.7.0 release and install it through the Zotero plugin manager, with papersgpt.com/quickstart linked for detail. Everything after that happens inside Zotero.
Open a PDF from your library and the panel is reachable from the top menu of the PDF viewer or by keyboard, Command + Enter on macOS and Ctrl + Enter on Windows. For several documents, select multiple files or a whole collection, Ctrl-clicking on Windows and Command-clicking on Mac. For the entire library there is a "Search entire library" checkbox in PapersGPT, which searches across all your documents and synthesises an answer.
Step two is choosing a model and entering its API key, with papersgpt.com/models linked for the detail, and then either picking a built-in prompt such as Summary, Background, a literature review, theoretical frameworks or future directions, or typing your own question. Step three is saving what you want to keep and closing the window with the red cross.
Where the key is stored, how to revoke it, and what to do when a plugin refuses to resolve are not covered on this page.
MCP and SKILL support are documented in another repository
The agent integration is real but delegated. The README says the plugin supports MCP, which lets you reach Zotero papers, Obsidian and Apple Notes from Claude and the ChatGPT desktop app, then sends you to the docsagent/docsagent repository for how it works. A separate note says you can index and search your whole library without starting Zotero at all, again through mcp-zotero in that other repository.
Inside this repository the only artefact is a SKILL.md under papersgpt-for-zotero/, described as providing agents for connecting to a local Zotero library, plus a pointer for OpenClaw users. The page ends partway through that OpenClaw link, so what it would have said about that route is not visible here.
The same pattern applies to AutoPilot, which the README calls the first autonomous researcher for Zotero: define a goal and it batch-processes 1,000 or more papers overnight, writing insights into Zotero Notes while you sleep. That is the most powerful claim on the page and the least specified one, with no configuration surface shown. The citation feature is better evidenced, since clickable citations that jump to the cited paper are a concrete mechanism a reader can check.
Editorial conclusion
Adopt PapersGPT if your Zotero library is large enough that indexing cost matters and you want the index on your own disk, and pair it with a local model through Ollama or a custom OpenAI-compatible endpoint when the documents are sensitive. Do not adopt it on the strength of the header claims: the page defers hardware specifications to benchmark.md, npm test exits 1 on purpose, and the manifest version reads 0.0.16 while the newest release tag is papersgpt-v1.7.0. Verify first which Zotero major version you run, because the start scripts pass --z 6 or --z 7 and the install step is an .xpi from that v1.7.0 release.
Frequently asked questions
Does PapersGPT for Zotero send my PDFs to a cloud service?
The README states that parsing, indexing and searching Zotero documents are performed locally, and that the structural index runs 100% on your machine. The model that answers your question can still be a hosted one unless you connect a local LLM.
Can PapersGPT for Zotero run without an internet connection?
The README says the plugin works in Airplane Mode and supports 100% offline local LLMs through three routes: integrated open-source models, a custom OpenAI-compatible endpoint, and Ollama. Selecting one of the integrated models triggers an automatic download from Hugging Face, so the first run needs the network.
Which versions of Zotero does PapersGPT support?
The build scripts include start-z6 and start-z7, which pass --z 6 and --z 7 to node scripts/start.js, so both Zotero 6 and Zotero 7 are covered. The user-facing install is an .xpi loaded through the Zotero plugin manager.
How do I install the PapersGPT Zotero plugin?
Download papersgpt-v1.7.0.xpi from the papersgpt-v1.7.0 release and install it as a Zotero plugin. The README links to papersgpt.com/quickstart for the step-by-step version and does not document a source build for end users.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/papersgpt-papersgpt-for-zotero)Star history chart for your README
[](https://hysenlabs.com/projects/papersgpt-papersgpt-for-zotero)Was this useful?