Pigsty hands you a whole Postgres platform, not just a database
Enterprise-Grade OSS PostgreSQL Distribution with HA, PITR, IaC, Monitor, 12 kernel forks and 575 PG extensions. Best-of-breed products integrated as a platform. Self-host Postgres like a Pro!
At a glance
- What is it?
- Pigsty is an Ansible-driven PostgreSQL distribution that bundles extensions, kernel forks, pooling, backups and Grafana dashboards into one install. The trade is that you inherit every component it deploys.
- Who is it for?
- Pigsty fits teams that want a managed-Postgres shape on hardware they own, especially when the workload needs wire compatibility with MySQL, SQL Server, Oracle or MongoDB, or a fork such as Citus or pgEdge. It does not fit a team that only wants the postgres package and nothing else, since the install brings haproxy, pgbouncer, Victoria and Grafana with it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Shell, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
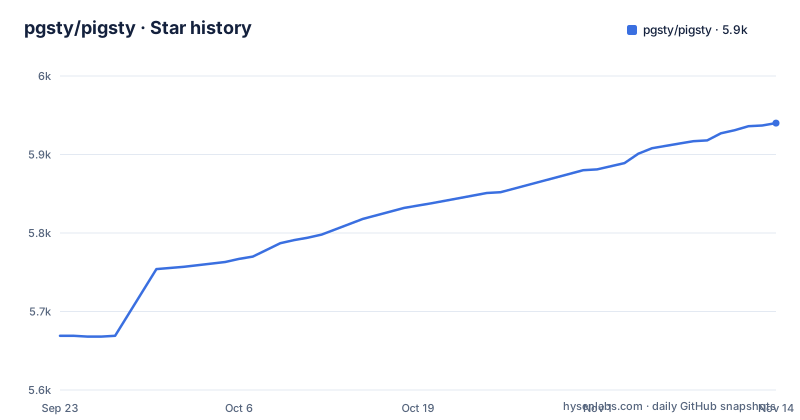
- pgsty/pigsty5,940 ★ · +271
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| pgsty/pigsty | 5.7k | 5.9k |
271 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One piped command installs the whole stack, and the version is a shell argument
Installation is a single line that fetches a script and runs it. The README pins the current release by passing the version after the pipe:
curl -fsSL https://repo.pigsty.io/get | bash -s v4.5.0Drop the argument and you track the moving target instead. That argument is the whole pinning story: the Makefile quick-start target prints the unpinned form and then names the two follow-up steps:
./bootstrap
./configure
The Makefile is explicit about the host requirement, printing "Run on Linux node with nopass sudo & ssh access" as its own echo line. No container runtime is required, and the project positions itself against Docker and Kubernetes by running directly on bare Linux. The cost of that convenience is that a shell script is piped straight into an interpreter with administrative rights and no checksum in the command line, so the version pin and your own review of what the script does are the controls you actually have.
ARCH and OS variables pick one of eight prebuilt package names
Before anything downloads, the Makefile decides which artifact you get. It defaults to `ARCH?=x86_64`, then probes `uname -m` and rewrites both arm64 and aarch64 to `aarch64`, so Apple Silicon and Graviton hosts land on the same name.
From those two values it derives eight distribution-specific package filenames: el8, el9 and el10 for the RHEL family, d12 and d13 for Debian, and u22, u24 and u26 for Ubuntu. Each becomes `pigsty-pkg-v4.5.0.<tag>.<arch>.tgz`. Four more package variables cover the source, app, DBA and Docker bundles.
One default deserves attention before you deploy anything. `META?=10.10.10.10` is a literal address sitting in the Makefile, and the question-mark syntax means an environment value can override it. If that address is already routed on your network, whatever consumes META will collide with it. Set it deliberately rather than accepting the default.
Every component ships a playbook and an -rm.yml twin
The repository root reads like an operations runbook because it essentially is one. Playbooks exist per concern: `pgsql.yml`, `pgsql-monitor.yml`, `pgsql-pitr.yml`, `pgsql-user.yml`, `pgsql-migration.yml`, `node.yml`, `infra.yml`, `deploy.yml`, `cert.yml`, `docker.yml` and `app.yml`.
Non-Postgres data services get the same treatment. Redis, MinIO, Etcd, Kafka and MySQL each have their own pair of playbooks, and the Kafka, MinIO, Redis, MySQL, Etcd, node, infra and pgsql sets all have a matching `rm` file for removal, for example `redis-rm.yml` beside `redis.yml`. A `slim.yml` entry point sits alongside the full `deploy.yml`.
Underneath sit the directories Ansible needs: `roles/`, `conf/`, `files/`, `templates/`, `app/`, `docker/`, `terraform/`, `vagrant/` and `bin/`, plus `ansible.cfg` and the `bootstrap` and `configure` scripts. The declared primary language is Shell, which matches the installer-first shape. The consequence for an operator is that a component you never wanted is still one file away from being deployed or torn down.
Kernel forks change wire compatibility, not just the version number
The catalog of PostgreSQL kernels is the part that distinguishes Pigsty from a tuned upstream install. Each entry swaps the engine while leaving the surrounding platform in place.
Four of them exist for protocol compatibility: Babelfish brings Microsoft SQL Server wire compatibility, IvorySQL offers Oracle grammar and PL/SQL compatibility, OpenHalo targets the MySQL wire protocol, and DocumentDB covers MongoDB wire compatibility. Two scale by architecture instead. Citus distributes through a native extension for horizontal scaling, and pgEdge is a geo-distributive multi-writer Postgres. Cloudberry is a Greenplum 7 Apache OSS fork serving as an MPP data warehouse, and AgensGraph is a transactional graph database built on PostgreSQL.
The remaining entries change storage or engine internals. Percona is the Percona distribution with pg_tde for transparent data encryption, OrioleDB is an OLTP engine described as having no bloat, no XID wraparound and S3 storage, and PolarDB is an Aurora-flavored RAC. The base entry is original PGDG PostgreSQL with the full extension set. The project claims 12 kernels; Supabase also appears in the table, framed as backend as a service over PostgreSQL and a Firebase alternative.
Pooling and routing live in front of the port, so a kernel swap keeps your entry point
Client access is handled by three separate pieces: haproxy, pgbouncer and a VIP. The README describes database services as auto-routed and pooled and customizable, and PITR is pre-configured alongside built-in ACLs and CA and SSL certificates managed through the infra admin path.
The other side of that design is that you now run three more moving parts per instance group.
Monitoring is a replaced Grafana and Victoria stack you then own
Observability does not come from a Postgres extension bolted onto the server. Pigsty deploys a Victoria and Grafana stack and builds monitoring for three layers from it: the database, the infrastructure and the node. The project publishes a public demo at demo.pigsty.io and a dashboard gallery in the repository wiki, which is the fastest way to see what the dashboards actually look like before deploying.
Maintaining that stack is the ongoing cost. Grafana and Victoria are separate from PostgreSQL, so version upgrades and dashboard fixes are yours after install. The repository also carries an `AGENTS.md` and a `CLAUDE.md` at the root alongside `SECURITY.md` and `CONTRIBUTING.md`, and the licensing is Apache-2.0 with a `LICENSE` file, a `NOTICE` file and a `KEYS` file for release verification.
Release cadence has been steady through 2026. v4.3.0 shipped on 2026-05-03 with a title referencing 510 extensions, v4.4.0 on 2026-07-10 as a better CLI release, and v4.5.0 on 2026-08-14 adding Silo, Valkey and Kafka. The last push to the default branch was on 2026-10-26, and the repository is not archived.
The cost of the distribution is everything it installs alongside the database
Pigsty describes itself as scaling from a laptop to a datacenter, which is a sizing claim in its own documentation rather than a measured result, and it points at a public demo rather than published benchmarks. What is concrete is the breadth: 575 PG extensions, 12 kernels and packages for 16 Linux platforms, with the extension count already having moved from 510 at v4.3.0 to 575 by v4.5.0.
Two practical limits follow. First, an install that provisions the database, haproxy, pgbouncer, a VIP, certificates, Grafana and Victoria is heavier than a package manager install of PostgreSQL, and it wants a nopass sudo Linux host rather than a container. Second, because every data service has its own playbook and removal twin, the operational surface you sign up for is the union of everything listed, not just the engine.
The comparison Pigsty draws is against managed cloud database pricing, and it positions itself as running on bare Linux without Docker and Kubernetes. If your constraint is licensing or data residency, that is the case it makes well. If your constraint is a small footprint, this is the wrong shape.
Editorial conclusion
Pigsty fits teams that want a managed-Postgres shape on hardware they own, especially when the workload needs wire compatibility with MySQL, SQL Server, Oracle or MongoDB, or a fork such as Citus or pgEdge. It does not fit a team that only wants the postgres package and nothing else, since the install brings haproxy, pgbouncer, Victoria and Grafana with it. Verify first that the pinned version string matches your target major release and that the META address in the Makefile default is not already taken on your network before running the installer.
Frequently asked questions
How do I install a specific version of Pigsty?
The installer accepts the release as an argument after the pipe, and the README pins the current release with `curl -fsSL https://repo.pigsty.io/get | bash -s v4.5.0`. The Makefile quick-start target prints the unpinned form of that command followed by the bootstrap and configure steps, and states the host must be a Linux node with nopass sudo and ssh access.
Which Linux platforms does Pigsty ship packages for?
Packages are named for el8, el9, el10, d12, d13, u22, u24 and u26, built from a version string plus a detected architecture. The Makefile defaults ARCH to x86_64 and rewrites arm64 or aarch64 to aarch64, and the README states packages are packed for 16 Linux platforms.
Can Pigsty run workloads written for MySQL, SQL Server or MongoDB?
It ships kernel forks aimed at those protocols: Babelfish for SQL Server wire compatibility, OpenHalo for the MySQL wire protocol, IvorySQL for Oracle grammar and PL/SQL, and DocumentDB for MongoDB wire compatibility. Each is described as an in-place replacement you can wrap as a full service.
What does Pigsty do about backups and access control?
Backups and point-in-time recovery are pre-configured rather than left as a manual step, and built-in ACLs plus CA and SSL certificate handling are part of the default install. The repository root holds a dedicated pgsql-pitr.yml playbook and a cert.yml playbook for that side of the stack.
Do I need Docker or Kubernetes to run Pigsty?
No. The project positions itself as running on bare Linux without Docker and Kubernetes, and the installer is a shell script with an Ansible playbook set behind it. Docker is available as an optional module with its own docker.yml playbook rather than as a requirement.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pgsty-pigsty)Star history chart for your README
[](https://hysenlabs.com/projects/pgsty-pigsty)Was this useful?