agents-from-scratch has one dependency, and it compiles C++
Build AI agents from first principles using a local LLM - no frameworks, no cloud APIs, no hidden reasoning.
At a glance
- What is it?
- A twelve-lesson curriculum that grows a single AI agent one stage at a time against a local GGUF model, with no framework and no cloud API. The design argument is that reliability comes from structure rather than prompt wording. The practical detail is that the whole no-dependency position rests on one unpinned package that builds a native inference engine from source.
- Who is it for?
- Read this one if you already write code and want a mechanical picture of what an agent loop actually does, because that is exactly what it promises and exactly what it delivers: one file that grows, twelve lessons you are told not to reorder, and a running example per lesson so you can see each stage alone before it is composed.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 113 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
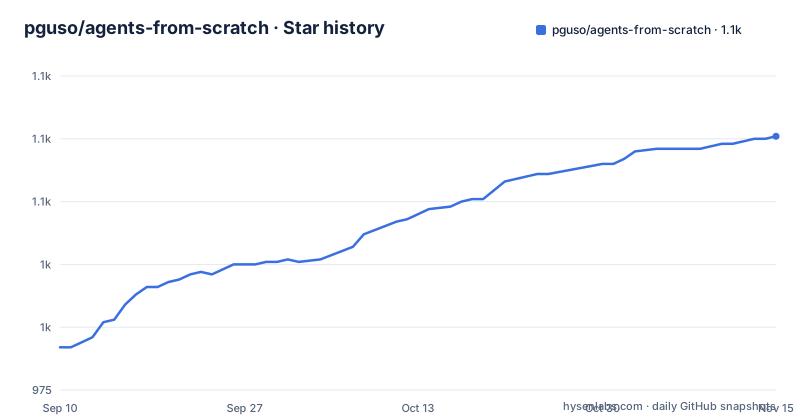
- pguso/agents-from-scratch1,076 ★ · +84
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| pguso/agents-from-scratch | 992 | 1.1k |
84 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The entire dependency list is one unpinned native binding
The requirements file has a single line in it:
llama-cpp-pythonThat is the whole list. No version constraint, no hash, nothing else.
The position this supports is stated plainly on the front page: no frameworks, no cloud APIs, no hidden reasoning, no magic. And it holds in the sense that matters for the curriculum, because there is no agent framework being pulled in, no model provider SDK, no telemetry library, no JSON schema package. The loop, the state and the tool dispatch are all in the repository.
But the one dependency is not a pure-Python convenience. It is the Python binding for a native inference engine, which in practice compiles from source unless a matching wheel exists for your platform and interpreter. So the lightest possible install path still involves a toolchain on many machines, and the documentation's three-step quick start does not mention that.
Nothing here is wrong. It is worth knowing that the simplest possible repository to clone is also the one that may take the longest to install.
One class, twelve lessons, and a file you are meant to edit
The central design choice is that this is one evolving agent, not twelve examples. The same agent file grows across the lessons, each one adding methods and a capability to the same class, and that file is described as the heart of the repository and the thing you study and modify.
Alongside it sits a second file with twelve separate functions, one per lesson, each demonstrating that lesson's concepts in isolation. The relationship is stated explicitly: one file is the implementation you are learning, the other is the isolated examples to try before combining them. Both are meant to be run, through the same entry point.
The curriculum is ordered and the order is defended. Foundation first, three lessons on the model call, roles and structured output. Then agency, three lessons on routing decisions, tools and the loop itself. Then intelligence, four lessons on memory, planning, atomic actions and a dependency-graph representation of thought. Then two lessons on evals and telemetry.
The instruction is not to skip ahead, which is a claim about how the concepts compose rather than about difficulty. If you already know what a tool call is, lessons four and five will feel thin while seven and eight are where the design argument gets interesting.
The quick start is three steps, and the setup checker is not one of them
The getting started section is deliberately short, with the detail pushed into a separate document. In short: install the dependencies with pip from the requirements file, download a GGUF model into a models folder, and run the complete example script.
The models folder is a place rather than a download, so which model you pick is your decision, and nothing in the quick start says how large a file to expect or what class of machine it needs. That is the kind of thing the longer setup guide is for.
The gap is that the repository root contains a script called setup_check.py, and the three-step quick start never mentions it. Whatever that script verifies, an environment problem surfaces at the first model call instead.
The complete example is described as containing executable code demonstrating all twelve lessons, which makes it the natural smoke test: if it runs, the binding, the model file and the agent loop all work. That is a better first command than any individual lesson, and it is listed third for that reason.
The output of running it is the other thing worth noticing here, which is that a telemetry file exists at the repository root.
The structure diagram names a different directory and lower-cases a file
The repository structure block has three small errors, which is worth a paragraph because it is the map a newcomer reads first.
The tree is headed with a directory name that is not the repository name. The repository is agents-from-scratch; the diagram says ai-agents-from-scratch. That is the name of a sibling repository, so the diagram was very likely copied from the JavaScript version of this same course.
Inside it, a file is written in lower case as philosophy.md while the repository root holds the same file in upper case. On a case-insensitive filesystem nobody notices; on Linux the diagram points at a file that does not exist.
The diagram also stops listing the agent directory after three files, ending partway through the description of the planning module. The two files that the very next section goes on to explain, the evaluation module and the telemetry module, never appear in the diagram at all.
None of this changes what the repository does. It does mean the one piece of orientation material in the project is the piece that cannot be trusted, and that the files most worth reading are the ones the map omits.
A telemetry output file is committed to the repository root
Lesson twelve is telemetry, described as runtime observability with structured logging for debugging and tracking of latency, success rates and traces. And the repository root contains a file called agent_telemetry.jsonl.
That is a run artefact, not source. Somebody ran the lesson twelve code and the output stayed where it landed, which means the file in the repository is whatever that one run produced.
It is a small thing with two consequences worth noting. A reader who opens it gets a sense of the trace format the lesson teaches, which is genuinely useful. And it means the repository root is not a clean list of inputs, so a newcomer looking for the code has one more non-code file to skip.
There is a second split in the same area. Evaluation code is described as living in the agent directory, while the repository root also has a separate evaluations directory. Two locations for the two halves of lesson eleven, with only the in-package one documented.
Taken with the setup script that is not in the quick start and the structure diagram that is out of date, the pattern is consistent: this is a repository maintained by one person for teaching purposes, where the teaching is in good order and the housekeeping is not.
Structure over prompting, which is the argument the curriculum is built on
Five principles are listed, and the third one is the thesis.
Reliability comes from constraints rather than clever wording. Every lesson that follows is a mechanism for that claim: structured output through JSON contracts in lesson three, routing logic as explicit decisions in lesson four, the loop itself as observe then decide then act in lesson six, planning held as data rather than as thoughts in lesson eight, atomic actions for safe execution in lesson nine, and a dependency-graph representation of thought in lesson ten.
That last one is the most interesting. Atom of Thought is presented as a way to hold reasoning steps as a dependency graph rather than as a linear chain, which is a data structure you can inspect, reorder and test. It is also the point where this repository differs most from a chat-shaped approach to agents, and where a reader who disagrees with the representation will get the most out of the lesson.
The remaining principles are about shape rather than mechanism: one agent with many stages, explicit over implicit, local-first with no API keys and no rate limits, and educational rather than production.
The one line that runs through all of them is a refusal. The repository does not claim models think, and it does not expose chain-of-thought.
Two lists of what this repository is not
There is a list of who the repository is for and, underneath it, a list of who it is not for. The second list is more specific than most projects manage: not for people looking for the fastest demo, not for people who want a SaaS starter kit, not for people who believe agents think, and not for people who want hidden chain-of-thought.
Then a separate section repeats the point in a different form. This is not a framework. This is not a chatbot demo. This does not claim models think. This does not expose chain-of-thought. This does not require OpenAI or cloud APIs.
Two lists saying the same thing is not redundancy here. The audience list tells a reader whether they will enjoy it, and the identity list tells a reader what they may safely claim after using it. The second one is doing reputational work: if you build on this and then market chain-of-thought visibility, you are not misrepresenting this project.
The philosophy section adds the line that everything here is loops, state and constraints, and that if something feels like magic you should open the file because there is no hidden logic in it. That is a promise about a repository you can verify by reading it, which is a rarer thing than it sounds.
Three repositories, two languages, and inconsistent names
The related projects section points at two siblings from the same author.
One is a JavaScript version of this same course, a separate repository. The other is a product-building course on TypeScript, React and Node, running to ten lessons covering prompt engineering, structured output, multi-step reasoning, API design and frontend integration with visual diagrams.
The naming across the three is inconsistent in a way that will send someone searching to the wrong place. This repository is agents-from-scratch. Its JavaScript counterpart is ai-agents-from-scratch, with the ai prefix. The product course is ai-product-from-scratch. Two of the three use the prefix and this one does not, and the structure diagram in this repository uses the prefixed name of the sibling that is written in a different language.
The stack split is clean otherwise. This one is Python with a native binding and GGUF weights, the other two are JavaScript and TypeScript with a browser front end.
There are also diagram assets and a set of per-lesson markdown documents at the repository root, which is where the written half of the curriculum lives.
Editorial conclusion
Read this one if you already write code and want a mechanical picture of what an agent loop actually does, because that is exactly what it promises and exactly what it delivers: one file that grows, twelve lessons you are told not to reorder, and a running example per lesson so you can see each stage alone before it is composed. Do not reach for it if you want a production starting point, because the repository says so itself and adds that it teaches fundamentals rather than best practices. Two practical checks before you start. Budget for the dependency: the only package in the requirements file is the Python binding for a native inference engine, unpinned, which usually means a source build. And use the tutorial's own admission as your acceptance test, since it states plainly that it does not claim models think and does not expose chain-of-thought. If you want a chatbot that talks to a hosted model, this is the wrong repository and it tells you so.
Frequently asked questions
What do I need to run pguso/agents-from-scratch?
Three things: pip install -r requirements.txt, a GGUF model file placed in the models folder, and python complete_example.py. The requirements file contains exactly one package, llama-cpp-python, with no version constraint. The repository also contains a setup_check.py script that the quick start does not mention.
Does agents-from-scratch use LangChain or any agent framework?
No. The front page states no frameworks, no cloud APIs and no hidden reasoning, and the only dependency is a binding for a local inference engine. A separate line in the documentation names people tired of being told to just use LangChain as one of its intended readers.
How is the pguso/agents-from-scratch course structured?
Twelve lessons that grow one agent class rather than twelve separate examples. Three lessons on foundation, three on agency including the loop, four on memory, planning, atomic actions and Atom of Thought dependency graphs, and two on evals and telemetry. The learning path says not to skip ahead.
Does agents-from-scratch show the model's chain-of-thought?
No, and it says so twice. The repository states it does not claim models think and does not expose chain-of-thought, and its intended readers explicitly exclude people who want hidden chain-of-thought. Planning is taught as data in lesson eight and Atom of Thought as a dependency graph in lesson ten.
Is pguso/agents-from-scratch production ready?
It says it is not. One of its five core principles is educational rather than production, described as teaching fundamentals and not best practices, and it is described as not a framework and not a chatbot demo. It also contains a telemetry output file from a previous run at its root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pguso-agents-from-scratch)Star history chart for your README
[](https://hysenlabs.com/projects/pguso-agents-from-scratch)Was this useful?