pikepdf: a setup.py that exists only to raise, a Makefile pinned to uv, and an sdist that refuses to ship qpdf
A Python library for reading and writing PDF, powered by QPDF
At a glance
- What is it?
- A Python library for reading, writing and repairing PDFs on top of the qpdf C++ library. Its build has moved to scikit-build-core with nanobind, the old setup.py is kept as a script that raises an error, the test Makefile refuses bare pip because an old pip silently drops C++ changes, and the sdist is configured to exclude the qpdf sources the CI compiles.
- Who is it for?
- Reach for pikepdf when a PDF arrives damaged, when a merge or metadata edit has to survive PDF/A conformance, or when you need object level access that a higher level library will not give you. Do not reach for it to generate documents from HTML, to rasterise pages, or to pull text and tables out, because the project names the tools for each of those and they are different libraries.
- Can I use it commercially?
- Yes, with conditions. MPL-2.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
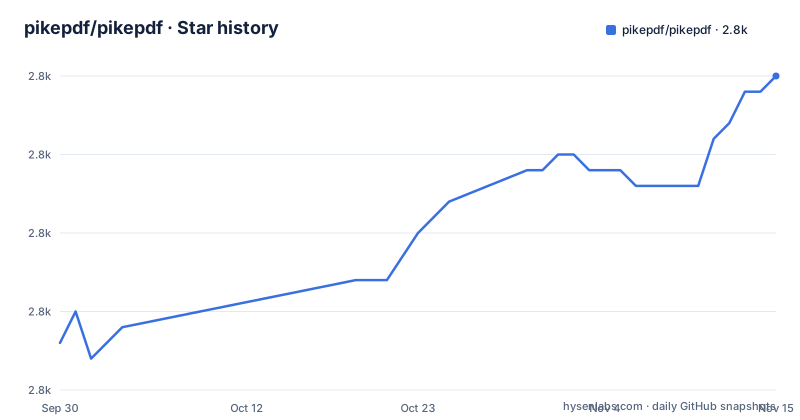
- pikepdf/pikepdf2,825 ★ · +17
| Repository | 2026-09-30 | 2026-11-15 |
|---|---|---|
| pikepdf/pikepdf | 2.8k | 2.8k |
17 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
setup.py is kept in the tree only to refuse to build
The most direct thing in this repository is a build script that does nothing but fail. setup.py opens with a docstring calling itself an obsolete setup script and saying that pikepdf now uses scikit-build-core with nanobind, then raises a RuntimeError stating that pikepdf no longer uses setuptools for building and pointing at pip install -e . or pip install . instead. It is left in place on purpose, which is why a reader who finds it should not read it as a working entry point. The real build configuration is pyproject.toml: scikit-build-core at 0.10 or newer and nanobind at 2.0 or newer as build requirements, the scikit_build_core.build backend, the package mapped to src/pikepdf, a Release CMake build type, and the wheel tagged for the cp314 Python API. Two project fields matter for anyone pinning a version: it declares version 10.16.0 and requires Python 3.11 or newer. Almost every text file in the tree opens with the same two comment lines, an SPDX file copyright line naming James R. Barlow and the year 2022, and an SPDX licence identifier for MPL-2.0, which is how the REUSE tooling in the root can verify licensing without a human reading headers. The native side is formatted by a .clang-format file at the root, and the project classifiers list C++ among the programming languages even though the interface is Python.
The Makefile says it is only for testing, and it pins uv over pip
The first comment in the Makefile is that this is really just for testing, and the rest of it explains why the obvious command does not work. The build target runs uv pip install --no-build-isolation -e . rather than pip, and a comment above it spells out the reason: the virtual environment ships an old pip, 22.0.x, which does not reliably recompile the scikit-build-core editable extension, so repeated pip install -e . reuses a stale build and silently drops C++ changes. That is a specific and expensive failure, the kind where the Python side updates and the native side does not. Tests run pytest with -n auto after the build. Coverage is split in two, one path through pytest and --cov for Python and another that rebuilds with CMAKE_ARGS carrying the coverage compiler and linker flags, captures with lcov, extracts only the paths under src/core, and renders HTML with genhtml. The clean targets delete coverage files and remove src/pikepdf/_core.*so, and the build target first deletes stale gcno files so that a stale native build cannot masquerade as a fresh one.
The sdist is configured so it cannot ship qpdf by accident
One block in pyproject.toml is worth reading closely because it explains a whole class of packaging bug. The comment says the wheel-building CI jobs download the qpdf source into a qpdf directory to compile libqpdf before building, and that without an exclusion scikit-build-core sweeps that entire tree, roughly 2,900 Apache-2.0 files, into the source distribution. Two harms are named: the sdist becomes bloated, and it misrepresents itself as containing third-party source. The fix is a single line, sdist.exclude set to qpdf, and the principle stated next to it is that libqpdf is a build prerequisite and not part of pikepdf's source. That distinction runs through the rest of the packaging too: the compiled library is vendored into the binary wheels by the platform specific tools, and those components are accounted for separately from the project's own licence. The root carries the pieces that make this auditable: LICENSE.txt for the project itself, a LICENSES/ directory and a REUSE.toml for the reuse format, and third-party-licenses/ for what ends up inside a wheel.
Licence files are enumerated per vendored library, not globbed
The licence story is unusually explicit for a package with native code. The project licence is MPL-2.0, described as liberal and compatible with most open and closed source projects, and the metadata declares its licence files under PEP 639 rather than relying on a default glob. The list covers LICENSE.txt and everything under third-party-licenses, and the comment explains why: that directory covers the compiled libraries that auditwheel, delocate and delvewheel vendor into binary wheels on the three platforms, with a README there mapping each component to its licence. Setting the list explicitly also replaces the build backend's default licence glob, which on case-insensitive Windows filesystems matched files it should not have. That is a small entry with a real consequence, since a wrongly matched licence file ends up in the wheel metadata. The repository also carries REUSE.toml and a LICENSES/ directory, so the licensing information is expressed in the format that automated reuse tooling reads.
Binary wheels everywhere, including free-threaded CPython
Installing is one command, and the packaging work exists so that a compiler is not needed:
pip install pikepdfThe page states that binary wheels are available for the common platforms, Linux, macOS and Windows, on both x86-64 and ARM64 including Apple Silicon, and that this includes free-threaded, no-GIL, CPython 3.14. The build configuration matches that claim from the other side: the wheel is pinned to the cp314 Python API and compiled as a Release build. The declared floor is Python 3.11 or newer. Anyone who does need to compile has a separate source build document linked from the installation section, and the page notes that commercial support is available for that path. The three most recent releases, 10.16.0 on 2026-09-29, 10.15.0 on 2026-09-28 and 10.14.0 on 2026-09-26, also show how often the native layer changes under that version scheme, which is the other reason the wheel story matters.
Encryption covers AES and RC4, but not signature-based schemes
Opening a password-protected file takes the password as an argument, and saving can add encryption with a user password and an owner password. Three algorithms are named as available output: AES-256, AES-128 and RC4. Encryption is also removable, by saving with encryption set to false, and the example notes the condition for that to work, which is that the user password is not set. One limitation is stated flatly and is worth quoting rather than paraphrasing: digital signature based encryption is not currently supported. That is a different thing from signing a document, and the phrasing matters, because a reader looking for signature support will find nothing here. Everything in this area is passed through to qpdf, so the algorithm set is inherited from the C++ library rather than chosen by the Python layer.
Repair happens silently at open time, which changes what you see
The behaviour worth understanding first is that opening a file can change it before you do anything. Because the library sits on qpdf, opening a PDF repairs structural damage automatically and quietly, which the feature list describes as silently fixing many types of PDF damage on open. That has two consequences: a file you open and save unchanged may differ from the one you opened, and a document that other tools consider broken will load here. Alongside that, the page claims PDF/A conformance survives modification, image extraction is lossless with no re-encoding of JPEGs or other compressed formats, XMP and DocumentInfo metadata are synchronised automatically as you write either one, and saving with linearize set to true produces a fast web view for streaming. For low-level work, the object model mirrors the specification, with dictionaries, arrays, streams and names mapping onto Python types: a page exposes its MediaBox as a plain list of numbers such as [0, 0, 612, 792], its Resources.XObject dictionary holds the images and forms on that page, and rotation can be set either by assigning to the page attribute or through a call with a relative flag. Images on a page are walked as a mapping and each one extracted to a filename prefix. The Job API goes further and exposes qpdf's command line behaviour, including running a check on a document and driving the JSON job interface with a dictionary of settings.
The page names four jobs pikepdf is the wrong tool for
The most useful paragraph for anyone choosing a library is the list of what this one is not for. Generating PDFs from HTML or templates belongs to weasyprint or reportlab. Rendering pages to images belongs to PyMuPDF or pypdfium2. Extracting text or tables belongs to pdfminer.six or pdfplumber. The neighbouring section adds the landscape: pypdf is pure Python and suits straightforward work without compiled dependencies, pypdfium is the permissively licensed rendering option, PyMuPDF covers rendering and text extraction, and pikepdf is positioned around correctness, repair and low-level manipulation under MPL-2.0. Even the name is explained on the page, since Python plus qpdf gives pyqpdf, which is pronounced like pikepdf. The page closes with testimonials, including one from the creator of qpdf. Two details are worth noticing in the surrounding lists. Cropping appears in the list of jobs this library fits, alongside merging, splitting, rotating and rearranging, while the worked examples on the page only demonstrate merging and rotating, so cropping is claimed rather than shown. And notebook rendering is listed as a feature, meaning PDF and page previews can be drawn inline in Jupyter. Around the documentation the tree carries a fuzzing/ directory, a context7.json file, a prek.toml for hooks, a uv.lock, and four examples covering benchmarking, object construction benchmarks, form filling and link finding.
Editorial conclusion
Reach for pikepdf when a PDF arrives damaged, when a merge or metadata edit has to survive PDF/A conformance, or when you need object level access that a higher level library will not give you. Do not reach for it to generate documents from HTML, to rasterise pages, or to pull text and tables out, because the project names the tools for each of those and they are different libraries. Two practical checks before you commit: read the release cadence, since three 10.x releases landed within four days, and if you build from source, read the build instructions rather than improvising, because the packaging is scikit-build-core with nanobind and the plain setup.py left in the tree deliberately fails. The MPL-2.0 licence and the shipped third-party-licenses mapping make redistribution easier to reason about than most native extensions manage.
Frequently asked questions
what is pikepdf
A Python library for reading, writing, repairing and transforming PDF files, built on the qpdf C++ library. It offers page manipulation, XMP and DocumentInfo metadata editing with automatic synchronisation between the two, lossless image extraction, encryption with AES-256, AES-128 or RC4, linearization for web delivery, direct object access that mirrors the PDF specification, and programmatic access to qpdf's own job interface.
how to install pikepdf
Run pip install pikepdf. Binary wheels cover Linux, macOS and Windows on x86-64 and ARM64 including Apple Silicon, and include free-threaded no-GIL CPython 3.14, so no compiler is needed. Building from source is documented separately, and the project declares Python 3.11 or newer as the floor.
Is pikepdf free to use?
Its licence is MPL-2.0, which the project describes as liberal and compatible with most open and closed source projects. Because the wheels vendor compiled libraries, those components are enumerated under third-party-licenses with a component to licence mapping rather than left implicit.
How does pikepdf differ from qpdf itself?
pikepdf is the Python layer over the qpdf C++ library, and its Job API is the bridge that exposes qpdf's command line capabilities to Python, including qpdf's JSON job interface. Opening a file through pikepdf also repairs structural damage automatically, which is qpdf behaviour inherited rather than reimplemented.
Can pikepdf render a PDF page to an image?
Not as its purpose. The project points rendering tasks at PyMuPDF or pypdfium2, and text or table extraction at pdfminer.six or pdfplumber. What pikepdf does extract is embedded images losslessly, without re-encoding JPEGs or other compressed formats.
Does pikepdf support digitally signed encryption?
No. The page states that digital signature based encryption is not currently supported. Password protection is supported for opening and for saving, with AES-256, AES-128 and RC4 available on output, and encryption can be removed when the user password is not set.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pikepdf-pikepdf)Star history chart for your README
[](https://hysenlabs.com/projects/pikepdf-pikepdf)Was this useful?