Pipecat: every pipeline is an agent, and the base install is heavy
Open Source framework for voice agents, multimodal apps, and realtime AI. Maintained by Daily and the community.
At a glance
- What is it?
- Pipecat is a Python framework for realtime voice and multimodal agents that treats a pipeline as an agent you can hand off, fan out or distribute. That composition model is the reason to use it, and the reason to hesitate is a base dependency set that pulls in the OpenAI client and numba before you have chosen any provider.
- Who is it for?
- Pipecat fits a team building a realtime voice or multimodal product that would rather have audio, transports and AI services wired together by a framework than by hand, and that is willing to live with its dependency set and its rapid minor releases. It does not fit a project that wants a small install, because the OpenAI client and numba arrive whether or not you use them.
- Can I use it commercially?
- Yes. BSD-2-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
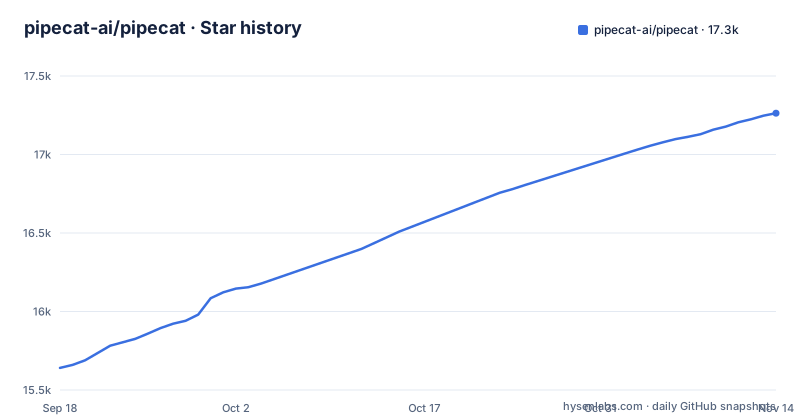
- pipecat-ai/pipecat17,263 ★ · +1,622
| Repository | 2026-09-18 | 2026-11-14 |
|---|---|---|
| pipecat-ai/pipecat | 15.6k | 17.3k |
1,622 Stars in the last 57 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A pipeline is an agent, so handoff is composition rather than a separate layer
The central design claim is that each pipeline is an agent. Multi-agent systems are not a separate subsystem you add on top; they are what you get when you compose pipelines, using handoff, parallel fan-out, sidecar workers or distributed deployments. Specialists hand off to each other, fan out in parallel, or run as sidecars over a shared bus, locally or distributed across processes and machines.
That framing has a practical benefit. A single voice assistant and a four-specialist crew are the same object at different sizes, so a simple product does not pay for the multi-agent machinery, and the handoff points appear only when you write them.
The consequence is that the hard part moves from a library concern to yours. Describing when a conversation should transfer from one specialist to another, and what each sidecar receives, is application logic the framework exposes but does not decide. The README states that agents can coordinate over a shared bus distributed across processes and machines, so confirm the bus protocol and configuration in the documentation before you design around it.
The base install already carries the OpenAI client, onnxruntime and numba
The dependency list is heavier than a voice framework's headline suggests. Three entries explain why.
    "openai>=1.74.0,<4",
    "numba>=0.61.2,<1",
    "sentencex==1.0.32",
The OpenAI client is a core dependency rather than an extra, so it installs even if you plan to use a different provider. The list also carries a packaging comment marking a dependency as required by the local smart-turn analyzer, so turn detection adds to the base install as well. numba carries the comment that it is pinned to resolve package dependencies, which makes it a compatibility pin rather than a stated feature requirement.
sentencex is pinned to an exact version. The consequence is that when those pins eventually need to move, the resolver will make you unpin something. Budget for that in environments where you also control other pinned packages.
audioop-lts appears only on Python 3.13, which is the stdlib removal surfacing
requires-python is 3.11 and newer, and several dependencies are conditional on the interpreter version, including these two (a pydantic floor also applies from 3.14). audioop-lts is marked for python_version 3.13 and above, and wait_for2 is marked for versions below 3.12.
The first of those is a direct consequence of audioop leaving the standard library in Python 3.13. A framework that does audio conversion needs a replacement there, so it pulls a backport on exactly the versions that lost the module. The second is a compatibility shim for older interpreters rather than a feature.
The consequence for you is that the dependency graph differs between interpreters in a way that is invisible until pip resolves it. On 3.11 you get wait_for2 and no audioop-lts; on 3.12 you get neither; on 3.13 and above you get audioop-lts and no wait_for2. If you pin a lock file for one interpreter and move it to another, expect the resolution to change, which is an argument for resolving per target environment rather than sharing a single lock across Python versions.
Transports are WebSockets or WebRTC, and seven client SDKs follow the protocol
Pipecat is described as voice-first, integrating speech recognition, text-to-speech and conversation handling, and as pluggable across many AI services. Real-time behaviour is delivered over different transports, with WebSockets and WebRTC given as the examples, and the project claims ultra-low latency interaction as a result.
On the client side there are official SDKs for JavaScript, React, React Native, Swift, Kotlin, C++ and ESP32. Seven platforms is a real commitment, because each one has to stay in step with whatever payload shape your pipeline emits.
The consequence is that the transport choice precedes most other decisions. WebRTC gives you a peer connection and its own signalling and NAT concerns; WebSockets keeps the media path inside your existing connection handling. Both are offered, so this is a decision you make rather than one the framework makes for you, and the choice determines which client SDK is the easiest path. Read the transports documentation and examples/transports before committing.
pipecat init hands the scaffolding to a coding assistant
The CLI ships with the package and is installed as an extra.
uv tool install "pipecat-ai[cli]"Starting a project is one command.
pipecat init quickstartWhat that does is worth reading closely, because it shapes how you get started. pipecat init sets you up so an AI coding assistant, named as Claude Code or Codex, builds the project for you, and the project states it can scaffold a runnable bot in under a minute. The CLI then monitors and deploys your agent to production.
Two consequences. The quick path assumes you already have one of those assistants installed, so a team without either is reading the generated project rather than watching it get built. And the under-a-minute figure is the project's own claim for a scaffold, not a measurement of anything you will later depend on. If you scaffold skills for Claude Code instead, the marketplace is added with the following.
claude plugin marketplace add pipecat-ai/skillsWhisker and Tail exist because a live pipeline is otherwise hard to see
Observability gets its own tools here rather than being left to logging. Whisker is described as a real-time Pipecat debugger for looking at your pipeline and processors, and Tail is a terminal dashboard for Pipecat. The repository also carries an examples/observability directory alongside turn-management, context-summarization and persistent-context.
The reason is structural. A voice pipeline is a stream of frames and turn events crossing services in real time, and the failure you need to catch is usually temporal: a turn that never started, a response that stopped mid-stream, a processor waiting on something. A request and response trace does not show that well because there is no single request.
So the practical consequence is that you should plan to run Tail beside a development bot from the first day rather than bolting on instrumentation after something misbehaves in front of a user. Worth noting that these are separate projects from this repository, which means the debugging story depends on tooling that can move on its own schedule.
Pipecat Flows moves conversation state into the framework
Structured conversations are handled by Pipecat Flows, which is built into Pipecat rather than added separately, and exists for predefined or dynamic conversation paths with state management. Examples live in examples/flows.
This is the alternative to writing the logic into a prompt. A prompt asks a model to behave like a state machine and hopes it does; a flow defines the states and the transitions, and the framework runs them. For guided flows such as intake or support, that difference is the whole point, because the conversation shape becomes something you can inspect and test.
The consequence is a shift in where your product logic lives. Turn conditions that lived in a system prompt now live in framework objects, which is more testable but also more binding, and the boundary between flow logic and pipeline processors is yours to keep straight. There is a separate examples/turn-management directory as well, which suggests both approaches coexist, so decide early whether a given conversation is a flow or a pipeline.
A LiveKit-based agent stack owns its media rooms, pipecat does not
The credible alternative in this space is a voice agent framework built on a realtime media provider, which is what LiveKit Agents is. That design starts from the provider's own infrastructure: sessions happen in LiveKit rooms, and you inherit its model for rooms, participants and connection, in exchange for a media layer that is already solved and operated.
Pipecat makes the opposite choice. It describes itself as pluggable and composable, with transports such as WebSockets and WebRTC named as the alternatives, so the media path is something you select rather than something the framework's host imposes. That is why it can also target an edge device and why client SDKs span from React to ESP32.
The trade is direct. If your architecture already standardises on one realtime media provider, going provider-agnostic buys you flexibility you will not use. If you are choosing a media stack now, pipecat's neutrality costs you the solved signalling and NAT handling that a provider gives you, and you keep ownership of that problem.
BSD-2-Clause, marked Production/Stable, shipping three minors in September
The package is pipecat-ai, licensed BSD-2-Clause, requiring Python 3.11 or newer and classified as Development Status 5, Production/Stable. It is maintained by Daily and the community, and the ecosystem around it is broad: Pipecat UI as a shadcn component registry, Pipecat Skills for Claude Code, Whisker, Tail, community service integrations with a guide in COMMUNITY_INTEGRATIONS.md, and an examples tree covering transports, RAG, MCP, video avatars and transcription.
The release cadence is the part to plan around. v1.13.0 shipped on 2026-10-19, v1.14.0 on 2026-10-24 and v1.15.0 on 2026-10-29, with the last push on 2026-11-02. Three minor releases inside a fortnight is a fast-moving surface.
The consequence is that the Production/Stable label describes release discipline rather than an API frozen in place. Pin the minor version you develop against, read CHANGELOG.md before upgrading, and expect the exact dependency pins to be part of what you manage, since they are what keeps a given install reproducible while the framework underneath moves.
Editorial conclusion
Pipecat fits a team building a realtime voice or multimodal product that would rather have audio, transports and AI services wired together by a framework than by hand, and that is willing to live with its dependency set and its rapid minor releases. It does not fit a project that wants a small install, because the OpenAI client and numba arrive whether or not you use them. Verify three things before committing: which Python you are on, since requires-python is 3.11 and newer and audioop-lts is pulled only from 3.13 upward; whether your transport matches the official clients, which cover JavaScript, React, React Native, Swift, Kotlin, C++ and ESP32; and where production deployment goes, since the documented path deploys to Pipecat Cloud while the framework itself is BSD-2-Clause and self-hostable. The package is marked Production/Stable and reached 1.15.0 on 2026-10-29 after 1.14.0 and 1.13.0 in the same month, so pin the version you develop against.
Frequently asked questions
What is Pipecat?
An open-source Python framework, distributed as pipecat-ai, for building realtime voice and multimodal conversational agents. It integrates speech recognition, text-to-speech and conversation handling into composable pipelines, and each pipeline is treated as an agent that can be combined through handoff, parallel fan-out or sidecar workers.
How do I install Pipecat?
The framework installs as pipecat-ai on Python 3.11 or newer. To get the command line tools as well, install the extra with uv tool install "pipecat-ai[cli]", then run pipecat init to start a project.
Is Pipecat open source?
Yes, it is an open-source Python framework under the BSD-2-Clause licence, maintained by Daily and the community. The package is marked Production/Stable and its source is published on GitHub with the documentation at docs.pipecat.ai.
Is Pipecat free?
The framework itself is free and BSD-2-Clause licensed. Pricing for the hosted Pipecat Cloud deployment service is something you would need to confirm separately.
What is Pipecat Cloud?
It is a deployment target named in the README: the Pipecat Skills for Claude Code can scaffold projects and deploy to Pipecat Cloud. Check the documentation for what the hosted service provides and how it is priced.
Official sources
Where this project is recommended
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Scaling Voice Agents to 10K+ Calls: Jarvis’s 3 Biggest Challenges: Part 1dev.to · Oct 18, 2026 · 3 points · 4 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pipecat-ai-pipecat)Star history chart for your README
[](https://hysenlabs.com/projects/pipecat-ai-pipecat)Was this useful?