Pixeltable: multimodal tables, computed columns and HTTP services
The unified multimodal backend for AI data apps. Database, orchestration, and serving in one Python file.
At a glance
- What is it?
- Pixeltable combines multimodal storage, computed columns, search indexes and HTTP routes in a Python application. Its quickstart separates catalog schema updates from starting or updating the service.
- Who is it for?
- Pixeltable suits teams that want one file to review instead of four systems, and the split between pxt schema update and pxt service update is worth learning before anything else because running only one half looks like a broken install.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
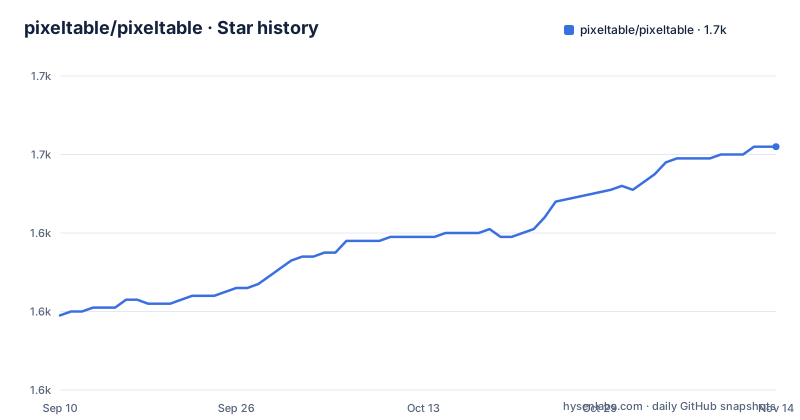
- pixeltable/pixeltable1,662 ★ · +43
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| pixeltable/pixeltable | 1.6k | 1.7k |
43 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Deployment is two commands that each do half the job
The whole quickstart is five lines:
pip install 'pixeltable[serve]'
pxt init
pxt service example --out app.py
pxt schema update app.py my_app
pxt service update app.py my_app
The two update commands are then defined in terms of what each one refuses to do. `pxt schema update` creates the catalog `my_app` and its tables, and it does not start HTTP. `pxt service update` starts HTTP, and it does not create tables. Nothing in the sequence links the two, so the order is load bearing: schema first, then service, or the service has no tables to mount and the schema step leaves you with a catalog and no listener. `pxt service example` is what writes `app.py` in the first place, so the file you then edit twice is generated output, not a hand written module. The `[serve]` extra is what pulls in the serving layer, since the base install is the database alone.
The current example computes and returns a video summary
The upstream skill documents the shape generated by `pxt service example`: its `Docs` model declares `summary = excerpt(title)`, and the insert route explicitly includes `Docs.summary` among its outputs. Therefore a response with a `summary` field matches the documented model; the previous claim that the field was undeclared arose from an incomplete excerpt.
The current Pixeltable README also shows a separate video application with a computed summary and a route that returns it. Check the generated file and serving documentation for the exact version in use.
Input and computed columns in the video model
The current `Videos` model declares `video: pxt.Video` as the inserted input. Computed columns extract audio, transcribe it and summarize the transcript; an embedding index supports similarity search over summaries. This shows how Pixeltable connects stored media, model calls and derived data rather than requiring the application to update each layer separately. Model calls and indexing incur their own provider and resource costs.
The upstream example shows a complete data pipeline
The README contains a complete application example: it declares a `Videos` table, derives audio, transcription and summary columns, builds an embedding index, and registers insert and search routes. It then gives commands to initialize the project, update the schema and start the service.
The earlier claim that the upstream code and link definitions stopped mid-sentence came from an incomplete excerpt, not the full README. Use the current upstream example when implementing this flow.
pxt serve is gone, and two ways of making a table still coexist
The page names its own stale documentation. If an agent writes `create_table` in application code, names the file `schema.py`, or reaches for `pxt serve`, then the installed skill is out of date and has to be reinstalled with `npx skills add pixeltable/pixeltable-skill`. Three signals, one remedy. `pxt serve` is described as removed outright, so it is a real command that used to exist rather than a typo. Underneath that sits a genuine split in the API: notebooks and tests are still expected to call `pxt.create_table()`, while an application is supposed to put its tables in `app.py` and let `pxt schema update` create them. The same table therefore has two creation paths depending on where the code lives, and the agent instruction files are what keep an editor on the right one.
Endpoint discovery reads the first entry and needs jq on the path
Ports are assigned rather than fixed, and the guidance is to read one back instead of hardcoding it. The command given is `pxt service list --json` piped into `jq` to pull `.[0].endpoint`, which works for the single service case the quickstart creates. It indexes position zero rather than matching a name, so as soon as a project carries more than one service the URL you get back is whichever one the CLI happened to list first. Two smaller costs come with the same line: the output has to be JSON and the extraction needs `jq` on the machine. The alternative offered for people who do not want endpoints at all is to run `pxt schema update`, insert from Python, then `export_sql`, which gives you the data without the serving layer.
A limited beta banner, an org provisioning step and a URI shaped catalog name
The hosted path starts with a banner saying the cloud is in limited beta, with an email address rather than a signup flow. Past `pxt login`, the documented check is `pxt org list`, and if nothing comes back then `pxt org create NAME` provisions the organization together with a database called `main`. From there the catalog argument stops being a bare name and becomes a URI, which is why the quickstart above passes `my_app` and the cloud example passes `pxt://org:main`. The URI is written into the project file as a TOML table before anything is deployed:
[[pixeltable.database]]
name = 'pxt://org:main'
Then the same three commands repeat with the new target, `pxt db update pxt://org:main`, `pxt schema update app.py pxt://org:main`, `pxt service update app.py pxt://org:main`. The read only constraint is stated for the MCP side rather than the CLI: the hosted cloud MCP reads your signed in organization over OAuth and does not deploy or change resources, which is the point at which you reach for the command line instead.
Two documentation toolchains and a conda instruction next to a uv toolchain
The root listing holds `mkdocs.yml` and a `docs/` directory, while the build file pins `MINTLIFY_VERSION := 4.2.506` and its `docs` target is described as building mintlify documentation. Two documentation pipelines, one repository. The build file is also where the odd pins live: `FFMPEG_VERSION := 6.1.1=gpl*`, `CMAKE_POLICY_VERSION_MINIMUM := 3.5` kept necessary for onnx to compile, and `CMAKE_ARGS := -DLLAVA_BUILD=OFF` for the LLaMA build on some Linux systems. The `help` target tells you that you must be in a conda environment to install the development environment, while the variables around it are all uv, with `UV_VERSION := 0.12.3` and `--group extra-dev` added to `UV_ARGS`, plus a `--group cuda-dev` group switched on by probing for `nvidia-smi`. The default goal is `help`, so a bare `make` prints instructions rather than doing anything.
Editorial conclusion
Pixeltable suits teams that want one file to review instead of four systems, and the split between pxt schema update and pxt service update is worth learning before anything else because running only one half looks like a broken install. Verify two things before committing: that your response schema matches the columns you declared, since the shipped example returns a summary the class does not define, and that your endpoint discovery handles more than one service, because the documented command reads the first entry rather than the one you started. For the agent workflow, check which instruction file your editor actually reads, since AGENTS.md, CLAUDE.md and a separately installed skill are three different channels.
Frequently asked questions
What is the difference between pxt schema update and pxt service update?
pxt schema update creates the catalog and its tables and does not start HTTP. pxt service update starts HTTP and does not create tables. Running only one of the two leaves you with half a deployment, so the order matters.
How does Pixeltable tell you which port the service is on?
The port is assigned rather than fixed, and the documented way to read it is pxt service list --json piped into jq to take the endpoint at position zero. That takes the first listed service, not a service matched by name.
Which command tells me my installed Pixeltable skill is out of date?
Writing create_table in application code, naming the file schema.py, or using the removed command pxt serve are the three signals given. The remedy is to reinstall with npx skills add pixeltable/pixeltable-skill.
Does Pixeltable Cloud need an API key to insert rows?
In the chat app copied by uvx pixeltable-new, inserting into the knowledge table needs no API key. The /ask route is the part that needs ANTHROPIC_API_KEY.
How do I point a Pixeltable project at a cloud database?
Add a [[pixeltable.database]] entry with the name pxt://org:main to the project file, then run pxt db update against that URI before repeating the schema and service updates. pxt org create NAME is what provisions the organization and its database called main.
What Python versions does Pixeltable support?
The project metadata requires Python 3.11 or newer, and the classifiers list 3.11, 3.12, 3.13 and 3.14. The licence is Apache 2.0 and the version string is dynamic rather than fixed in the project file.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pixeltable-pixeltable)Star history chart for your README
[](https://hysenlabs.com/projects/pixeltable-pixeltable)Was this useful?