OpenKB: a compiled wiki, a dev-pinned retriever, and a web server with auth off by default
OpenKB: Open LLM Knowledge Base
At a glance
- What is it?
- OpenKB is a command line system that compiles documents into a wiki of Markdown pages with cross-links instead of querying a vector store at query time, using PageIndex tree indexing for long PDFs. Its dependency file is pinned to exact versions with the reasons for the policy and for key pins written next to them, and the bundled web interface ships with authentication off.
- Who is it for?
- OpenKB fits a researcher or small team with a folder of papers and notes who wants a reviewable body of knowledge on disk rather than an index they cannot read, and who is willing to accept compilation cost and an alpha-stage tool. It does not fit a corpus that changes hourly, since a single source can touch ten to fifteen pages, and it does not fit anyone exposing the web interface without turning on a token first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 115 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
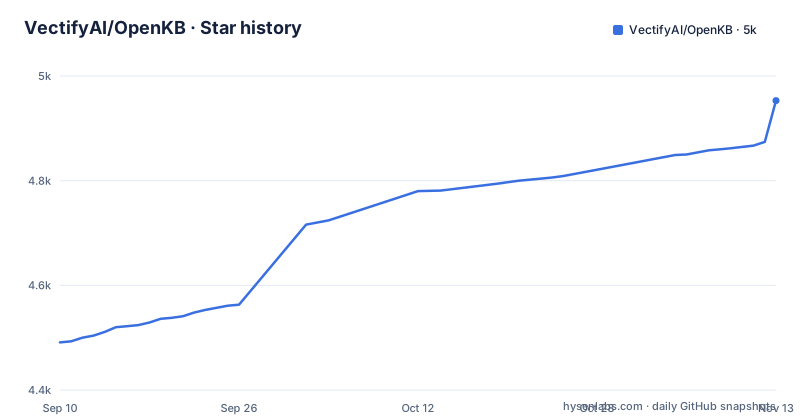
- VectifyAI/OpenKB4,953 ★ · +462
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| VectifyAI/OpenKB | 4.5k | 5k |
462 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Auth is off by default on the bundled web server
The Knowledge Workbench is a web interface the REST API serves at `/`, and installing it is an extra:
pip install "openkb[web]"
openkb-web
That starts the API and the Workbench together on `http://127.0.0.1:7566/`. The interface browses the knowledge base, uploads and compiles documents, and streams queries and chats, all in the browser.
Now the part to read twice. Auth is off by default, described as local-first, and you set `OPENKB_API_TOKEN` to require a bearer token before exposing the server. A loopback bind address is what makes that default defensible; the same process reachable from a network is an unauthenticated interface that can compile your documents and read your wiki.
The environment template shows the rest of the server surface. `OPENKB_API_TOKEN` is the token clients send as an Authorization bearer header, and `OPENKB_KB_ROOT` is where the REST `/init` endpoint creates knowledge bases, defaulting to `~/.config/openkb/kbs`. An optional `OPENAI_API_BASE` covers OpenAI-compatible gateways.
The frontend is ordinary enough to work on: `cd frontend && npm install && npm run dev` proxies `/api` to a running `openkb-web`, and `npm run build` regenerates the bundled copy under `openkb/web/`.
Every pin is exact, and the reason is in a comment
The dependency list is unusual and worth reading in full:
"pageindex==0.3.0.dev3",
"markitdown[docx,pptx,xlsx,xls]==0.1.5",
"trafilatura==2.0.0",
"litellm==1.87.2",
"openai-agents==0.17.3",
"openai==2.44.0",
Not one of them is a range, and the comment above the list explains why: all dependencies are pinned exactly out of supply-chain caution, citing the litellm package-poisoning incident, with the instruction to bump deliberately after vetting each release.
Two pins carry their own explanations, which is the part worth knowing. `litellm` is held at 1.87.2 because that version fixes the `chatgpt/*` provider returning empty Responses output and auto-injects GitHub Copilot IDE-auth headers. `openai` is held at 2.44.0 because 2.45.0 added a required `cache_write_tokens` field to `InputTokensDetails` that `openai-agents` 0.17.3 does not set, which crashes usage parsing on every response. The comment says to stay below 2.45 until openai-agents catches up.
That is a project telling you what its known breakages are. The cost is equally plain: upgrading anything means a deliberate edit, because there is no resolver doing the work for you.
One more detail deserves a flag. The retriever itself is pinned to `pageindex==0.3.0.dev3`, a development build, so the retrieval layer under the whole system is an exact-pinned prerelease.
Twenty pages decides which code path you get
There is a threshold, and it is a page count rather than a file size:
| | Short documents | Long documents (PDF at least 20 pages) | | --- | --- | --- | | Convert | markitdown to Markdown | PageIndex tree index and summaries | | Images | extracted inline by pymupdf | extracted by PageIndex | | LLM reads | full text | document trees | | Result | summary and concepts | summary and concepts |
Short documents are converted to Markdown and read end to end by the model. A long PDF is processed by PageIndex into a hierarchical tree index, and the model reads that tree instead of the full text, which is what makes long document retrieval accurate without a vector database.
The output is the same either way, which is reassuring. The behaviour is not identical, and a nineteen-page and a twenty-one-page PDF take different routes through the system, including different image handling.
The formats accepted on input are wider than PDF: PDF, Word, Markdown, PowerPoint, HTML, Excel, CSV, plain text and URLs, with trafilatura among the pinned dependencies for the URL path.
One source can touch ten to fifteen wiki pages
This is where the cost model lives. When you add a document, the LLM does five things in order: it generates a summary page, reads the existing concept and entity pages, creates or updates concepts with cross-document synthesis, creates or updates entity pages for people, organisations, places and products, and finally updates the index and the log.
The stated consequence is that a single source might touch ten to fifteen wiki pages, and that knowledge accumulates because each document enriches the existing wiki rather than sitting in isolation.
That is the mechanism behind the project's argument with retrieval-augmented generation. Traditional RAG rediscovers knowledge from scratch on every query and nothing accumulates; OpenKB compiles once into a persistent wiki and keeps it current, so cross-references already exist, contradictions are flagged, and synthesis reflects everything consumed so far.
It is also why the bill is not proportional to what you added. Compilation reads existing concept and entity pages, so the cost of the hundredth document depends on how large the wiki already is. For a corpus that changes constantly, that is the wrong shape, and no amount of prompt tuning changes it.
The output is markdown you can read and diff
The wiki is plain `.md` files with cross-links, which means it opens in Obsidian for a graph view and it opens in a text editor for everything else. There is no proprietary store to query and no format to convert out of.
The newer additions push in the direction of interop rather than lock-in. Wiki pages follow the Google Open Knowledge Format specification for knowledge sharing, and entity pages for people, organisations, places and products are extracted automatically and kept in sync, so those pages are structured data rather than prose that happens to mention a name.
The rest of the output layer is three commands. `openkb query` takes a one-off question, `openkb chat` runs a multi-turn conversation with persisted sessions you can resume, and `openkb visualize` is listed as an optional output command.
For a team this matters more than it sounds. A knowledge base compiled by a model that writes files can be reviewed in a pull request, corrected by hand, and diffed when behaviour changes, none of which is possible against a vector index.
The wiki has a second output aimed at agents
The Skill Factory is the part that goes beyond reading. It distills redistributable agent skills from the wiki, and the quick start shows the shape of one:
openkb skill new my-expert "Reason like an expert on <your-topic>"So the same compilation that produces human-readable concept pages also produces something you can hand to an agent, which means the knowledge base has two consumers rather than one.
The repository is arranged for that. There is a `skills/` directory at the top level, and a `.claude-plugin/` directory, which is how the project packages itself as a Claude plugin. The `examples/` tree has dedicated directories for `chat/`, `commands/`, `configuration/`, `docs/`, `pageindex-cloud/`, `rest-api/`, `skills/`, `slides/` and `visualize/`, with a README at its root.
There is also an `openkb-web` REST path and a `pageindex-cloud` example, so the same knowledge base can be driven from code rather than the command line.
The two-layer description from the README is the cleanest way to hold all of this: a wiki foundation that compiles and maintains knowledge, and generators, meaning query, chat and Skill Factory, that turn it into output.
Three install routes and one model string
Installation is a single line from PyPI:
pip install openkbThere is also `pip install git+https://github.com/VectifyAI/OpenKB.git` for the latest from GitHub, and the editable route for development, which is a clone, a `cd OpenKB` and `pip install -e .`. The project requires Python 3.10 or later and its classifiers cover 3.10 through 3.13.
The first run is five commands. Make a directory, `openkb init`, then add documents by file, by whole directory or by URL, then `openkb query` or `openkb chat`.
Choosing a model is where configuration lives. OpenKB routes through LiteLLM, so any supported provider works, and you set the model during `openkb init` or in `.openkb/config.yaml` using the `provider/model` format, for example `anthropic/claude-sonnet-4-6`. OpenAI models may omit the prefix, so `gpt-5.4` is enough.
The key goes in a `.env` file:
LLM_API_KEY=your_llm_api_keyOne exception is handled for you. Subscription providers that authenticate through an OAuth device flow, such as `chatgpt/*` and `github_copilot/*`, need no API key, and OpenKB skips the missing-key warning for them rather than sending you looking for a credential that does not exist.
Alpha at version 0.4.5, last pushed in July
The classifier in the project metadata says Development Status 3, Alpha, and the version is 0.4.5. Both are true at once, and the second tells you how much to trust the first.
The releases are v0.4.4-rc1 on 2026-07-10, v0.4.4 the same day, and v0.4.5 on 2026-07-20. The last push to the repository is dated 2026-07-22, so the code has been sitting for more than three months. The version itself is declared as dynamic in the project metadata, which means it is derived from git tags by the VCS build backend rather than typed into a file.
For a tool whose value is a compiled artifact you keep, a gap of several months matters less than it would for a library, and the pinned dependency set means an old install keeps working exactly as it was.
The rest of the tree is conventional: `openkb/` for the package, `tests/`, `docs/`, `assets/`, `frontend/`, a `config.yaml.example` to copy, a `uv.lock` so the project itself is developed with uv, and both `AGENTS.md` and `CLAUDE.md` at the root alongside the Claude plugin directory.
The licence is Apache 2, stated in the project metadata rather than only in the file, with the authors listed as Kylin and Ray.
Editorial conclusion
OpenKB fits a researcher or small team with a folder of papers and notes who wants a reviewable body of knowledge on disk rather than an index they cannot read, and who is willing to accept compilation cost and an alpha-stage tool. It does not fit a corpus that changes hourly, since a single source can touch ten to fifteen pages, and it does not fit anyone exposing the web interface without turning on a token first. Verify two things before you start: which LLM you point it at, because compilation reads and rewrites existing pages and the bill follows the wiki's size rather than the new document's, and that `OPENKB_API_TOKEN` is set before the server leaves localhost.
Frequently asked questions
What is OpenKB?
OpenKB is an open-source command line system that compiles raw documents into a structured, interlinked wiki-style knowledge base using LLMs, with PageIndex providing vectorless, reasoning-based retrieval for long documents. The wiki output is plain Markdown files with cross-links.
Does OpenKB need a vector database?
No. The stated design is no vector database, and long document retrieval runs through PageIndex tree indexing, where the model reads a hierarchical tree index instead of the full text.
Which LLM providers can OpenKB use?
Any LiteLLM-supported provider. You set the model in `provider/model` form such as `anthropic/claude-sonnet-4-6`, with the prefix omittable for OpenAI models like `gpt-5.4`, and put the key in `LLM_API_KEY` in a `.env` file. OAuth device flow providers such as `chatgpt/*` and `github_copilot/*` need no key.
Is the OpenKB web interface protected by authentication?
Not by default. Auth is off by default because the server is local-first on `http://127.0.0.1:7566/`, and you set `OPENKB_API_TOKEN` to require a bearer token before exposing the server.
How does OpenKB handle long PDFs?
PDFs of twenty pages or more go through PageIndex into a hierarchical tree index with summaries, and the model reads the tree. Shorter documents are converted to Markdown with markitdown and read in full, with images extracted inline by pymupdf.
Why are all OpenKB dependencies pinned exactly?
The project metadata cites supply-chain caution and the litellm package-poisoning incident, and records two specific fixes: litellm 1.87.2 for the chatgpt/* provider returning empty Responses output, and openai held below 2.45 because 2.45.0 added a required cache_write_tokens field that openai-agents 0.17.3 does not set.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vectifyai-openkb)Star history chart for your README
[](https://hysenlabs.com/projects/vectifyai-openkb)Was this useful?