OpenAI4S declares zero dependencies, and its own kernel inherits whatever your virtualenv has
Replicate Claude Science using the 9.9-yuan Doubao API
At a glance
- What is it?
- PKU-YuanGroup/OpenAI4S is an MIT-licensed hybrid research agent that keeps JSON tool calls as one control plane and persistent Python and R kernels as the other. Its sandbox boundary, its version metadata and its own skill count do not line up.
- Who is it for?
- Read it as an agent that runs code with your environment's privileges rather than inside an isolated one, because the kernel is spawned from your own interpreter and sees every package you have installed. Before a first run, set the access token expectation correctly, since the loopback opt-out that used to skip it is gone in v0.3.0, and read the upgrade note, as the schema moves from 27 to 32.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
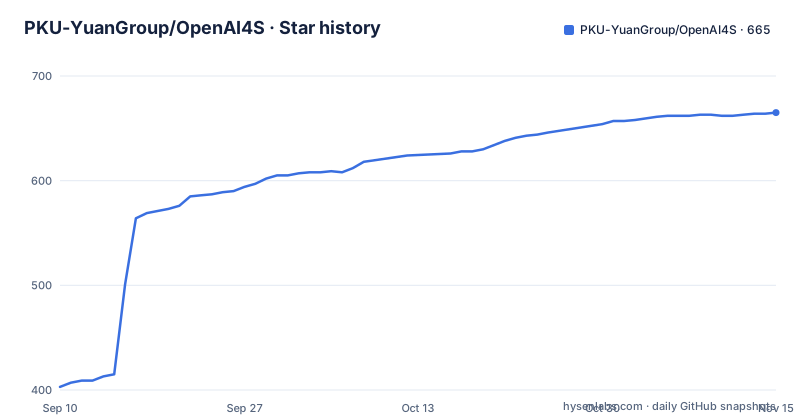
- PKU-YuanGroup/OpenAI4S665 ★ · +262
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| PKU-YuanGroup/OpenAI4S | 403 | 665 |
262 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The kernel is your virtualenv, and nothing is declared as a dependency
The package manifest ships an empty dependency list with a comment explaining that this is deliberate, that the agent is pure standard library by design and that its language model client talks HTTP through urllib. The consequence is stated in the same file, in a comment above the science extra: the kernel is spawned with sys.executable, so anything present in the active virtualenv is visible to agent cells. That is the whole isolation story, and it is worth being blunt about what it means. Cells written by a model see the packages you installed and the versions you pinned, and the optional extra is only a convenience:
uv sync --extra scienceThe extra adds numpy, pandas, matplotlib and scikit-learn, and the comment notes that every one of those imports in the tree is already guarded by a try/except ImportError, so the core runs whether or not they exist. The tradeoff is deliberate in the other direction too: no transitive dependency can be pulled in by an agent, at the price of no hardened runtime underneath it.
R has no in-cell completion signal, while Python has host.submit_output
The architecture is two planes, and the comparison table makes the asymmetry explicit. The JSON control plane handles workflow, permissions, metadata, services and human approval; its action unit is one ordered native tool batch, its state is an append-only action ledger, and its completion signal is a strictly structured finalize_response action owned by the engine. The science plane handles computation, analysis and simulation; its action unit is one complete code cell, its state is kernel memory plus versioned artifacts, and its composition is ordinary control flow plus libraries. Python cells can call the in-kernel host API synchronously while they run and complete with host.submit_output(...), which is the only completion signal that can fire inside a cell. R is listed as an independent persistent channel with no in-cell completion at all. An R-heavy workflow therefore has to close through the engine's own action rather than from the cell, which is the single biggest structural difference between the two languages here.
The compose file publishes one port to loopback and explains why in a comment
The container deployment is single node, and its port mapping is not a default:
docker compose up -d --build
docker compose exec openai4s openai4s url
The published mapping is 127.0.0.1 on the host for port 8760, and the comment above it says why in unusually direct language. Publishing 0.0.0.0 on that port would expose a code execution surface on every interface of the machine, with a single bearer token standing between the internet and the endpoint that executes code. The daemon's own posture is loopback, and containerising it that way is what preserves that posture, with the suggested routes being an SSH tunnel or a TLS reverse proxy that is the only thing actually published. A second comment explains the fixed container name: it exists so that the documented `docker logs openai4s` commands work as written, at the cost of allowing only one instance per engine, described as one machine and one workbench.
The access token cannot be turned off, and credentials never touch the volume
Two security decisions are recorded in the image comments rather than in a settings file. The first is that the access token is mandatory and unremovable on every bind, minted through the gateway's local_auth load_or_mint path, and the comment is explicit about why the token rather than the Host header allowlist is the real control: a wildcard bind necessarily turns the allowlist off. The second is the secret backend. Credentials arrive as environment variables named with an OPENAI4S_SECRET scope and name pattern, and nothing credential shaped is ever written to the data volume, which the comment calls stronger than a keychain a container cannot have. It also records the alternative it rejected: an auto-detecting backend would fail closed here, correctly, but that means a SecretStoreUnavailable traceback before the startup banner on every boot for a migration with nothing to migrate. The volume itself holds the database, artifacts, session workspaces, user skills, a checkpoint store and the token, so losing it loses every session.
The skill library is counted three different ways
The number of skills moves across the document without converging. The open-sourcing entry lists 24 science skills. The v0.2.0 entry says a pinned 561 recipe bioSkills collection brought the total to 603, installable anywhere through npx. The v0.3.0 entry says a single-cell RNA analysis skill brings the total to 604. The npm package that installs them, @pku-yuangroup/openai4s-skills at version 0.3.0, describes itself in its own manifest as 606 scientific recipes. Nothing reconciles 603, 604 and 606, and a user deciding whether their recipe collection is current has to guess which figure describes the tree in front of them. The same manifest is interesting for another reason: it declares no runtime dependencies at all, one dev dependency, a pinned Playwright, and a single test script that runs one self-test file, while its file list ships the entire skills directory of Python recipes.
The classifiers name two operating systems, and the third platform shipped anyway
The Python manifest advertises macOS and POSIX Linux and no others, which is a shorter list than the releases actually delivered. The v0.2.0 entry describes an Apple Silicon disk image and a relocatable Linux x86_64 tarball, with the Windows and WSL2 package built but still under stabilization. The v0.3.0 entry is the one that ships it, describing the first Windows and WSL2 zip beside the Linux tarball, and in the same sentence noting that the Apple Silicon macOS image is an ad-hoc-signed preview rather than a notarized one. So the packaging metadata predates the release history and was not updated with it. The same file also carries Development Status 3 - Alpha across three tagged releases, a workbench rewrite, a schema migration and a benchmark suite, which is a conservative label rather than a wrong one, but it is the label a package index will show.
Python 3.10 is declared, and the science extra cannot be satisfied there
The manifest requires Python 3.10 or newer and the classifiers claim support for 3.10 through 3.14. The comment above the extra groups explains why the floor is really higher for the science stack. CPU-first single cell workflows need Python 3.11, because PyDESeq2 0.5.4 raised its own floor. Pertpy 1.0.3 is described as the newest release compatible with both that floor and Scanpy 1.11.5, and Pertpy 1.1.1 requires Python 3.12 outright. So on 3.10 the declared requirement holds and the science extra does not, and a resolver on that interpreter will find a combination that cannot be satisfied. The listing also skips Windows in the environment classifiers while the release notes describe a Windows package, which is the second place where this file and the news entries disagree.
Three Python packages in one tree, and a schema that moves from 27 to 32
The repository root holds three separate Python packages, openai4s, openai4s_compute_provider and openai4s_worker_runtime, which lines up with the bring-your-own-compute claim in the open-sourcing entry, alongside frontend for the workbench, plus workflows, harness, envs, deploy, skills, tools, tests and docs directories, and two shell entry points. The workbench itself changed shape in v0.3.0, where a Preact and TypeScript interface replaces an app.js monolith as the default UI. The same release tightened the local daemon: every local daemon now requires its access token, and the OPENAI4S_REQUIRE_TOKEN=0 loopback opt-out that used to skip it is gone. Database schema 27 to 32 follows in the same entry, with a pointer to an upgrade guide for 0.2.x readers and an instruction to read it before the first start, which is the kind of migration note that belongs in a release and rarely does.
Editorial conclusion
Read it as an agent that runs code with your environment's privileges rather than inside an isolated one, because the kernel is spawned from your own interpreter and sees every package you have installed. Before a first run, set the access token expectation correctly, since the loopback opt-out that used to skip it is gone in v0.3.0, and read the upgrade note, as the schema moves from 27 to 32. For a cheap trial the documented path is the Doubao provider on the cheapest Volcengine Ark plan, and for distribution note that the skill count differs between the news entries and the npm package description.
Frequently asked questions
Does OpenAI4S need any third-party Python packages?
No. Its manifest declares an empty dependency list and builds its language model client on urllib, so the core runs on the standard library alone. The optional science extra adds numpy, pandas, matplotlib and scikit-learn, installed with `uv sync --extra science`.
Which platforms does OpenAI4S ship a desktop package for?
Version 0.2.0 added an Apple Silicon disk image and a relocatable Linux x86_64 tarball, and version 0.3.0 added the first Windows and WSL2 zip. The macOS image is described as an ad-hoc-signed preview rather than a notarized one.
How does OpenAI4S handle Python and R differently?
Python cells run in persistent kernels, can call the in-kernel host API while running, and signal completion with host.submit_output(...). R is an independent persistent channel with no in-cell completion, so it closes through the engine-owned finalize_response action instead.
What is the cheapest way to run OpenAI4S according to its documentation?
The documentation points at the Doubao provider on the cheapest Small plan of Volcengine Ark, at ¥9.9 per month or roughly US$1.4, selected by choosing the `ark` provider in the interface, on the argument that no expensive frontier model key is needed.
What changed in OpenAI4S 0.3.0 for existing installs?
The default interface moved from an app.js monolith to a Preact and TypeScript workbench, every local daemon now requires an access token because the OPENAI4S_REQUIRE_TOKEN=0 opt-out was removed, and the database schema moves from 27 to 32, with an upgrade guide for 0.2.x to read first.
How does the OpenAI4S container avoid exposing code execution on the network?
The compose file publishes 127.0.0.1 for the daemon port rather than 0.0.0.0, and its comments say the image binds all interfaces only inside the container namespace. The access token is mandatory and unremovable on every bind, and credentials arrive as environment variables rather than being written to the data volume.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pku-yuangroup-openai4s)Star history chart for your README
[](https://hysenlabs.com/projects/pku-yuangroup-openai4s)Was this useful?