pony's setup.py still describes a directory tree that is gone
Pony Object Relational Mapper
At a glance
- What is it?
- A Python object-relational mapper that parses generator expressions into SQL, where two releases landed a day apart in August 2024 and the next did not ship until August 2026, the packaging keeps two long descriptions in two formats, and one of them links a directory layout the repository no longer uses.
- Who is it for?
- pony is a good fit if you want queries written as Python and the generated SQL visible while you work, because the error messages name the exact part that failed and the translation is done per database dialect. Two things to know before you adopt it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 104 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
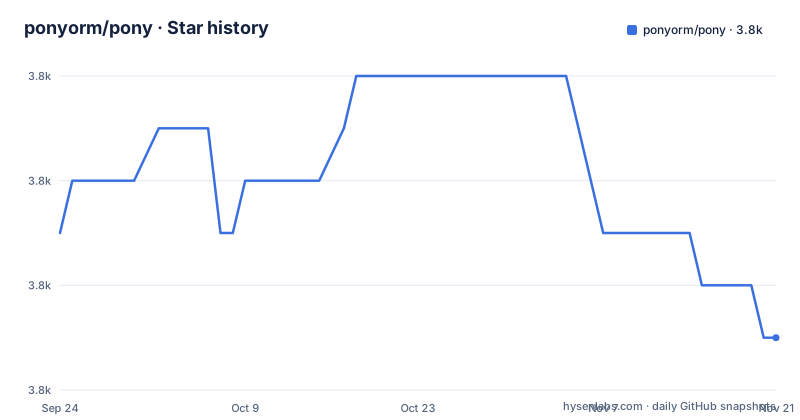
- ponyorm/pony3,815 ★ · -2
| Repository | 2026-09-24 | 2026-11-21 |
|---|---|---|
| ponyorm/pony | 3.8k | 3.8k |
-2 Stars in the last 58 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two releases a day apart, then a two year gap
The three most recent releases tell the whole story. v0.7.18 went out on 2024-08-26 and v0.7.19 on 2024-08-27, one day apart, which reads like a pair of patch releases pushed in a hurry. Then nothing until v0.7.20 on 2026-08-09. The last commit to the default branch is dated 2026-08-10, the day after that tag. So the project spent a single afternoon cutting two versions and then sat on a zero point seven line for two years. The manifest also marks its development status as Beta, and the version number is still zero seven after all of that, so there is no signal in the numbering that tells you anything about the change.
The query is Python source that gets parsed, not a string
The mechanism is stated once and everything else follows from it: Pony writes queries using Python generator expressions and lambdas, analyses the abstract syntax tree of the expression, and translates it into SQL. The example is a single line.
select(p for p in Product if p.name.startswith('A') and p.cost <= 1000)So there is no query builder DSL and no string interpolation: the filter is an ordinary Python expression over entity attributes, and the translation step is what turns it into SQL. Four database engines are named, and the page notes that each query is translated using the specific dialect of the engine being talked to, which is the part that makes one query line portable across four databases at all.
Two long descriptions in two formats, one pointing at a dead tree
There are two packaging manifests and both carry a long description. The modern one reads the readme file and declares its content type as Markdown. The legacy script carries its description inline as reStructuredText, complete with section underlines and a literal block introduced by a double colon. The two formats disagree, and the modern manifest wins when both are present, so the reStructuredText copy is rendered by nobody. It is also out of date in a way you can see: its links point into an `orm` subdirectory of the package, which is the layout the repository used before it flattened. The readme's own example link has the same problem in a different form, because it pins a branch called `orm` rather than the default branch.
The version is derived twice, by two different mechanisms
One line in the package's initialisation file holds the version, and both manifests go and get it. The modern manifest declares the version dynamic and points setuptools at the package attribute. The legacy script does the same job with a regular expression over the same source file.
version_match = re.search(
    r'^__version__ = ["\']([^"\']+)["\']',
    version_file.read_text(encoding="utf-8"),
    re.MULTILINE,
)
And if the pattern does not match, that script stops the build with a plain runtime error saying it cannot find the version. So a formatting change to one line in the package breaks packaging, and the error message gives no hint about which line or which pattern.
The test package ships in the wheel
The package list is written out by hand rather than discovered, and it is worth reading what is in it.
packages = [
    "pony",
    "pony.flask",
    "pony.flask.example",
    "pony.orm",
Two of those are not the library. A web framework integration is shipped, and so is its example package, complete with a separate table mapping HTML templates into it as package data. Deeper in the list sits the test package itself, which means the test suite is installed alongside the code. Alongside all this, package data inclusion is switched off explicitly, while a manifest file for source distributions still sits in the root. So the packaging has a hand-maintained list, an off switch for automatic data inclusion, and a leftover from before the list existed.
The claimed benefits are all about seeing what the generator did
There are five, and four of them are about legibility rather than capability. Compact entity definitions, a concise query language, being able to work with it interactively in a Python interpreter, comprehensive error messages that show the exact part where an error occurred in the query, and displaying the generated SQL in a readable format with indentation. Read together they describe a code-generating mapper whose main design goal is that when it goes wrong it tells you where, and when it goes right it shows you the statement. The stated payoff is that the developer works on business logic instead of on the mapper, which is a fair description of what an ORM is for and an unusually candid way to put it. The interpreter point deserves reading twice, because it is a design commitment rather than a convenience: a query can be typed at a prompt, mistyped, corrected and rerun without restarting anything, which is not true of most mappers and is presumably why the error messages name the failing part.
The diagram editor is a hosted tool and the docs are a third repository
The project points at a browser tool for drawing a database diagram, generating either entity declarations or a SQL script from it, and then querying the result. It also keeps its documentation in a separate repository and routes documentation questions and pull requests there rather than to this one's tracker, which means the code tracker and the prose tracker are two different places. Both copies of the description also carry the same misspelling in a heading, the tool's name written as Entity-Relationship rather than Relationship. Small, but it is in both copies, which tells you the two descriptions were copied from each other rather than maintained separately.
Development is a requirements file and two pairs of ruff invocations
The contributor instructions are short.
python -m pip install -r requirements-dev.txtSo development dependencies live in a requirements file at the root rather than in an optional group in the manifest. Then the page draws a distinction most projects skip: one pair of commands is described as formatting the code and applying safe lint fixes, and another pair is described as checking the code without changing any files.
python -m ruff check .
python -m ruff format --check .
A test runner script sits at the root as well, and the repository has been carrying a copyright notice since 2013, with the current year in it.
Editorial conclusion
pony is a good fit if you want queries written as Python and the generated SQL visible while you work, because the error messages name the exact part that failed and the translation is done per database dialect. Two things to know before you adopt it. The release history is two versions a day apart in August 2024 followed by a two year gap, so pin a version rather than tracking the branch. And the packaging carries two long descriptions in two formats, one of which still describes a directory layout the repository no longer has, so read the manifest rather than the legacy script.
Frequently asked questions
Is a female horse called a pony?
Not what this repository is. Pony is an object-relational mapper for Python that writes queries as Python generator expressions, analyses the syntax tree of the expression and translates it into SQL.
Does pony mean horse?
No. The name here is a Python object-relational mapper supporting SQLite, MySQL, PostgreSQL and Oracle, translating each query using the specific dialect of the database it is talking to.
How do I install pony?
With pip install pony, from the package index. The build backend is setuptools, the supported Python range runs from 3.10 up to but not including 3.15, and the version number is read from an attribute inside the package rather than being written in the manifest.
What databases does Pony support?
Four, named on the page: SQLite, MySQL, PostgreSQL and Oracle. Queries are translated using the specific dialect of each engine rather than a lowest common denominator, which is what makes one query line portable across all four.
How do I write a query in Pony?
As a generator expression passed to select, over entity classes, with ordinary Python expressions as the filter. The example on the page selects products whose name starts with a given letter and whose cost is at or below a threshold.
How do I run Pony's tests?
The repository carries a test runner script at its root and a development requirements file. The documented development steps install that file with pip, then run the linter and formatter through the Python module interface, once with fixes applied and once in check-only mode.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ponyorm-pony)Star history chart for your README
[](https://hysenlabs.com/projects/ponyorm-pony)Was this useful?