The weights are non-commercial and the CPU ceiling is 5000 samples
⚡ TabPFN: Foundation Model for Tabular Data ⚡
At a glance
- What is it?
- TabPFN is a foundation model for tabular data behind a scikit-learn shaped API, with the checkpoint downloaded on the first fit call. The code is Apache 2.0 and the weights are not, the dependency list caps skrub because its minor releases change transformer behaviour, and the CPU path is limited to a few thousand samples while a paid enterprise edition distils the model into an MLP or tree ensemble.
- Who is it for?
- Take TabPFN when your data is tabular, your sample count is in the low thousands, and you have a GPU with about 8 GB of VRAM, because that is the shape the local path is built for. Leave it if you need a commercial licence for the weights, since TabPFN-2.5, TabPFN-2.6, TabPFN-3 and TabPFN-3.5 are released under non-commercial licences and the code licence does not extend to them.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
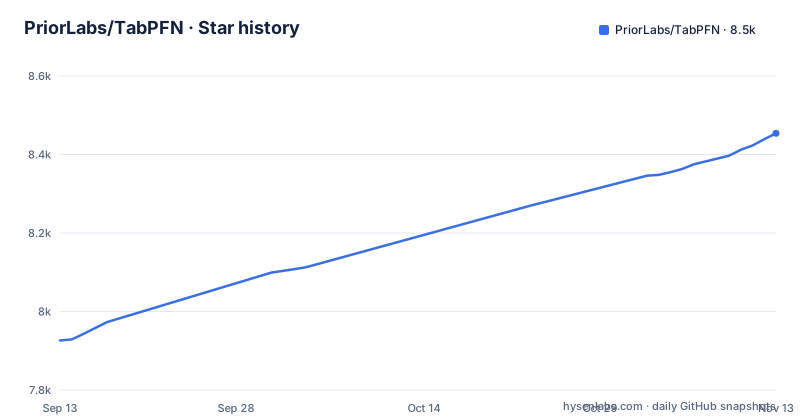
- PriorLabs/TabPFN8,454 ★ · +528
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| PriorLabs/TabPFN | 7.9k | 8.5k |
528 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Apache 2.0 covers the code and nothing else
The licence section is the most important paragraph in this README, and it is easy to skim past because the repository has a LICENSE file and a pyproject.toml licence field that says Apache-2.0.
Those are true of the code. Third-party code inside the tree is subject to its own licences and attribution requirements, with a pointer to Third-Party Notices. Then there is a single sentence that changes everything: model weights are licensed separately.
The current weights are not open source. The README states that the TabPFN-2.5, TabPFN-2.6, TabPFN-3 and TabPFN-3.5 model weights are released under non-commercial licenses, and that TabPFN-3.5 is used by default. So the model you get with no arguments after pip install is one you may not put behind a commercial service.
The v2 weights are different again, under what the README calls the Prior Labs License, described as Apache 2.0 with an additional attribution requirement. You select them explicitly:
tabpfn_v2 = TabPFNRegressor.create_default_for_version(ModelVersion.V2)So there are three regimes to hold in your head: open code, non-commercial current weights, and older weights that are Apache with attribution.
5000 samples on CPU, 1000 on older versions
The install section has a callout about hardware, and it contains the hard limit on local use.
The recommendation is a GPU, with the note that even older ones with around 8 GB of VRAM work well, and that 16 GB is needed for some large datasets. Then the CPU case: only moderate datasets are feasible. TabPFN-3, TabPFN-3.5 and TabPFN-3.5-Fast allow up to 5000 samples. Older versions allow up to 1000.
That is a sample ceiling rather than a time estimate, which makes it unusually useful. You can check your row count against it before you install anything, and the answer does not depend on how fast your CPU is.
The third path is to not run it locally at all. If you have no GPU, the README points at free hosted inference through the TabPFN Client, a separate project in the same ecosystem described as a simple API client for cloud-based inference.
So the practical decision is three-way: local on a GPU, local on CPU under a sample ceiling, or hosted through the client.
skrub is capped because its minor releases change transformer behaviour
The dependency list in pyproject.toml carries two comments and one platform marker worth reading.
  # Capped: skrub is pre-1.0 and its minor releases change transformer behavior.
  "skrub>=0.7,<0.11",
A pre-1.0 package whose minor releases change behaviour gets a bounded range rather than a caret. That is the pattern you use when a dependency's own version policy and yours disagree, and it means TabPFN is tracking a specific set of skrub releases rather than accepting whatever is current.
The second comment is an admission of redundancy:
  # For plotting utils; skrub already pulls it in transitively anyway.
  "matplotlib>=3.6.1",
Listing a package you already get transitively, and saying so, is a small honesty that most manifests skip.
The third is a platform marker:
"mlx>=0.29.3; sys_platform == 'darwin' and platform_machine == 'arm64'",which is how Apple Silicon gets its own backend without a separate requirements file. The rest of the list is ordinary for a model library: torch at 2.5 or newer, safetensors, huggingface-hub for the checkpoint, pydantic and pydantic-settings for configuration, filelock, joblib, tqdm, and lightgbm alongside the usual numpy, scipy, pandas and scikit-learn.
One pip install, but PyTorch comes first on AMD and on CPU-only
Installation is one line:
pip install tabpfnTabPFN supports Python 3.10 or later, which matches the requires-python entry in the manifest.
Around that line there are four platform notes, and two of them mean you have to do something first.
On macOS, GPU support is automatically included for Apple Silicon Macs, with a caveat that for best performance you should be using PyTorch 2.13 or newer.
On Linux, Nvidia GPU support is also automatic. For AMD GPUs you install PyTorch with ROCm first:
pip install torch --index-url https://download.pytorch.org/whl/rocm7.2
pip install tabpfn
and for a CPU-only install you install CPU-only PyTorch first, then TabPFN, which the README notes saves disk space if you have no GPU.
On Windows, Nvidia means PyTorch with CUDA first and AMD means PyTorch with ROCm first.
So the rule is consistent: pip install tabpfn is the last step, not the first, unless you are on Nvidia hardware under Linux or on a Mac.
fit downloads the checkpoint, so your first training call is a network call
The basic usage is four lines and one of them has a comment worth reading twice:
clf = TabPFNClassifier()
clf.fit(X_train, y_train)  # downloads checkpoint on first use
predictions = clf.predict(X_test)
The regressor is the same shape. There is no explicit model loading step and no cache configuration in the snippet, so the download happens inside fit, on the first call, in your training step.
That is convenient and it has consequences. It means the first run of a script depends on huggingface-hub being reachable, which the dependency list confirms is how the checkpoint arrives. It means an air-gapped machine needs a prepared cache. And it means a CI job that measures its own duration includes a model download once.
Selecting a different model is a one line change through a constants module:
from tabpfn.constants import ModelVersion

classifier = TabPFNClassifier.create_default_for_version(ModelVersion.V3_5_FAST)
regressor = TabPFNRegressor.create_default_for_version(ModelVersion.V3_5_FAST)
V3_5_FAST is the smaller, faster model. The previous default is V3, and V2 is the older weights under the attribution licence.
The enterprise edition is a distillation engine, sold separately
There is a section on the README called Enterprise and Production, and it is short.
For high-throughput or massive-scale production environments, the project offers an Enterprise Edition with two named capabilities. Fast Inference Mode is described as a proprietary distillation engine that converts TabPFN into a compact MLP or tree ensemble, delivering orders-of-magnitude lower latency for real-time applications. Commercial Support is described as including a Commercial Enterprise License for production use-cases, dedicated integration support, and access to private high-speed inference engines.
The latency claim is the project's own, and the Enterprise section gives no benchmark behind it. But the shape of the offer is informative on its own: a foundation model that must run inference on the training data is expensive at prediction time, and the commercial answer is to throw the model away and ship a distilled approximation.
That is a different product from the one in the repository. Anyone evaluating TabPFN for a latency-sensitive service should treat the local path and the enterprise path as two systems, and the contact address for the second one is a sales mailbox rather than a licence file.
The examples directory says more about scope than the feature list does
The README names three example files, and the repository contains eighteen entries under examples/. The difference between the two lists is where the real scope is.
The three named in the README are the obvious ones: binary classification, multiclass classification and regression. The directory also has batched_classification_cv.py and batched_regression_m4.py.
Then there is tuning. finetune_classifier.py and finetune_regressor.py are separate from prompt_tuning_classifier.py and prompt_tuning_regressor.py, and tabpfn_classifier_with_tuning.py and tabpfn_regressor_with_tuning.py are separate again. So the project treats prompt tuning and fine tuning as distinct techniques with separate examples rather than one option on a flag.
The rest are operational. save_and_load_model.py, sagemaker.py for a managed endpoint, benchmarking_tabpfn.py, plot_regression_distribution.py, and two files with instructive names: input_gradients.py and kv_cache_fast_prediction.py.
Alongside them there is a changelog/ directory, a pre-commit config, a SECURITY.md and a THIRD-PARTY-NOTICES.md that the licence section refers to by name, which is where the third-party attribution story actually lives.
Editorial conclusion
Take TabPFN when your data is tabular, your sample count is in the low thousands, and you have a GPU with about 8 GB of VRAM, because that is the shape the local path is built for. Leave it if you need a commercial licence for the weights, since TabPFN-2.5, TabPFN-2.6, TabPFN-3 and TabPFN-3.5 are released under non-commercial licences and the code licence does not extend to them. Leave it if your dataset is large and you need real-time latency, because the project sells an enterprise edition on the grounds that the local path does not deliver that. Verify three things. Run pip install tabpfn on Python 3.10 or later and confirm the checkpoint download succeeds, since fit downloads on first use and that is a network call inside your training step. Install the correct PyTorch wheel first if you are on AMD or CPU-only, because the README gives separate commands for ROCm and for a CPU-only build. And read the licence section before you plan a release, because the split between Apache 2.0 code and separately licensed weights is the fact that decides whether you can ship.
Frequently asked questions
How much does TabPFN cost?
The code is Apache 2.0 and free. The model weights are licensed separately: TabPFN-2.5, 2.6, 3 and 3.5 are released under non-commercial licenses, and the TabPFN-2 weights are under the Prior Labs License, described as Apache 2.0 with an additional attribution requirement. There is also a paid Enterprise Edition with a commercial license for production use.
What is TabPFN 3?
One of the model versions you can select. The default is TabPFN-3.5, the smaller and faster TabPFN-3.5-Fast is selected with ModelVersion.V3_5_FAST, the previous default TabPFN-3 is selected with ModelVersion.V3, and the older v2 weights are selected with ModelVersion.V2 through create_default_for_version.
how to install tabpfn
pip install tabpfn, which requires Python 3.10 or later. On AMD GPUs you install PyTorch with ROCm first, for example pip install torch --index-url https://download.pytorch.org/whl/rocm7.2, then install TabPFN. A CPU-only install follows the same order with a CPU-only PyTorch wheel, which the README says saves disk space if you have no GPU.
is tabpfn free
The code is, under Apache 2.0. The default TabPFN-3.5 weights are not: the README states that model weights are licensed separately and that TabPFN-2.5, 2.6, 3 and 3.5 are under non-commercial licenses. If you have no GPU, the project also points at free hosted inference through the TabPFN Client.
is tabpfn a foundation model
That is how the project describes it. The package description reads Foundation model for tabular data, the README is organised around choosing a model version through a constants module, and the checkpoint is downloaded on first use by fit. The dependencies include torch>=2.5 and safetensors, and the PyPI distribution is named tabpfn.
what does tabpfn stand for
The repository description reads TabPFN: Foundation Model for Tabular Data, and the README frames the project the same way. The PyPI distribution is simply named tabpfn.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 2 in the last 30 days; newest first.
- On 21 Nov 2024 Adani fell 22.61%. My model didn't know why, and it wasn't allowed to guess.dev.to · Nov 1, 2026 · 2 points · 2 comments
- I let an open model delete 1,242 of my saved articles. On purpose. I feel lighter.dev.to · Oct 23, 2026 · 27 points · 21 comments
- I Built an Open-Weight AI That Prices Etsy Shops, On Your Laptopdev.to · Oct 15, 2026 · 20 points · 0 comments
- Frostline: what to plant this week, from your local frost datesdev.to · Oct 10, 2026 · 2 points · 0 comments
- I built an offline AI that knows your last frost date, no internet, no APIdev.to · Oct 9, 2026 · 16 points · 2 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/priorlabs-tabpfn)Star history chart for your README
[](https://hysenlabs.com/projects/priorlabs-tabpfn)Was this useful?