PenguinHarness types itself against a generated file, and every push publishes an image
🐧 Harness for RSI. Let AI Build AI. Multi-Agent Auto-Dev Platform. Everything is Transparent.
At a glance
- What is it?
- A local-first platform whose pitch is that agents should build agents, backed by cost comparisons that live in an image rather than in the page text. The build is unusually well argued: three container stages split by which machine has to run them, and an image published per commit including unreleased ones.
- Who is it for?
- PenguinHarness fits someone who wants agent development to run locally, who wants to watch an agent improve itself against a benchmark, and who reads the trace view rather than trusting the score. Three things to weigh.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
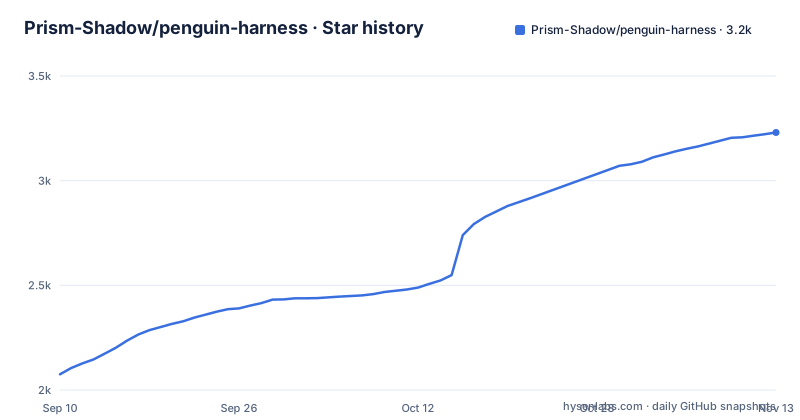
Star history
- Prism-Shadow/penguin-harness3,230 ★ · +1,155
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| Prism-Shadow/penguin-harness | 2.1k | 3.2k |
1,155 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The speed claim is a ratio and the evidence is a picture
The positioning is a single comparison: building agents by hand is put at one times speed, and the same page puts agents building agents at a hundred times. A hundred times is a memorable multiplier, and the supporting paragraph explains the mechanism as a deliberately small toolset over clean low level interfaces, producing fewer tool calls and fewer tokens, with the tuning aimed at open models. Then the specific claim: best accuracy on data analysis at one seventieth of the cost of a competing coding tool, on the same tasks, run head to head on the model each is normally paired with. The problem is where the numbers live. The benchmark is a picture, referenced through a dark mode image asset, so the accuracies and the costs are not in the page text and cannot be read, checked or copied from it. A reader who wants to verify the comparison has to open the image or find the page it belongs to.
The self-evolution loop is bounded by a snapshot and a trace view
This is the feature the repository description leads with, and the mechanism is stated in one sentence.
run the benchmark, find the lost points, ship version N+1An agent runs its own evaluation, works out where it lost points, and ships the next version of itself. Two details make that claim more than a slogan. A snapshot is taken before every round, so there is always a state to return to if a round makes things worse. And every request is observable in a trace view, so a change in behaviour can be attributed to a specific round rather than guessed at. The plugin table supports the same idea from the other direction: alongside the skills there are session hooks that drive goal mode and continual learning, and the page states that agents can write and optimise their own skills as well as use them. The plugin categories are four, with named plugins in each, including one for model tuning and one for porting skills.
Nine built-in presets, and a thousand models behind a custom endpoint
The header advertises a thousand models, and the table underneath lists nine families.
Each family's latest generation onlyFor each of the nine there is a row of providers, several of which are aggregators rather than the model's own host, so one preset is reachable through three or four different billing relationships. The count in the header is not the preset count. It comes from the sentence after the table: any endpoint speaking the OpenAI protocol also works, so you can point a custom endpoint at any of the thousand or more online and local models. That is a genuinely different claim from the one the badge makes, and it is worth separating them, because a preset carries a curated tool set and a model name while a custom endpoint carries only the protocol. The requirements table adds the practical floor: an operating system, an architecture, and an API key for at least one model.
Two ports, one for a development run and one for the image
The development entry point is a wrapper script rather than a command, and the reason is that it needs three environment variables before anything runs.
PENGUIN_HOME=~/.penguin/dev-data-cli PENGUIN_PROFILE=dev PORT=7369So a development run gets its own data directory, its own profile name to keep it separate from real data, and a port. That port is 7369, while the container image documents the server running on 7364. Two ports for the same program, one for a developer's local instance and one for the shipped image, and nothing on the page says so. It is the kind of split that is invisible until two things collide, at which point the profile variable and the data directory are what tell you which instance you are talking to. The image also takes the loopback bind in its own run example, so a local container exposes its port on one interface only.
Typechecking cannot run until an interface file has been generated
This is the detail that tells you how the repository is wired, and it is in the script list rather than in the prose.
"gen:ifaces": "node scripts/gen-ifaces.mjs --project packages/server/tsconfig.json --out packages/server/src/ifaces.json"So a script walks the server package's TypeScript configuration and writes a single JSON file of interfaces into the server source tree. Two other scripts then depend on that file. The typecheck script generates it before typechecking anything, which means the build has a generation step that is not optional and not covered by a watch mode, and a second script turns the same generated file into a documentation page. One artefact feeding both the compiler and a page is a tidy arrangement, and it also means the checked-in version of that file is either authoritative or stale, with nothing in the script list saying which.
Three stages split by which machine each one has to run on
The container file is the best documented build script in the repository, because it argues each choice instead of asserting it. The three stages are split by machine rather than by concern.
# `build` is pinned to the BUILD platform.
# `native` runs on the TARGET platform
# - the runtime stage copies the result and never installs a compiler.
The reasoning is that a TypeScript and bundler toolchain emits the same bytes anywhere, so running a full workspace install and build under emulation for the arm64 leg would cost minutes and buy nothing. Exactly one thing is architecture specific, a terminal multiplexer binding with a C++ extension that publishes for desktop platforms and therefore compiles on every Linux install, and it is the only compiled dependency in the shipped tree. The base image is a Linux distribution rather than the vendor's own runtime images, and the stated reason is that it matches what the continuous integration runners use, so a native binding compiles against the same C library every release artefact was built on. And because nothing is installed from a package registry at runtime, an image can carry an unreleased commit, which is how every push to the main branch publishes one.
The package, the image and the organisation have three different names
Nothing about this repository is confusing, but the names are spread across three identities. The root manifest is named for the project, is marked private so it is never published, and requires a very recent runtime. What is published to the package registry is a scoped package under a different name, while the container image is published to a personal account rather than to the organisation, and the social account in the readme is that same personal handle. So a user finds the code under one organisation, the library under a scope, and the image under a person.
Two smaller things are visible in the tree. One entry whose name is a dot directory for an assistant has no trailing slash while the neighbouring one has, which means the first is a file and the second a directory. And there are four places changelog information lives, two root files including a Chinese one, a directory of its own, and the version string in the manifest. The readme also exists in two languages with a parallel set of translated images, and there are three separate installers, one shell script and two for Windows, alongside a Dockerfile and a compose setup.
Editorial conclusion
PenguinHarness fits someone who wants agent development to run locally, who wants to watch an agent improve itself against a benchmark, and who reads the trace view rather than trusting the score. Three things to weigh. The headline speed and cost comparisons are the project's own and they live in an image, so there is nothing on the page to check them against. The published library, the container image and the source organisation carry three different names, which matters when you are wiring a dependency or pulling an image. And typechecking depends on a generated interface file, so a fresh checkout that skips generation will not build, and you should decide whether you are tracking the committed copy of that file or regenerating it.
Frequently asked questions
What is PenguinHarness?
An open-source, local-first platform for building agent applications, which it describes as automating the lifecycle from creation and evaluation through optimisation to deployment. Agents can write and optimise their own skills, and it runs on your own machine or server rather than as a hosted service.
What does PenguinHarness need in order to run?
Linux, macOS or Windows 10 or newer on an x64 or arm64 architecture, an API key for at least one model, and the runtime. The one-line installer bundles the runtime, while installing through a package manager needs Node 24 or newer, which is stated in the requirements table.
How does the PenguinHarness self-evolution loop work?
A skill runs the benchmark, identifies where points were lost, and ships the next version. A snapshot is taken before every round and every request is observable in a trace view, which is what makes a regression attributable to a round rather than a mystery.
Which models can I use with PenguinHarness?
Nine built-in presets covering the latest generation of several families, each reachable through one or more providers including aggregators. Any endpoint that speaks the OpenAI protocol also works, which is where the thousand model figure in the header comes from, since it counts what you can point a custom endpoint at rather than the presets.
Can a PenguinHarness agent control my browser?
Two ways. The desktop app has a built-in browser in its side dock that agents drive through a command and a plugin, signed in with accounts you import from your own browser. Or a browser extension drives your own Chrome, limited to the tabs you hand it, with your sign-ins staying in Chrome.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/prism-shadow-penguin-harness)Star history chart for your README
[](https://hysenlabs.com/projects/prism-shadow-penguin-harness)Was this useful?