Pushgateway: a metrics cache for jobs that die before the next scrape, with three stated non-goals
Push acceptor for ephemeral and batch jobs.
At a glance
- What is it?
- The Prometheus Pushgateway accepts pushed metrics on behalf of ephemeral and batch jobs, and Prometheus then scrapes the gateway rather than the jobs. It stores what it is given in groups keyed by labels, does not persist anything unless told to, has no expiry on metrics, and states three things it is not: a push-based monitoring system, a distributed counter, and an event store.
- Who is it for?
- Pushgateway suits a batch job that finishes in minutes, where a scrape interval is longer than the job's life, and where the job can be rewritten to push at the end instead of exporting for scraping. It does not suit long-running services, which should be scraped directly, machine-level metrics, which the Node exporter textfile collector handles, distributed counting, which needs real statsd semantics, or anything that assumes pushed values disappear on their own.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 14 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
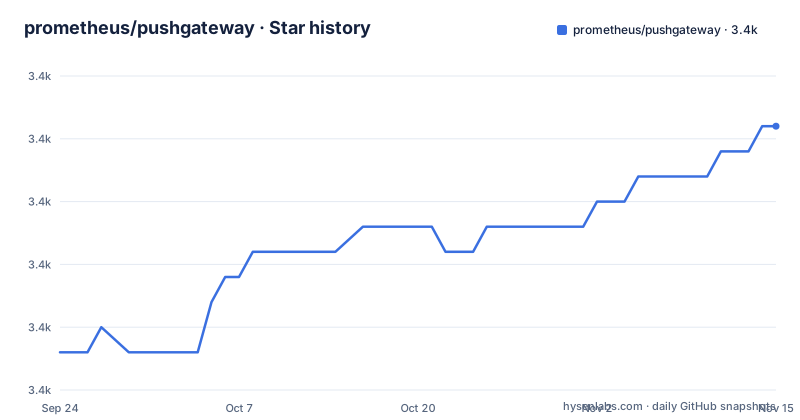
Star history
- prometheus/pushgateway3,378 ★ · +9
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| prometheus/pushgateway | 3.4k | 3.4k |
9 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A cache for jobs that are gone before the next scrape
Prometheus is a scraper, and the Pushgateway exists for the case where the thing producing metrics is too short lived to be scraped at all. Batch jobs, and jobs that run once and exit, fit that description: they can push their metrics to the gateway instead, and the gateway exposes them so Prometheus can scrape it in the normal way. The direction of data flow is the part worth being precise about, because the project is explicit that this does not turn Prometheus into a push-based monitoring system. Prometheus still polls. What changes is the address it polls, which means the gateway inherits the scrape interval as its update frequency, and a value pushed at the end of a job is not visible to Prometheus until the next scrape of the gateway. For a general description of when this is the right shape to reach for, the project links to a practices page on pushing to Prometheus, which is worth reading before a gateway goes into a scrape config.
Three non-goals, and the alternatives named for each
The section that should change your mind about whether this tool fits is the one listing what it is not. First, it is not an aggregator or a distributed counter, and it explicitly does not have statsd-like semantics; the metrics you push are exactly the metrics you would have exposed for scraping from a permanently running program. For real distributed counting the project points at actual statsd used with the Prometheus statsd exporter, or at a separate aggregation gateway, and notes that the Prometheus project may one day offer a native solution. Second, for machine-level metrics it points at the textfile collector of the Node exporter as the more appropriate tool, because the gateway is intended for service-level metrics. Third, it is not an event store: release events and similar things belong in an event-logging framework, even though Prometheus can feed Grafana annotations.
No timeout on pushed metrics, on purpose
The most consequential design decision is the absence of one. A timeout or time to live for pushed metrics was considered and deliberately not implemented, because nearly every proposed use case turned out to be an anti-pattern the project discourages. The reasoning thread is public on the pushgateway issue about it and on the Prometheus developers mailing list. The operational consequence is easy to state and easy to trip over: a group you push once stays there. Nothing ages out, nothing is refreshed by a later push unless you push the same group again, and the value on disk is whatever the last push left behind. That makes deletion a first-class operation rather than a cleanup chore, which is why the documentation spends space on the delete endpoints and why the ability to wipe everything is gated behind a command line flag.
Groups are keyed by labels, and job has to come first
Pushed metrics are held in groups, and a group is identified by a grouping key made of any number of labels, with one rule: the first label has to be job. The key appears directly in the URL, which is why the documentation warns about special characters in label values, and it is also why the delete examples are worth reading closely. Deleting the group identified by a job and an instance pair is a DELETE on that path; deleting the group identified by the job alone is a different path and explicitly does not remove the metrics in the instance subgroup, even when those metrics carry the same job label. So a mis-shaped deletion can leave data behind that looks like it should have gone. The groups are also inspectable through the gateway's own web interface, which is the quickest way to see what a job has actually pushed. The documentation also flags that special characters in label values have implications for the URL, and defers the details to a later section on URL formatting, which is the part to read before scripting anything against the push path.
The text protocol, and the single character that breaks it
There is no separate command line client, because pushing is an HTTP request carrying the text exposition format. The documentation is unusually firm about one detail: every line has to end with a line feed character, and ending a line with a carriage return, with a carriage return and line feed pair, or at the end of the packet results in a protocol error. The simplest example pipes a metric straight in:
echo "some_metric 3.14" | curl --data-binary @- http://pushgateway.example.org:9091/metrics/job/some_jobWith no type information supplied, that metric is stored as untyped. For anything more than one sample the documentation shows type and help lines being included, and calls them optional but strongly encouraged:
# TYPE some_metric counter
some_metric{label="val1"} 42
# TYPE another_metric gauge
# HELP another_metric Just an example.
another_metric 2398.283
Windows users get their own example, because a PowerShell request has to end the body with a back tick and the letter n rather than a real line feed.
Nothing is written to disk and the wipe endpoint is disabled by default
Two defaults matter for anyone deploying this. The first is persistence: by default the gateway keeps pushed metrics in memory only, and the flag that changes that names a file to write them to so they survive a restart of the gateway itself. The second is the admin interface, which is off until the enable admin API flag is passed, and which is what gates the endpoint that deletes every metric in every group at once:
curl -X PUT http://pushgateway.example.org:9091/api/v1/admin/wipeThe listen address is the third flag the documentation mentions, with examples given for binding to all interfaces or to a port only, on the default port 9091. That last detail is also why the container images expose 9091. Note the verbs: the push examples use POST through the data flag of curl, group removal uses DELETE, and the administrative wipe uses PUT. Releases come as tarballs per platform with the version kept in a file in the repository root, and the published history is unhurried: 1.11.1 in April 2025, 1.11.2 in October 2025, 1.11.3 in May 2026.
Five container architectures, a busybox base, and an embedded web interface
The build files show how little the binary needs. The container image starts from a busybox base image for the target operating system and architecture, copies in a single prebuilt binary, exposes port 9091, and runs it as an unprivileged numeric user with nobody as the owner, so there is no shell and no package manager in the image. The Makefile defaults the build to five architectures, amd64, armv7, arm64, ppc64le and s390x, and includes a shared Makefile that the rest of the Prometheus projects also use. The web interface and other static files are not served from disk: they are generated into Go source and embedded in the binary. The module's own dependency list explains the rest, with a command line parser for the flags, a compression library, the Prometheus client library and its data model, the shared configuration library, and the exporter toolkit that provides the web layer. The repository layout follows the same shape as the code it serves, with separate directories for the API surface, the request handlers, the storage layer and a histogram package, an asset directory that gets code generated into the binary, and a test utilities directory that downstream projects import. Alongside them sit the files a Prometheus project usually carries: a release configuration, lint and YAML lint settings, a shared Makefile, a second Dockerfile for a distroless base, a container README, and the usual maintainers, security, notice and licence documents.
Editorial conclusion
Pushgateway suits a batch job that finishes in minutes, where a scrape interval is longer than the job's life, and where the job can be rewritten to push at the end instead of exporting for scraping. It does not suit long-running services, which should be scraped directly, machine-level metrics, which the Node exporter textfile collector handles, distributed counting, which needs real statsd semantics, or anything that assumes pushed values disappear on their own. Three things to check before deploying it: whether your Prometheus scrape config sets honor_labels, which the documentation says you should always do for a gateway target and which changes which labels win; whether you accept that a group of metrics stays until something deletes it, since there is no timeout and no expiry by design; and whether you need the metrics to survive a restart, because nothing is written to disk unless the persistence flag names a file.
Frequently asked questions
what is pushgateway
The Prometheus Pushgateway is a metrics cache that lets ephemeral and batch jobs push their metrics to it, so Prometheus can scrape the gateway instead of the job. It is not a push-based monitoring system, not an aggregator or distributed counter, and not an event store, and it is intended for service-level metrics rather than machine-level ones.
how to install prometheus pushgateway
Download the binary for your platform from the release page and unpack the tarball, or compile from source with a working Go setup by typing make. There is also an official image: docker pull prom/pushgateway, then docker run -d -p 9091:9091 prom/pushgateway.
how to use prometheus pushgateway
Configure the gateway as a scrape target in Prometheus and set honor_labels: true in the scrape config, which the documentation says you should always do. Then push metrics over HTTP in the Prometheus text format, where every line must end with a line feed character, grouping them under a key whose first label is job.
pushgateway alternatives
For distributed counting the project points at real statsd used with the Prometheus statsd exporter, or at a separate aggregation gateway, because the Pushgateway has no statsd-like semantics. For machine-level metrics it points at the Node exporter textfile collector, and for tracking events it points at an event-logging framework.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/prometheus-pushgateway)Star history chart for your README
[](https://hysenlabs.com/projects/prometheus-pushgateway)Was this useful?