The agent systems handbook offers four paths and no required order
A practical AI agents handbook covering agent systems, agentic workflows, LangGraph, MCP/A2A, context engineering, agent memory, evaluation, observability, and multi-agent architecture. Current trend focus: Gemini Interactions API and managed agents, emerging agent runtimes, and production AI workflow patterns.
At a glance
- What is it?
- The Agent Systems Handbook by Prompthon is a documentation repository rather than a library: content is organised into topical lanes, and readers are routed through one of four parallel paths depending on whether they want to understand the field, apply it, build with it, or contribute to it. Its most unusual feature is disclosed in its own overview.
- Who is it for?
- The handbook suits a reader who needs to know what sits around an agent before choosing a framework, since the coverage list is organised by capability rather than by product and the interoperability material sits alongside the memory and context material. It does not suit someone looking for runnable code to adopt, since the repository ships prose and examples as documentation.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 28 days ago.
- What is it written in?
- Mainly MDX, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
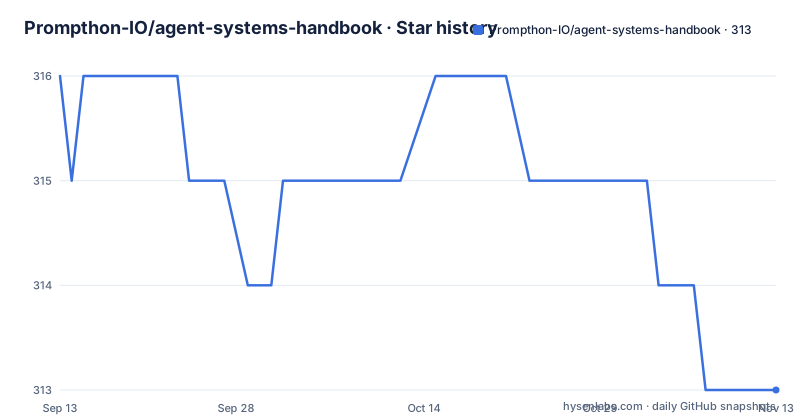
- Prompthon-IO/agent-systems-handbook313 ★ · -3
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| Prompthon-IO/agent-systems-handbook | 316 | 313 |
-3 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four reading paths with no required order
The start-here section is a table of four cards, and the sentence above it sets the rule.
These are parallel tracks for different types of learners and builders, not a required sequence. That is an unusual thing to state explicitly, and it matters because the same material is being organised for four different intentions rather than linearised into a course.
The first path is for students, newcomers, and curious readers who want a broad view of the field, the trends, and the foundational ideas without becoming engineers. What it delivers is a curated set of high-signal reads.
The second is for people who want to use AI tools and workflows in daily life, study, and work without becoming full-time engineers, and it explicitly includes one-person-company style cases where AI expands what a single person can do.
The third is for engineering-minded learners and developers, going from agent applications and workflows through to startup-style products and technically deeper implementations.
The fourth is not a learning path at all. It is for people who want to shape the handbook itself, by adding, revising, curating, or maintaining pages and examples, and it delivers the editorial workflow, templates, review rules, and placement standards.
Each card links to its own guide under a reading-paths directory.
Content lives in lanes and the contributor guide sets placement
The repository root is a set of topical directories, and the contributor guide is what turns them into a filing system.
The instruction is to start from the contributor documentation rather than from ad hoc internal working material, and then six kinds of contribution are listed.
Lab articles go into one of five lanes: foundations, patterns, systems, ecosystem, or case studies. Trend notes go into a radar directory. Source projects go into example folders local to their lane. Practitioner skill packages go into a skills directory with its own index. Curated reference notes go into a reference-notes directory inside a contributor kit. And publication extensions go into a publications directory, but only once a lab page is ready to become an outward-facing article.
That last condition is a sequencing rule rather than a location rule, and it is the only one of the six with a precondition.
The placement standards being a named artefact is itself notable. Most content repositories let a reviewer decide where a page goes after reading it; here the decision is documented before submission, which is what makes a large multi-contributor handbook coherent rather than a pile of unrelated notes.
Lane-local example folders are described but do not appear in the tree
One of the six contribution paths has no visible counterpart in the repository listing.
Source projects are supposed to go into example folders local to their lane. The lanes are named in the same guide, and the five article lanes are all present at the root. There is no examples directory at the root, and none of the visible lane directories suggests a nested one.
So either the example folders exist inside lanes in a way the top-level listing does not show, or the convention is documented ahead of the first contribution following it.
Either way, it is the kind of gap worth resolving before writing code for this handbook. A contributor who follows the rule literally has no template to copy and no working example to point at.
The same section has a second soft spot. Publication extensions are conditional on a lab page being ready, and the readiness criteria are not stated anywhere in the visible documentation, so the threshold is defined by the review process rather than by a rule.
The handbook says it was drafted with AI and reviewed by people
One of the five reasons given for why the handbook fits its audience is called being AI-native by design.
The sentence describes the content being created through an AI-native workflow that combines AI-assisted drafting, synthesis, iteration, and refinement with expert guidance and review.
That is a disclosure rather than a boast, and it is unusual to see in a project README. Most published material does not describe its own production method, and the ones that do usually do so to claim a benefit.
The other four reasons frame the same project from different angles: it is built on learning, questioning, and innovating rather than passive consumption; many contributors are learners themselves, which keeps the material close to the questions students and new graduates actually have; it is guided by real industry practice through the lab's programs and industry-facing guidance; and it is designed for different paths rather than a single track.
Read together, the five reasons amount to a quality argument: written by people at the stage of learning, shaped by working practice, and produced with tooling whose output a human reviewed.
Coverage is listed by capability and interoperability gets one bullet
The contents list is seven bullets, and reading them in order gives the table of contents of a field guide rather than of a framework.
Foundations and mental models come first, followed by agentic workflows with planning, reflection, tool use, and function calling named explicitly.
Then memory, retrieval, context engineering, and retrieval-augmented generation. Then interoperability: MCP, A2A, protocol interoperability, and what the documentation calls agent communication boundaries.
Frameworks come next, and the list is broader than the one the repository description leads with: LangGraph, agent frameworks generally, hosted builders, and low-code platforms.
Multi-agent orchestration follows, then a bullet that puts evaluation, observability, reliability, and safety in one line. The last bullet is the practical one, naming deep research agents, customer-support agents, source projects, and starter examples.
Two things are worth noting about that structure. Interoperability is treated as a first-class concern rather than an appendix, which is unusual for material whose headline framework is one specific library. And the project description adds a trend focus that the contents list does not mention, naming a specific interactions API, managed agents, and emerging runtimes.
A docs site with a second config, custom hooks, and a Chinese tree
The file listing shows a documentation project rather than a software package, and the tools match.
There is a docs configuration file, a page-index file in the MDX dialect the content is written in, and a separate document describing the website itself. An ignore file names a specific documentation tool, which is the clearest signal of what renders the site.
Node is pinned twice, once in a version file and once in a file read by the version manager. That is normally a duplication to avoid, and here it is at least consistent.
Two entries are worth a second look. A git hooks directory means the repository installs its own hooks rather than relying on a server-side check alone. And a directory whose name is a language tag means there is a Simplified Chinese version of the whole handbook, not just a subset.
That translation track is the most expensive commitment in the list. A handbook with dated trend notes and a weekly release cadence needs someone to keep two languages in step, and the contributor guide says nothing about which language a contribution should arrive in.
Releases are named for the day they were cut
The release tags are dates.
Three of them are visible, each carrying a date and a sequence number: one from late September, one from mid-September, and one from the start of September. Each lands on a different day and each has a suffix of one.
That is a sensible scheme for a documentation repository, where the unit of release is a batch of page changes rather than an artifact someone depends on. The tags also make it easy to ask what changed between two readings of the site.
The cadence implied is roughly weekly, which for trend-tracking material is a reasonable rhythm: fast enough to stay current, slow enough that a reader can catch up.
Two smaller observations. The project description names a current trend focus explicitly, including one vendor's interface and the phrase emerging runtimes, which is a signal that content is expected to change as the market moves rather than to be a fixed text. And the repository metadata reports no resolved licence while a licence file sits at the root, so anyone checking terms should read the file.
Editorial conclusion
The handbook suits a reader who needs to know what sits around an agent before choosing a framework, since the coverage list is organised by capability rather than by product and the interoperability material sits alongside the memory and context material. It does not suit someone looking for runnable code to adopt, since the repository ships prose and examples as documentation. Before you plan study time around it, pick a path first, because the four are explicitly parallel, and read the placement rules before contributing, since where a page lands is decided before its content is reviewed.
Frequently asked questions
What are the main components of an agent system?
The handbook frames them as: foundations and mental models; agentic workflows with planning, reflection, tool use, and function calling; memory, retrieval, context engineering, and agentic RAG; MCP, A2A, and protocol interoperability; frameworks such as LangGraph plus hosted builders and low-code platforms; multi-agent orchestration; and evaluation, observability, reliability, and safety.
What is A2A and MCP?
The handbook covers both under one heading, alongside protocol interoperability and what it calls agent communication boundaries, with a separate section on agent frameworks and hosted builders. The overview does not define either acronym, so the definitions live in the pages rather than in the project description.
Which reading path should I start with in the agent systems handbook?
Pick by intention, since the four paths are explicitly parallel rather than sequential: Explorer for a broad non-engineering view, Practitioner for applying AI tools to work and study including one-person-company cases, Builder for engineering depth from applications to products, and Contributor for shaping the handbook's own pages and examples.
Where do contributions to the agent systems handbook go?
Into one of six paths: lab articles under foundations, patterns, systems, ecosystem, or case studies; radar notes; lane-local example projects; practitioner skill packages; curated reference notes in the contributor kit; or publication extensions once a lab page is ready. The guide says to start from the contributor docs rather than ad hoc internal material.
How is the agent systems handbook published and localized?
As a documentation site, with a docs configuration, a page index, and a separate website document, plus a directory for git hooks and scripts. It ships a Simplified Chinese tree alongside the English content, pins its Node version in two files, and cuts date-named releases roughly weekly.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/prompthon-io-agent-systems-handbook)Star history chart for your README
[](https://hysenlabs.com/projects/prompthon-io-agent-systems-handbook)Was this useful?