How pybind11 infers types at compile time, and what its CI does not cover
Seamless operability between C++11 and Python
At a glance
- What is it?
- pybind11 is a header-only C++ library that exposes existing C++ types to Python, written as a stripped-down answer to Boost.Python. Every binding decision is made while your module compiles, which moves the cost from linking into compile time and leaves toolchain support resting on a matrix nobody promises is complete.
- Who is it for?
- Take pybind11 when you already have C++ to wrap and want the binding code to shrink, and expect to own two things the project will not cover for you: whether your exact compiler and Python build sit inside the tested matrix, and whether your NumPy version is new enough. Boost.Python users get the same goals and syntax with the old compiler workarounds removed.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
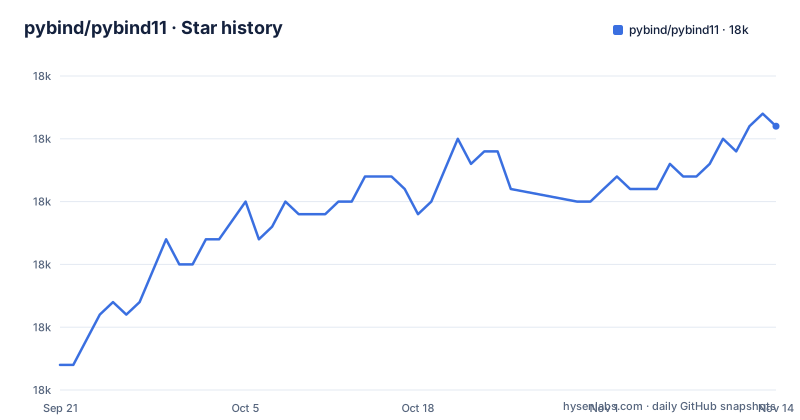
- pybind/pybind1118,031 ★ · +19
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| pybind/pybind11 | 18k | 18k |
19 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Boost.Python with the oldest-compiler workarounds removed
The project's own framing is subtraction. Its goals and syntax are similar to Boost.Python's: infer type information with compile-time introspection to cut the boilerplate in traditional extension modules. The difference it names is what had to be kept to support Boost itself, a suite that works with almost every C++ compiler in existence and pays for that with template tricks and workarounds aimed at the oldest and buggiest compiler specimens. Now that C++11 compilers are widely available, that machinery becomes an excessively large and unnecessary dependency, in the project's own words.
What remains is small enough to state. Without comments, the core header files need roughly 4K lines of code, and they depend on Python (CPython 3.9+, PyPy, or GraalPy) plus the C++ standard library. No further library to link against, because everything sits in a few headers.
The compact shape is a consequence of choosing C++11 as the floor. Tuples, lambda functions and variadic templates are named as the features that made it possible. Take the floor seriously: the C++ standard your extension needs to compile is the standard pybind11 itself is written in, so a host project pinned to an older dialect cannot use it without moving first.
Type information is inferred while the module compiles, not when it imports
There is no runtime registry to configure and no manual type table to fill in. Type information comes out of compile-time introspection, which is the mechanism behind the small core header count. Function signatures are precomputed at compile time using constexpr, and that is credited with the smaller binaries rather than with faster dispatch.
Two more choices follow from the same idea. pybind11 uses C++11 move constructors and move assignment operators wherever possible to hand custom data types over, and the feature list covers the cases that usually need hand-written glue: overloaded functions, single and multiple inheritance, arbitrary exception types, enumerations, callbacks, iterators and ranges, STL data structures, and classes with virtual or pure virtual methods that can be extended from Python.
The consequence for a reader is where the cost sits. A header-only binding layer is compiled into your extension module, so build time is the bill you pay and the compiler is the thing that reports your mistakes. Errors in a binding show up as compile errors inside template instantiation, which is a noisier place to debug than a Python traceback, and it is why the header count matters less to your build than the size of the translation unit that includes it.
The build backend is scikit-build-core, and the working setups live in sibling repositories
The packaging metadata is where the build story is. pyproject.toml at the repository root names the build system, and it is not setuptools:
[build-system]
requires = ["scikit-build-core >=0.11.2"]
build-backend = "scikit_build_core.build"
The same file sets the interpreter floor, which matches the supported list in the README:
requires-python = ">=3.9"And it declares a command, both as a console script and as something pipx can run on demand:
[project.scripts]
pybind11-config = "pybind11.__main__:main"

[project.entry-points."pipx.run"]
pybind11 = "pybind11.__main__:main"
For a setup you can copy rather than assemble, three sibling repositories are offered: pybind/python_example, pybind/scikit_build_example and pybind/cmake_example. Distribution runs through PyPI and Conda-forge, the two package channels in the badge row. The root also holds CMakeLists.txt and CMakePresets.json, which is what a CMake-based consumer of the headers will actually touch.
A bound lambda carries its captures inside the Python function object
C++11 lambdas with captured variables can be bound, and the README is specific about where the captured data ends up: stored inside the resulting Python function object. That placement is the whole lifetime story. While Python holds the function, the captured state stays alive, and when the last reference to that function goes away the captured state goes with it. Nothing extra has to be tracked on the C++ side, which is convenient for callbacks that would otherwise need a lifetime manager.
The same instinct runs through the reference-counting features. Smart pointers such as std::shared_ptr map over, and the feature list claims internal references with correct reference counting. What is not in that list is a policy for objects you hand out by raw pointer, so a binding that stores a pointer to something owned elsewhere keeps relying on your own ownership decisions at every call site.
Callbacks and iterators are both listed as supported, which means the C++ side can call back into Python and Python can drive a C++ sequence. Neither entry says what happens to a callback that fires after the owning object is gone, so a long-lived callback registered from Python needs the same lifetime care as a raw pointer, and the header-only convenience does not remove that question.
NumPy support arrives as buffers, vectorized calls, and a version floor
Three separate mechanisms cover the array case. Buffer protocol support exposes the internal storage of custom data types, which is the route for fast conversion between C++ matrix classes such as Eigen and NumPy without expensive copy operations. Separately, pybind11 can automatically vectorize functions so they are applied transparently to all entries of one or more NumPy array arguments. Built-in NumPy support is described as integrated, with one explicit floor attached to it: NumPy 2 requires pybind11 2.12 or newer.
That version floor is the practical trap. It names a specific pybind11 release, so a project pinned below 2.12 has no NumPy 2 support until it moves to at least that release. Check it before a NumPy 2 upgrade reaches your build, not after.
The copy behaviour is the other thing worth pinning down for yourself. Whether a given call copies depends on whether you bound it against a buffer or a value, and the feature list advertises both routes. If zero-copy matters for your arrays, verify per binding which one you actually got.
The CI matrix cannot promise your compiler is in it
pybind11 is exercised in continuous integration across operating systems, Python versions, C++ standards and toolchains, and the current combinations are visible in the GitHub Actions and AppVeyor logs. The documentation also says plainly what that does not mean. The matrix evolves as older platforms fall out of use and new ones arrive from the community, closely related versions of a tested compiler often work in practice, and the project cannot promise to validate every possible combination.
The reason is stated as well: the size of the test matrix has to be balanced against available CI resources, with GitHub's limits on concurrent jobs under the free tier named as an example. So coverage is a deliberate trade, made by people who can spend their own time on it, against a field of compiler and platform combinations that grows on its own.
For an adopter the consequence is plain. If your configuration is missing from the matrix, or it regresses, you have a bug you own until someone upstream takes an interest. Issues and pull requests extending coverage are welcome in exactly that case, which tells you the cost lands on whoever files them. An untested toolchain is workable; it just has to be tested by you.
The 5.4x size claim comes from one 2016 conversion of PyRosetta
The headline numbers need their source attached. Binaries are described as generally smaller by a factor of at least two compared with equivalent Boost.Python bindings, and the specific figures quoted are a pybind11 conversion of PyRosetta, an enormous Boost.Python binding project, which reported a 5.4x binary size reduction and a 5.8x compile time reduction. That report is a conference slide deck from 2016, linked from the project page.
One data point is not a ratio you can plan against. It is evidence that a large conversion improved, not a guarantee for the module you are about to write, and the number most likely to matter to you is compile time on your own codebase rather than binary size on someone else's. The project also says it has grown beyond Boost.Python in many ways since its creation; that is the maintainers' claim about scope, and the feature list is where you can check it against your own requirements.
On maintenance, the licence is the BSD-style LICENSE file at the root, and pyproject.toml names it as BSD-3-Clause with the version and optional dependencies left dynamic. Releases v3.1.0, v3.0.4 and v3.0.3 shipped in 2026, and the last push to the repository was on 2026-11-01, so the v3 line is where current work is happening.
Editorial conclusion
Take pybind11 when you already have C++ to wrap and want the binding code to shrink, and expect to own two things the project will not cover for you: whether your exact compiler and Python build sit inside the tested matrix, and whether your NumPy version is new enough. Boost.Python users get the same goals and syntax with the old compiler workarounds removed. Before you commit, check the CI matrix on the master branch for your toolchain, and pin NumPy 2 work to pybind11 2.12 or newer, because the README ties that support to a version floor rather than to the v3 line.
Frequently asked questions
What is pybind11 used for?
It exposes C++ types in Python and vice versa, mainly to create Python bindings of existing C++ code. It maps functions, classes with virtual methods, enumerations, callbacks, iterators, STL containers, smart pointers and NumPy arrays to Python.
Is pybind11 header only?
Yes. Everything is contained in just a few header files, and there is no need to link against any additional libraries. The core headers are around 4K lines of code without comments.
How do I install pybind11?
pybind11 is published through PyPI and Conda-forge, the package channels in the README's badge row. Its own pyproject.toml builds with the scikit-build-core backend (scikit-build-core >=0.11.2) and requires Python >=3.9, and complete project setups live in the pybind/python_example, pybind/scikit_build_example and pybind/cmake_example repositories.
How does pybind11 work?
It infers type information using compile-time introspection rather than a hand-written type table, and precomputes function signatures at compile time with constexpr. The core headers depend on Python (CPython 3.9+, PyPy, or GraalPy) and the C++ standard library only.
Which is better, pybind11 or nanobind?
The README's introduction positions pybind11 against Boost.Python, matching its goals and syntax while dropping what is not needed for binding generation, and covers the C++11 language features that made the smaller implementation possible.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pybind-pybind11)Star history chart for your README
[](https://hysenlabs.com/projects/pybind-pybind11)Was this useful?